PRISM manual latest
PRISM is a probabilistic model checker, a tool for the modelling and analysis of systems that exhibit random or uncertain behaviour. Probabilistic model checking is a formal verification technique: you build a precise mathematical model of the system to be analysed, express its properties formally in temporal logic, and PRISM analyses them automatically against the model.
Models
Models are written in the PRISM language, a simple, high-level modelling language. PRISM supports many different types of probabilistic model. The three most common are:
| Model | Keyword | Use it when |
|---|---|---|
| Discrete-time Markov chain (DTMC) | dtmc |
Behaviour is purely probabilistic, in discrete steps |
| Continuous-time Markov chain (CTMC) | ctmc |
Events happen after exponentially distributed delays, in continuous time |
| Markov decision process (MDP) | mdp |
There are also nondeterministic choices: decisions to optimise, or an unknown scheduler / environment |
PRISM also supports real-time models (e.g., probabilistic timed automata, PTAs), partially observable models (e.g., partially observable Markov decision processes, POMDPs), and uncertain models (e.g., interval Markov decision processes, IMDPs). It can also analyse non-probabilistic models (e.g., labelled transition systems, LTSs), using temporal logics such as CTL and LTL.
Properties
Properties are written in PRISM's property specification language, which is based on temporal logic. It incorporates several well-known probabilistic temporal logics, such as PCTL, probabilistic LTL and CSL. It also covers costs and rewards, multi-objective queries, and much more.
PRISM can formally verify that these properties hold (e.g., "the probability of a failure occurring within 10 time units is below 0.01") or generate strategies/policies/controllers that optimise properties (e.g., "how can I maximise the probability of reaching a goal location whilst avoiding hazard locations?").
Where to start
New to PRISM? See the "Getting started" section for details of installing and running PRISM for the first time. Work through the tutorial to learn what the tools can do, or read the sections on the modelling and property languages.
Contents
- Getting started: installing PRISM, solving common problems and first steps
- The PRISM language: how to write models
- Property specification: how to write properties
- Extended model types: real-time, partially observable and uncertain models
- Running PRISM: building, simulating, solving, verifying, exporting/importing models
- Configuration and performance: engines, solution methods and other settings
- Reference: language syntax, command-line switches, file formats and references
- Frequently asked questions: memory problems, modelling and properties
Getting started
This section guides new users through the first steps of installing and running PRISM.
Contents
- Installing PRISM: installing a binary release, or compiling from source
- Troubleshooting: solutions to problems installing, compiling or running PRISM
- First steps: a first run of the GUI or command-line tool
Installing PRISM
Prerequisites
PRISM runs on Linux, Windows and macOS. Pre-compiled binaries are available for 64-bit Linux (x86 and Arm), macOS (Apple silicon and Intel) and Windows (x86); on other platforms, you can build PRISM from source.
You will need Java, version 11 or above. To run binary versions of PRISM, you only need the Java Runtime Environment (JRE), not the full Java Development Kit (JDK).
To compile PRISM from source, you need the Java Development Kit (JDK), GNU make and a C/C++ compiler (e.g. gcc/g++). For compilation under Windows, you will need Cygwin. See below for more information:
- Installation on Windows
- Installation of Linux/Mac binary versions
- Building PRISM from source (non-Windows)
- Building PRISM from source on Windows using Cygwin
- Building PRISM from source on Windows using MSYS2
If you are installing on a completely fresh operating system installation (e.g. in a virtual machine), you may find the following scripts useful,
which install the required dependencies and PRISM itself. They can be found in the prism/etc/scripts directory:
- Script to build on a clean install of Ubuntu: prism-install-ubuntu
- Script to build on a clean install of Fedora-based Linux (e.g. Amazon Linux): prism-install-fedora
- Scripts to build on a clean install of Windows: prism-install-windows.bat and prism-install-cygwin
Installation on Windows
If you don't yet have Java, install it, for example with the Temurin installer.
To install PRISM on Windows, just run the self-extracting installer which you downloaded. You do not need administrator privileges for this, just write-access to the directory chosen for installation.
If requested, the installer will place shortcuts to run PRISM on the desktop and/or start menu. If not, you can run PRISM by double-clicking the file xprism.bat (which may just appear as xprism) in the bin folder of your PRISM folder. If nothing happens, the most likely explanation is that Java is not installed or not in your path. To check, open a command prompt window, navigate to the PRISM directory, type cd bin, then xprism.bat and examine the resulting error. If you want to create shortcuts to xprism.bat manually, you will find some PRISM icons in the etc folder.
If you wish to use the command-line version of PRISM on Windows, open a command prompt window and type for example:
cd "c:\Program Files\prism-4.11\bin"
prism ..\prism-examples\simple\dice\dice.pm
You can also edit the file bin\prism.bat to allow it to be run from any location. See the instructions within the file for further details.
Problems? See "Troubleshooting".
Installation of Linux/Mac binary versions
We provide pre-compiled binary distributions for Linux and macOS
(if you have any problems running these, try compiling PRISM from source instead - see below for instructions).
To install a binary distribution, unpack the tarred/zipped PRISM distribution into a suitable location, enter the directory and run the install.sh script, e.g.:
tar xfz prism-4.11-linux64-x86.tar.gz
cd prism-4.11-linux64-x86
./install.sh
On macOS, you may want to run the following command, which avoids manually approving the integrity of the binary files:
xattr -d com.apple.quarantine lib/*lib
You do not need to be root to install PRISM. The install script simply makes some small customisations to the scripts used to launch PRISM. The PRISM distribution is self-contained and can be freely moved/renamed, however if you do so you will need to re-run ./install.sh afterwards.
To run PRISM, execute either the xprism or prism script (for the graphical user interface or command-line version, respectively). These can be found in the bin directory. These scripts are designed to be run from anywhere and you can easily create symbolic links or aliases to them. If you want icons to create desktop shortcuts to PRISM, you can find some in the etc directory.
Problems? See "Troubleshooting".
Building PRISM from source (non-Windows)
To compile PRISM from source code, you will need:
- GNU make (sometimes called gmake)
- a C/C++ compiler (e.g. gcc/g++)
- a Java Development Kit, version 11 or above
To check that you have the development kit, type javac. If you get an error message that javac cannot be found, you probably do not have the JDK installed (or your path is not set up correctly). To check what version you have, type javac -version.
Hopefully, you can build PRISM simply by entering the PRISM directory and running make, e.g.:
tar xfz prism-4.11-src.tar.gz
cd prism-4.11-src/prism
make
For this process to complete correctly, PRISM needs to be able to determine your operating system (OSTYPE), machine architecture (ARCH) and the location of your Java distribution (JAVA_DIR). If there is a problem with any of these, you will see an error message and will need to specify one or more of these manually, such as in these examples:
make OSTYPE=linux
make OSTYPE=linux ARCH=aarch64
make JAVA_DIR=/usr/lib/jvm/java-21-openjdk
make OSTYPE=cygwin JAVA_DIR="/cygdrive/c/Program Files/Java/jdk-21"
Note the use of double quotes for the case where the directory contains a space. If you don't know the location of your Java installation, try typing which javac. If the result is e.g. /usr/lib/jvm/java-21-openjdk/bin/javac then your Java directory is /usr/lib/jvm/java-21-openjdk. Sometimes javac will be a symbolic link, in which case use "ls -l" to determine the actual location.
It is also possible to set the environment variables directly or edit their values in the Makefile directly. Note that even when you specify JAVA_DIR explicitly (in either way), PRISM still uses the version of javac that is in your path. To override this, you can also specify a specific version by setting JAVAC.
Problems? See "Troubleshooting".
Building PRISM from source on Windows using Cygwin
The compilation of PRISM relies on a Unix-like environment. On Windows, this can be achieved using the Cygwin development environment, with the packages below installed. You can run the script prism-install-windows.bat in a Command Prompt to automate this.
makemingw64-x86_64-gcc-g++binutilsdos2unixgit(if you will pull source code from GitHub)wget(if you will pull source code from the web)
Then proceed as described in the previous section. Note that the PRISM compilation process uses the MinGW-w64 libraries so that the final result is independent of Cygwin at run-time.
One thing to note: make sure you unzip the PRISM distribution from within Cygwin (e.g. using tar xfz prism-XXX-src.tar.gz). Don't use a Windows program (Winzip, etc.) since this can cause problems.
If you use git to checkout the PRISM repository, we recommend that you use the version of git provided by Cygwin. If you use a native Windows version of git, you may want to disable the Unix-to-Windows line-ending conversion, e.g., via
git config --global core.autocrlf false
Problems? See "Troubleshooting".
Building PRISM from source on Windows using MSYS2
An alternative to Cygwin on Windows is MSYS2. You can install the required MSYS2 packages like this:
pacman -S make mingw-w64-x86_64-gcc binutils dos2unix git wget unzip python nano
Build as for Cygwin, but with MSYS2's MinGW compilers:
make OSTYPE=cygwin CC=/mingw64/bin/gcc CXX=/mingw64/bin/g++
./install.sh
Problems? See "Troubleshooting".
Troubleshooting
Here are the answers to some of the most common questions about installing and running PRISM. If you are still stuck, see "Getting help" on the PRISM website.
Running PRISM
When I double-click the PRISM shortcut on Windows nothing happens
The most common cause of this is that you either do not have Java installed or the java executable is not in your path. In any case, to determine the exact problem, launch a command shell and navigate to the bin directory inside the directory where you installed PRISM (you can use the "PRISM (console)" shortcut installed in the start menu to do this). Then, type prism.bat and see what error message is displayed.
PRISM won't start: NoClassDefFoundError or UnsatisfiedLinkError
When I try to run PRISM, I get one of these errors:
Exception in thread "main" java.lang.NoClassDefFoundError: ...
java.lang.UnsatisfiedLinkError: no prism in java.library.path
java.lang.UnsatisfiedLinkError: ... Library not loaded: ../../lib/libprism.dylib
Things to check:
-
Did you run
install.shfrom the PRISM directory? -
If you compiled PRISM from source code, are you sure no errors occurred during the process? To check, go into the PRISM directory, type
make clean_alland thenmake, checking the output (especially at the end) carefully for any error messages. -
Are you running on macOS? See the next question.
-
Is PRISM picking up the wrong
java? You can give the exact path to thejavato use when running PRISM, e.g.:PRISM_JAVA=/Library/Java/JavaVirtualMachines/temurin-21.jdk/Contents/Home/bin/java prismor set the value of
PRISM_JAVAin theprismscript directly.
macOS won't open libprism.dylib
When I try to run PRISM on macOS, I get an error of the form:
"libprism.dylib" can't be opened because Apple cannot check it for malicious software.
or:
libprism.dylib not valid for use in process: library load disallowed by system policy
PRISM's macOS binaries are not signed/notarised,
so you need to approve the binary files manually to run them.
Run this command from the same place you ran ./install.sh:
xattr -d com.apple.quarantine lib/*lib
or approve the libraries one by one through the security settings.
You can also avoid this issue by compiling from source code.
PRISM won't start: UnsupportedClassVersionError
When I try to run PRISM, I get an error of the form:
Exception in thread "main" java.lang.UnsupportedClassVersionError: ... has been compiled by a more recent version of the Java Runtime ...
Your version of Java is too old (PRISM needs Java 11 or above). Update or install a newer version of Java, and then try again.
Compiling PRISM
make seems to get stuck in an infinite loop
This is probably due to the detection of Java failing. Specify the location of your Java directory by hand, e.g. make JAVA_DIR=/usr/lib/jvm/java-21-openjdk. See "Building PRISM from source" for more on this.
libtool errors on macOS
When I try to compile PRISM, I get errors of the form:
/usr/bin/libtool: for architecture: cputype (16777234) cpusubtype (0) file: -lSystem is not an object file (not allowed in a library)
The likely explanation is that you have upgraded to a new version of macOS but have not upgraded the developer tools (Xcode or its command line tools). Upgrade (e.g. with xcode-select --install) and try again.
Nothing happens, or Unexpected end of line seen
When I try to compile PRISM, nothing seems to happen, or I get errors of the form:
make: Fatal error in reader: Makefile, line 58: Unexpected end of line seen...
Perhaps you are not using the GNU version of make. Try typing make -v to find out. On some systems, GNU make is called gmake.
$'\r': command not found on Windows
When I try to compile PRISM on Windows, I get errors of the form:
./install.sh: line 2: $'\r': command not found
The files have Windows line endings. Did you unpack PRISM using WinZip or another Windows program, or check it out with a Windows version of git? If so, unpack from Cygwin, using tar xfz (or similar), or use Cygwin's git (see "Building PRISM from source on Windows using Cygwin").
can't create ... No such file or directory
When I try to compile PRISM, I get an error of the form:
Assembler messages: Fatal error: can't create ../../obj/dd/dd_abstr.o: No such file or directory
Did you unpack PRISM using a graphical tool or file manager? If so, unpack using tar xfz (or similar) instead.
Do I have to use GNU make to build PRISM?
Strictly speaking, no, but you will have to modify the various PRISM Makefiles manually to overcome this.
Can I build PRISM on other operating systems?
PRISM should be suitable for any Unix/Linux variant.
The first thing you will need to do is compile CUDD (the BDD library used by and included in PRISM) on that platform.
CUDD is built with its own configure script (run by cudd/install.sh),
which works on most Unix-like systems.
To just build CUDD, not PRISM, type make cuddpackage instead of make.
Next, look at the main PRISM Makefile, in particular, each place where the
variable $OSTYPE is referred to. Most lines include comments and further
instructions. Once you have done this, proceed as usual.
If you do successfully build PRISM on other platforms, please let us know so we can include this information in future releases. Thanks.
Other issues
How do I uninstall PRISM?
If you installed PRISM on Windows using the self-extracting installer, you can uninstall it using the option on the start menu. If you didn't add these shortcuts, just run uninstall.exe from the directory where you installed PRISM.
On other platforms, simply delete the directory containing it.
The only thing that is not removed via either of these methods is the file containing your PRISM settings (see "Settings file" for where it is). You may wish to retain this when upgrading.
First steps
To get started with PRISM, check that you can run either the
graphical user interface (xprism) or the command-line version (prism),
as explained in the installation instructions.
In short, to run the PRISM GUI:
- (on Windows) click the short-cut (to
xprism.bat) installed on the Desktop/Start Menu - (on other OSs) run the
xprismscript in thebindirectory
and for the command-line:
- run the
prismscript in thebindirectory
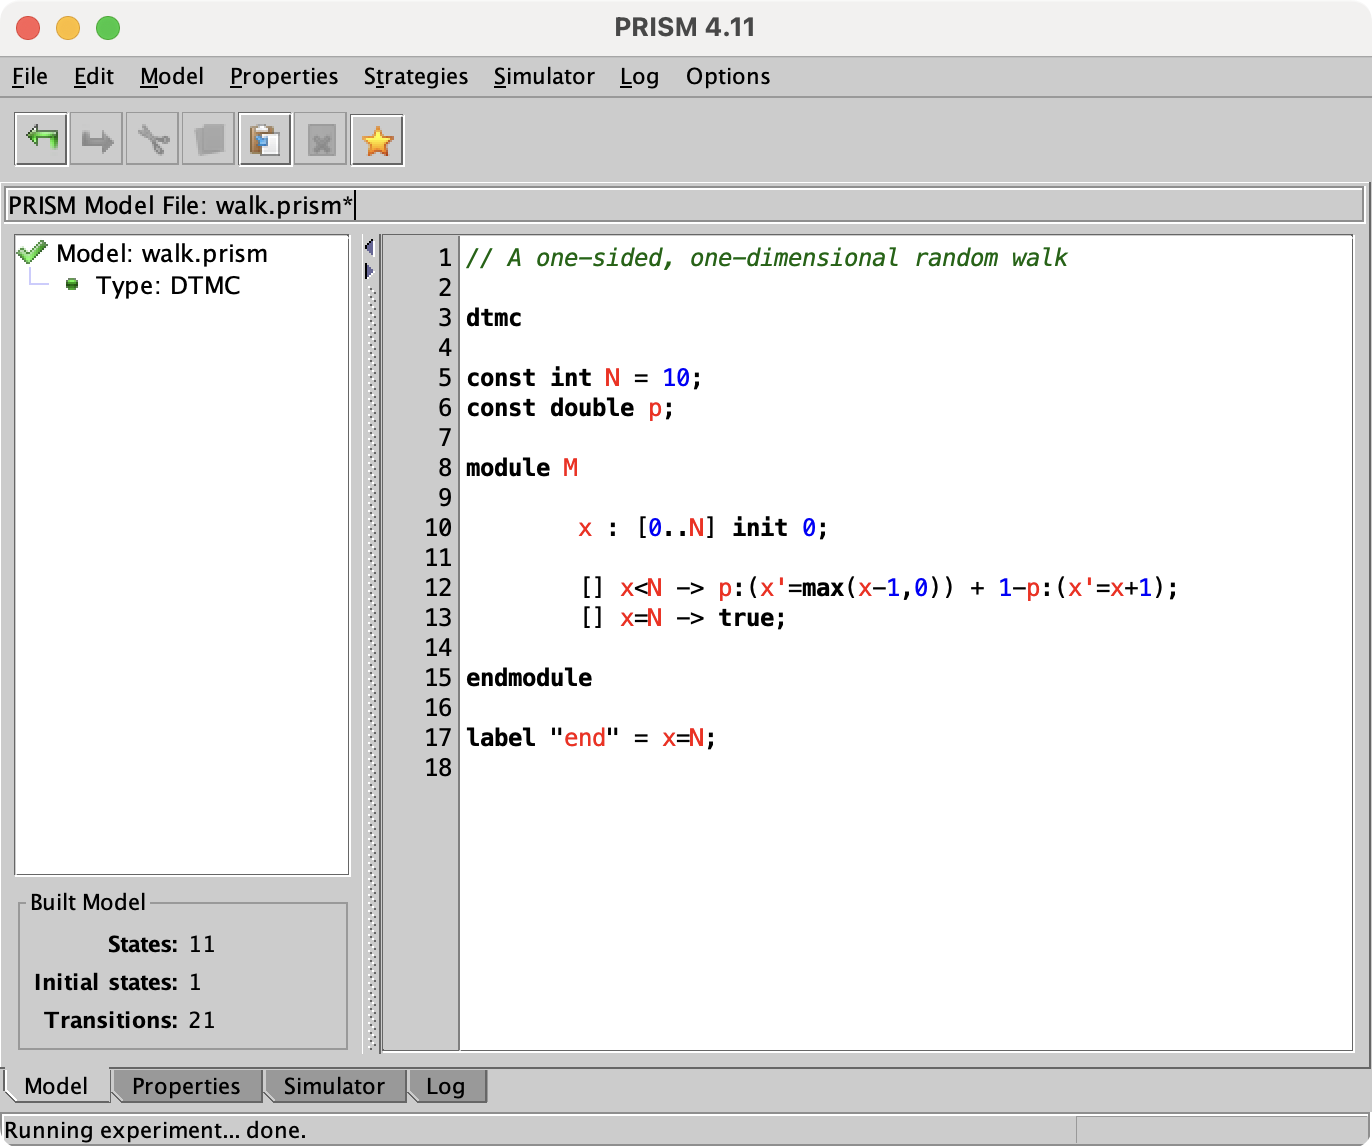
You first need a model. Here is a small random walk, specified in the PRISM modelling language:
// A one-sided, one-dimensional random walk

dtmc

const int N = 10;
const double p = 0.5;

module M

	x : [0..N] init 0;

	[] x<N -> p:(x'=max(x-1,0)) + 1-p:(x'=x+1);
	[] x=N -> true;

endmodule

label "end" = x=N;
Loading it into the GUI (xprism walk.prism) lets us view and edit the model:
Some examples of properties to be checked are:
const int k;

// The walk reaches the end with probability 1
P>=1 [ F "end" ];

// What is the probability of reaching the end within k steps?
P=? [ F<=k "end" ];
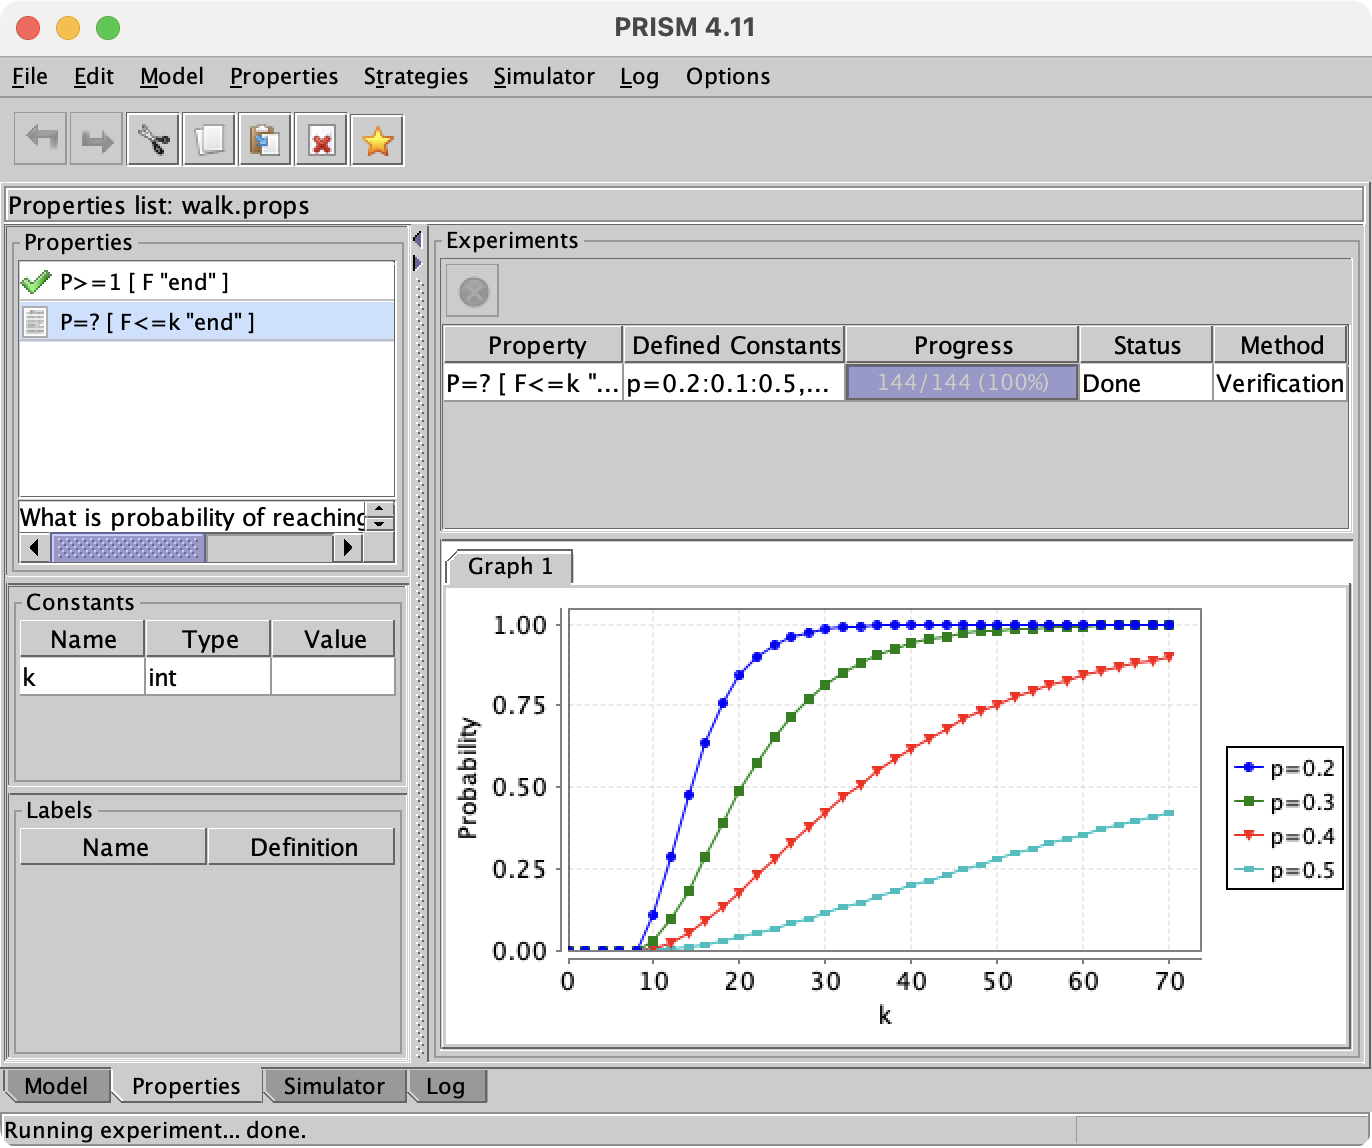
Also loading this properties file into the GUI (e.g., xprism walk.prism walk.props),
we can verify the first property to be true and,
by making a small change to the constant p and running an experiment,
we can start visualising results of the model's analysis:
All this and more can be done from the command line. Just giving the model file builds it and displays some statistics:
prism walk.prism
...
Type:        DTMC
States:      11 (1 initial)
Transitions: 21
...
or we can verify a property:
prism walk.prism walk.props -prop 1
...
Result: true
Full details of both the GUI and command-line versions of PRISM are given in the "Running PRISM" section of this manual. For more detailed walkthroughs of the tool, try the PRISM tutorial.
The PRISM language
In order to construct and analyse a model with PRISM, it must be specified in the PRISM modelling language (often referred to simply as the PRISM language). This is a simple, state-based language, based on the Reactive Modules formalism [AH99], which expresses the behaviour of a system in terms of guarded commands that describe how its state evolves over time.
The PRISM language is used to describe all the types of model that the tool supports,
using files with the extension .prism.
The three most commonly used model types are:
- discrete-time Markov chains (DTMCs)
- continuous-time Markov chains (CTMCs)
- Markov decision processes (MDPs)
This section describes the PRISM language, focusing on how it can be used to specify models of these three types, and giving some small illustrative examples.
Later parts of the manual (in the "Extended model types" section) describe further modelling features that support the specification of various other model types:
- Real-time models using real-valued clocks to represent time, notably probabilistic timed automata (PTAs)
- Partially observable models, notably partially observable Markov decision processes (POMDPs)
- Uncertain models, such as interval discrete-time Markov chains (IDTMCs) and interval Markov decision processes (IMDPs)
- Non-probabilistic models, notably labelled transition systems (LTSs), which have no probabilities
Contents
This section covers the key modelling features and concepts for the PRISM language:
- Modules and commands: the basics (modules, commands, updates) and an example, illustrated for DTMCs
- Variables: how to use, declare and initialise variables
- Constants, labels and formulas: parameterised values (constants), sets of states (labels) and re-usable expressions (formulas)
- Actions and nondeterminism: introducing nondeterminism, primarily for MDPs, and labelling choices with actions
- Continuous time: how to model CTMCs, using rates instead of probabilities, and races between transitions
- Composition and synchronisation: how modules are combined into one model, synchronising on actions, module renaming and process algebra operators
- Costs and rewards: attaching costs or rewards to states and transitions
Examples
One of the best ways to learn what can be done with the PRISM language is to look at some existing examples.
A number of these are included with the tool distribution in the prism-examples directory.
Many more can be found in the "Case studies" section of the PRISM website.
Note that some examples of model files may use older conventions for filename extensions,
.nm for MDPs or PTAs, .pm for DTMCs and .sm for CTMCs, rather than .prism for all models.
Modules and commands
A PRISM model comprises one or more modules, usually representing distinct system components that may interact with each other. A module has two key ingredients: variables, whose values define the state of the module, and commands, which describe how the state of the module evolves over time.
An example DTMC
The following simple example illustrates these basic concepts on a PRISM model that defines a discrete-time Markov chain (DTMC).
// Variant of a random walk

dtmc

module M

	x : [0..3] init 0;
	y : [0..1] init 0;

	[] y=0 & x<3 -> 0.5:(x'=max(x-1,0)) + 0.4:(x'=x+1) + 0.1:(x'=x+1)&(y'=1);
	[] y=0 & x=3 -> true;
	[] y=1 -> (y'=0);

endmodule
The model's type (discrete-time Markov chain) is denoted by the initial dtmc keyword.
It contains one module M whose state is defined by two integer-valued variables x and y,
with ranges [0..3] and [0..1], respectively.
It models a variant of a one-sided, one-dimensional random walk:
it repeatedly randomly increments or decrements the value of x by one, until x reaches value 3.
This only happens when variable y equals 0.
On each increment of x, there is a chance that the value of y is flipped to 1.
It will then be reset to 0 one step later.
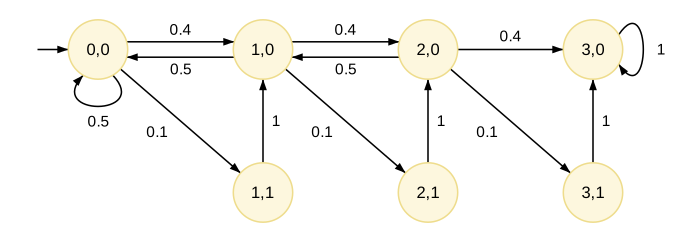
The resulting Markov chain, whose states take the form (x,y), is shown below.
Commands
A module's definition includes its variables, discussed in more detail later, and its commands. Each command comprises a guard and a probabilistic update. The basic form is:
[action] guard -> prob_1 : update_1 + ... + prob_n : update_n;
The guard is a predicate over all the variables in the model,
indicating when the command is enabled.
Each individual update update_i describes a possible outcome of the command being executed,
defined by giving the new values of the module's variables,
with x'=... denoting the new value of variable x.
For a Markov chain, as above, each update update_i is assigned a probability prob_i,
and the probabilities in the command must sum to one.
Commands have an optional action, between the initial pair of square brackets. These have multiple uses, including labelling nondeterministic choices in MDPs and synchronisation between commands in different modules, which are discussed in more detail later. The current example omits actions.
A simple command looks like:
[] x=0 -> 0.8:(x'=1) + 0.2:(x'=2);
which, when variable x has value 0, randomly updates it to either 1 or 2,
with probability 0.8 or 0.2, respectively.
The right-hand side of an update can be an expression
in terms of the current values of the model's variables,
as in the first command of the walk-var.prism example above:
[] y=0 & x<3 -> 0.5:(x'=max(x-1,0)) + 0.4:(x'=x+1) + 0.1:(x'=x+1)&(y'=1);
where (x'=x+1) increments x by 1
and (x'=max(x-1,0)) decrements it by 1, but ensures that it does not go below 0.
Updates to multiple variables are concatenated with &, as in the last update above, which increments x and flips the value of y to 1.
If a variable is not mentioned in an update, its value is assumed to remain unchanged,
i.e., (x'=x+1) above is equivalent to (x'=x+1)&(y'=y).
Thanks to its guard, the command above is enabled whenever y=0 and x<3.
It therefore defines the behaviour for three of the states in the Markov chain shown above:
(0,0), (1,0) and (2,0). For simple Markov chain models like the above,
we will usually assume that the guards are disjoint.
This will usually not be the case for models with nondeterminism
or models with synchronisation between modules.
If there are no enabled commands in some reachable state of the model, this is referred to as a deadlock state. PRISM's default behaviour is to add (probability 1) self-loops to such states and emit a warning.
Updates
If a probability is omitted, it is assumed to be one:
[] y=1 -> (y'=0);
and true is used to denote an empty update where no variable's value changes:
[] y=0 & x=3 -> true;
Changes to multiple variables in an update happen simultaneously.
So, for example, this command updates y to 0, not 1:
[] x=0 & y=0 -> (x'=1)&(y'=x);
Variables
Variables are used to describe the state space of a model. PRISM supports just a few simple types of variables: they can either be (finite ranges of) integers or Booleans (we ignore clocks for now, which are used in real-time models).
Variable declarations
As in the earlier example, variable declarations are usually placed within a module definition. In fact, these are local variables and it is also possible to declare global variables. This distinction is discussed later in the context of composing multiple modules.
The typical form of a variable declaration is:
name : type init initial_value;
where name is a valid identifier.
The most commonly used type is an integer with bounded range, specified as [lower..upper],
as in the earlier walk-var.prism example:
x : [0..3] init 0;
A Boolean variable is declared as, for example:
b : bool init false;
The initial value of a variable can be omitted from its declaration,
in which case it starts with its default value:
the lowest value in the range for an integer, or false for a Boolean.
Thus, the variable declarations shown below are equivalent to the ones above.
x : [0..3];
b : bool;
All the above examples are variables of bounded range. In some cases, this restriction can be relaxed, for example when using techniques such as statistical model checking or fast adaptive uniformisation which do not exhaustively explore the state space of a model. In these cases, integer variables with unbounded ranges can be used:
x : int init 1;
y : int;
For variable y above, where the initial value is omitted,
the initial value is taken to be 0.
PRISM's explicit engine can also be applied
to models with unbounded integer variables, as long as the reachable state space of the model remains finite.
Multiple initial states
The above examples assume that the model has a single initial state,
defined by the initial values of each of its variables.
It is possible to specify that a model has multiple initial states.
This is done using the init...endinit construct,
which can be placed anywhere in the file except within a module definition,
and removing any initial values from variable declarations.
Between the init...endinit is a predicate over all variables:
any state that satisfies this predicate is an initial state.
For example, given the following variable declarations:
x : [0..3];
b : bool;
this definition:
init x<2 endinit
results in a model with four initial states: (0,false), (0,true), (1,false) and (1,true).
Constants, labels and formulas
Constants
PRISM models often contain constants, which can be used to parameterise some values within the model,
such as the range of a variable or the probability associated with an update.
These constants can then appear in expressions anywhere in the model.
For example, we can rewrite the earlier walk-var.prism with constants,
making it much easier to change the size of the random walk or its probabilities:
// Variant of a random walk

dtmc

// Max value of random walk
const int N = 3;
// Probability of increment
const double p = 0.5;
// Probability of changing y when incrementing
const double q = 0.2;

module M

	x : [0..N] init 0;
	y : [0..1] init 0;

	[] y=0 & x<N -> 1-p:(x'=max(x-1,0)) + p*(1-q):(x'=x+1) + p*q:(x'=x+1)&(y'=1);
	[] y=0 & x=N -> true;
	[] y=1 -> (y'=0);

endmodule
Constants can be defined anywhere in a model file (but outside its modules) and can be of type integer, double or Boolean. The value of a constant can be specified as any constant expression of an appropriate type, and can also refer to the values of other constants. Examples of constant definitions are:
const int size = 10;
const double prob_fail = 1/size;
const bool enabled = true;
It is also possible to leave the values of one or more constants undefined, which allows them to be specified at the time of model checking, or to facilitate experiments over ranges of values:
const int size;
const double prob_fail = 1/size;
Labels
Models can be annotated with labels, which are used to identify sets of states that are of particular interest. Primarily, these are used when specifying properties and are in this sense synonymous with the notion of atomic propositions in temporal logic.
A label is defined by a Boolean expression, and its name is written using quotation marks ("..."), as illustrated in the following examples:
label "top" = x=N;
label "safe" = temp<=100 | alarm=true;
label "fail" = temp>100 & alarm=false;
Unlike constants, though, labels cannot be used to define other labels, and cannot appear in other parts of the model, such as guards or updates.
Formulas
The PRISM language supports formulas, which are used to avoid duplication of commonly repeated expressions within a model definition. A formula definition gives its name (a valid identifier) and an expression that defines it. The latter can be any valid expression, of arbitrary type, and including constants, variables or other formulas. The formula name can then be used as shorthand for the expression anywhere that an expression might usually be accepted. A formula is defined as follows:
formula num_tokens = q1+q2+q3+q4+q5;
It can then be used anywhere within that file, as for example in this command:
[] p1=2 & num_tokens=5 -> (p1'=4);
The effect is exactly as if the following had been typed:
[] p1=2 & (q1+q2+q3+q4+q5)=5 -> (p1'=4);
Formulas defined in a model can also be used when specifying its properties. Unlike labels, formulas can be of any type, not just Boolean, and their names are written without quotation marks.
Actions and nondeterminism
The examples presented so far have been DTMCs, which means that each state has one or more outgoing transitions with associated probabilities that sum to one. Another core model type supported by PRISM is the Markov decision process (MDP), which allows for nondeterminism in the model. In this case, each state can have several choices, each of which defines a probability distribution over successor states. Often, but not always, these choices are labelled with actions.
In the PRISM language, nondeterminism can be modelled by allowing the guards of its commands to overlap. Each enabled command in a state defines a separate choice, and its (optional) action label is specified using the square brackets at the start of the command.
An example MDP
The following example represents a classic MDP, the "chain" model [Str00].
There are N states in a chain, and in each one there are two possible actions:
a, which moves one step along the chain, and b, which goes back to the start.
But actions are not completely reliable:
with probability slip, the other action happens instead.
// A "chain" MDP: At each step, choose action a (move along the chain) or b
// (go back to the start), but with probability slip, the other one happens

mdp

// Number of states in the chain
const int N = 4;
// Probability that the chosen action slips
const double slip = 0.2;

module chain

	s : [0..N-1] init 0;

	[a] true -> 1-slip : (s'=min(s+1,N-1)) + slip : (s'=0);
	[b] true -> 1-slip : (s'=0) + slip : (s'=min(s+1,N-1));

endmodule
The keyword mdp indicates that the model is an MDP.
The module has a single variable s representing the position in the chain,
which ranges from 0 to N-1 using a constant N (here, 4).
The two commands have the guard true, so both are enabled in every state.
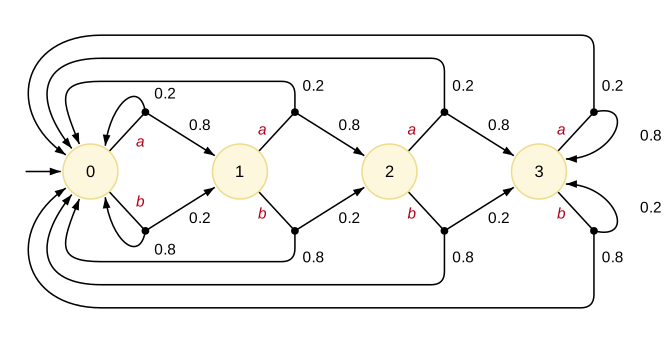
In the resulting MDP, each state has two choices, labelled a and b.
For example, in state s=0, there are two choices:
a: move to states=1with probability 0.8, or stay ins=0with probability 0.2b: stay ins=0with probability 0.8, or move to states=1with probability 0.2
The full MDP is shown below, where each state is labelled with its value of s.
Actions
The commands above are labelled with actions a and b, written between the square brackets, e.g.:
[a] true -> 1-slip : (s'=min(s+1,N-1)) + slip : (s'=0);
For an MDP, these actions play several roles. Firstly, they allow the definition of policies (referred to as "strategies" in PRISM), specifying which action to take in each state in order to satisfy or optimise some property. Actions can also be used (for all model types, not just MDPs) to define rewards and to enforce synchronisation between commands in different modules.
However, actions are optional.
For an MDP, omitting them from a command ([]) results in unlabelled choices.
For example these commands:
[] x<5 -> (x'=x+1);
[] x>2 -> (x'=x-1);
result, in states x=3 and x=4, in two unlabelled choices incrementing or decrementing x.
In similar fashion, PRISM allows the definition of MDPs in which the choices from a state have the same action (technically, this is a probabilistic automaton [Seg95], rather than an MDP):
[a] x<5 -> (x'=x+1);
[a] x>2 -> (x'=x-1);
[b] x=3 -> true;
In both cases (unlabelled choices and duplicate actions), restrictions may then be imposed on the generation of policies/strategies.
Local nondeterminism
We refer to the nondeterminism arising from overlapping guards in a single module as local nondeterminism. In MDPs comprising multiple modules, nondeterminism also arises due to the concurrent interleaving of its commands' execution.
In models that do not include nondeterminism, overlapping guards are treated differently. In particular, in a DTMC, if several commands are enabled in a state, it is assumed that one of them is picked uniformly at random. For example, given the following model:
dtmc

module M

    x : [0..3] init 0;

    [] x=0 -> 0.1:(x'=1) + 0.9:(x'=2);
    [] x=0 -> (x'=3);
    [] x>0 -> true;

endmodule
the first two overlapping commands result in state x=0 of the DTMC
having three outgoing transitions, to states x=1, x=2 and x=3,
with probabilities 0.05, 0.45 and 0.5, respectively.
Continuous time
The models seen so far, DTMCs and MDPs, are discrete-time: they move from state to state in discrete time steps. A continuous-time Markov chain (CTMC) instead permits real-valued time delays between the occurrence of transitions. More precisely, each transition of a CTMC has a rate, rather than a probability, and the time taken for the transition to happen is a random delay, which is exponentially distributed with that rate. A transition with rate r takes, on average, time 1/r: the higher the rate, the sooner the transition is likely to happen. CTMCs are widely used to model systems such as computer networks and queueing systems, reliability of hardware, and biochemical reaction networks.
An example CTMC
The following CTMC models a system of N identical components (here, 3),
each of which may fail, and a repair unit, which repairs failed components one at a time.
Each component fails at rate lambda, i.e., on average it works for time 1/lambda = 10 before failing,
and a repair takes, on average, time 1/mu = 0.5.
// N identical components, each of which fails at rate lambda,
// and a single repair unit, which repairs them one at a time at rate mu

ctmc

const int N = 3; // number of components
const double lambda = 0.1; // failure rate of each component (mean time to failure: 10)
const double mu = 2; // repair rate (mean repair time: 0.5)

module components

	f : [0..N] init 0; // number of failed components

	[fail]   f<N -> (N-f)*lambda : (f'=f+1);
	[repair] f>0 -> mu : (f'=f-1);

endmodule
A CTMC model is written in the same way as a DTMC, with commands made up of guards and updates,
but with the model type ctmc, and with rates, rather than probabilities, attached to updates.
The rate of failure here depends on the state:
when f components have failed, N-f are still working,
and the first of them fails at rate (N-f)*lambda, since rates of independent events add up (see below).
Only one component is repaired at a time, so repairs happen at rate mu, whenever at least one component has failed.
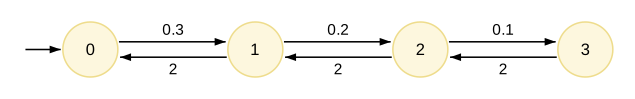
The resulting CTMC, whose states are the values of f, is shown below,
with each transition labelled by its rate.
Rates and races
As seen above, the notation used to give rates in a command is similar to that used for probabilities:
[] guard -> rate_1:update_1;
[] guard -> rate_2:update_2;
where each rate_i can be any positive value and is assumed to be 1 if omitted.
It is also possible to group updates with the same guard into a single command.
So, the above could be written as:
[] guard -> rate_1:update_1 + rate_2:update_2;
In either case, unlike DTMCs, the rates do not need to sum to one. The former approach allows the transitions to be labelled with different actions:
[a] guard -> rate_1:update_1;
[b] guard -> rate_2:update_2;
Unlike MDPs, there is no nondeterminism in a CTMC, and the a and b are just convenient labels for the transitions
(or a mechanism for synchronisation between modules, discussed later).
Commands with overlapping guards in a CTMC result in multiple transitions being possible in a state,
each with its own rate. This is known as a race condition:
the transition whose associated delay finishes first is the one that happens.
The time until the first of them happens is also exponentially distributed,
with a rate equal to the sum of their rates,
and each one happens first with probability proportional to its rate.
This is why, in the example above, the first failure among N-f working components happens at rate (N-f)*lambda.
Similarly, if several transitions from a state lead to the same state,
they are combined into one transition with a rate equal to the sum of the individual rates
(as, in fact, also happens for probabilities in discrete-time models).
Composition and synchronisation
Most PRISM models involve the parallel composition of several modules, which may interact with each other in various ways. In such cases, the global state of the whole model comprises the local states of all modules, i.e., the values of the local variables of each module. Furthermore, a module can read the values of any other variable in the model (for example, it can refer to it in the guards of its commands) but a module can only write to its own local variables.
The manner in which modules are composed depends on the model type. We start by describing the case for MDPs, which provide a natural model for the parallel composition of probabilistic components, use this to introduce some of the key ideas, notably synchronisation, and then also describe how the composition of modules is handled for CTMCs and DTMCs.
Composing modules in MDPs
The example below illustrates the parallel composition of two modules in an MDP, communicating with each other by reading each other's variables.
// Two parallel processes, reading each others variables

mdp

module P1
	s1 : [0..1] init 0;

	[a] s1=0 -> 0.9:(s1'=1) + 0.1:(s1'=0);
	[a] s1=1 -> (s1'=s2);
endmodule

module P2
	s2 : [0..1] init 0;

	[b] s2=0 -> 0.8:(s2'=1) + 0.2:(s2'=0);
	[b] s2=1 -> (s2'=s1);
endmodule
Both modules start in local state 0 and randomly move to local state 1 with some probability.
When in state 1, they simply copy the other module's state (e.g., (s1'=s2) in module P1),
and so return to state 0 if the other module is still in state 0,
or remain in state 1 if the other module is in state 1.
References to other modules' variables can also appear in guards,
but here are just used on the right-hand sides of updates.
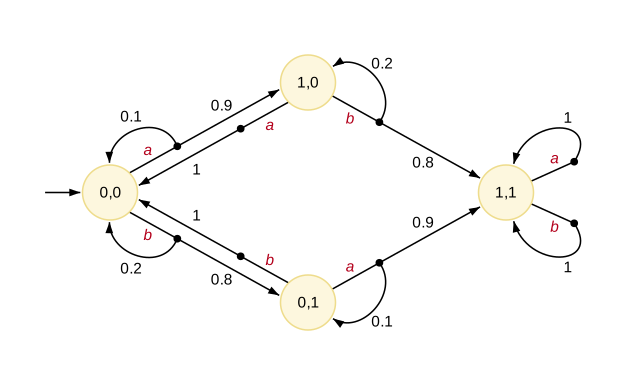
The resulting MDP is shown below, and comprises global states of the form (s1,s2).
Although it is not necessary, we labelled the commands of the two modules with actions, a and b,
which helps identify which module is responsible for each transition.
When both modules have an enabled command (all states in this example),
the choice between which one executes is nondeterministic.
So, even though neither module has overlapping guards,
all states of the MDP have a choice, between actions a and b.
The above example had no local nondeterminism.
If we changed the second module to the version shown below,
where its initial choice to move to state 1 or stay in state 0 is nondeterministic,
then states (0,0) and (1,0) in the MDP above would
have three nondeterministic choices, two labelled with b and one with a.
module P2
	s2 : [0..1] init 0;

	[b] s2=0 -> (s2'=1);
	[b] s2=0 -> (s2'=0);
	[b] s2=1 -> (s2'=s1);
endmodule
Synchronisation
Modules can also use synchronisation to coordinate their behaviour.
In the above example, modules had distinct actions, a and b, which occurred independently.
Commands with the same action label, however, are required to synchronise:
both are executed simultaneously, and this only happens when both commands are enabled.
Below, we modify the second commands of the two modules in the previous example,
removing the references to the other module's variable and using a shared action c.
// Two parallel processes, synchronising on c

mdp

module P1
	s1 : [0..1] init 0;

	[a] s1=0 -> 0.9:(s1'=1) + 0.1:(s1'=0);
	[c] s1=1 -> (s1'=0);
endmodule

module P2
	s2 : [0..1] init 0;

	[b] s2=0 -> 0.8:(s2'=1) + 0.2:(s2'=0);
	[c] s2=1 -> (s2'=0);
endmodule
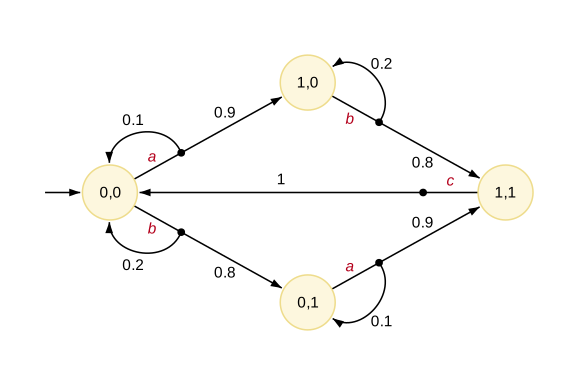
Now, when both modules are in state 1, they synchronise on action c and move to state (0,0).
And in state (1,0) or state (0,1), where only one of the c-labelled commands is enabled,
the synchronisation cannot occur, so the enabled c-labelled command is blocked:
The actions over which two modules synchronise are those that appear in both modules; any other actions are performed independently.
Synchronising commands can both have probabilistic updates.
In the variant below, the first commands of the two modules are both labelled with action a,
so they too have to synchronise.
// Two parallel processes, synchronising on both a and c

mdp

module P1
	s1 : [0..1] init 0;

	[a] s1=0 -> 0.9:(s1'=1) + 0.1:(s1'=0);
	[c] s1=1 -> (s1'=0);
endmodule

module P2
	s2 : [0..1] init 0;

	[a] s2=0 -> 0.8:(s2'=1) + 0.2:(s2'=0);
	[c] s2=1 -> (s2'=0);
endmodule
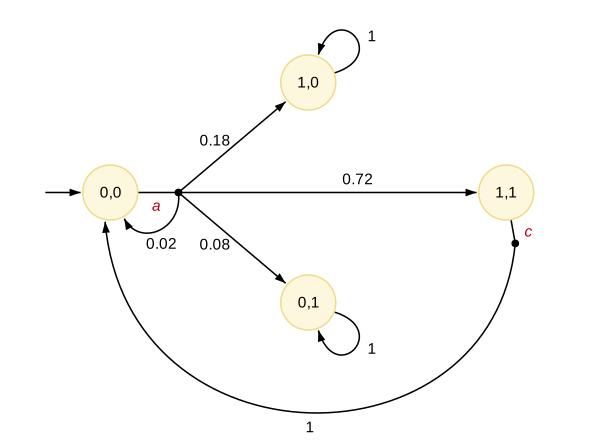
Now, in state (0,0), the two modules move together, in a single choice labelled a,
whose probability distribution is the product of the distributions of the two commands.
For example, both modules move to state 1 with probability 0.9 * 0.8 = 0.72,
and only P1 does so with probability 0.9 * 0.2 = 0.18.
In states (1,0) and (0,1), however, neither a nor c can occur, since each needs both modules,
so these are deadlock states, to which PRISM adds self-loops:
Synchronisation is often used as a simple way to model "sending" data from one module to another.
In the example below, module P1 chooses randomly whether to set its local variable s1 to 1 or 2.
It then communicates the result of this to module P2 by offering either action c1 or c2 for synchronisation,
depending on the value of s1. In isolation, module P2 would exhibit local nondeterminism,
but in parallel with P1 only ever performs c1 or c2 in a state.
// Module P1 "sends" a value (1 or 2) to P2, using a different action for each

mdp

module P1

	s1 : [0..2] init 0;

	[a] s1=0 -> 0.9:(s1'=1) + 0.1:(s1'=2);
	[c1] s1=1 -> (s1'=0);
	[c2] s1=2 -> (s1'=0);

endmodule

module P2

	s2 : [0..2] init 0;

	[c1] s2=0 -> (s2'=1);
	[c2] s2=0 -> (s2'=2);
	[d] s2>0 -> (s2'=0);

endmodule
We can achieve the same behaviour in another way by simultaneously synchronising on a single
action c and module P2 reading the value of s1 as it updates its own variable s2:
// Module P1 "sends" a value (1 or 2) to P2, which reads it while synchronising on c

mdp

module P1

	s1 : [0..2] init 0;

	[a] s1=0 -> 0.9:(s1'=1) + 0.1:(s1'=2);
	[c] s1>0 -> (s1'=0);

endmodule

module P2

	s2 : [0..2] init 0;

	[c] s2=0 -> (s2'=s1);
	[d] s2>0 -> (s2'=0);

endmodule
Composing modules in CTMCs
For a CTMC,
parallel composition between modules works analogously to MDPs,
except that the choice between enabled commands is a race condition, not nondeterministic.
Consider two commands in different modules that are labelled with actions a and b,
where those actions are used only in those modules.
Then, in a state where both commands are enabled, each results in a separate outgoing transition, with its own rate.
For two commands with a common action c, synchronisation occurs,
with both commands being executed simultaneously
and the rate of the synchronised transition taken as the product of the two individual rates.
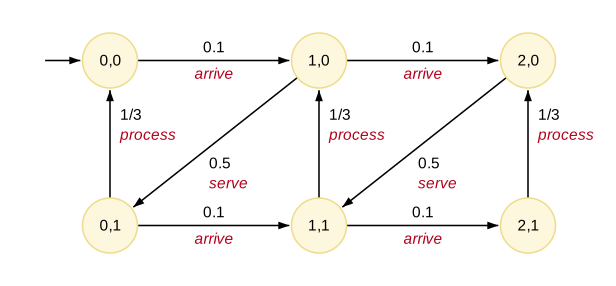
This is illustrated by the model below,
in which jobs arrive into an N-place queue
and are removed by a server which processes them one at a time.
// An N-place queue and a server

ctmc

const int N = 2;
const double lambda = 1/10;
const double mu = 1/2;
const double gamma = 1/3;

module queue
     q : [0..N];

     [arrive] q<N -> lambda:(q'=q+1);
     [serve] q>0 -> mu:(q'=q-1);
endmodule

module server
     s : [0..1];

     [serve] s=0 -> 1:(s'=1);
     [process] s=1 -> gamma:(s'=0);
endmodule
The CTMC (assuming N=2, as above) is shown below, with the states labelled as q,s.
In a CTMC, the product of two rates does not always meaningfully represent the rate of a synchronised transition.
A common technique, as seen here, is to make one command passive, with rate 1, and the other active,
which actually defines the rate for the synchronised transition
(in this case, mu * 1 = mu).
Composing modules in DTMCs
In a DTMC, the choice between two enabled commands with non-shared actions is probabilistic, with each command being selected with equal probability. It is much more common, in DTMC models that use multiple modules, to make modules synchronise fully, leaving no situations where a choice between enabled commands is randomised.
Below is a simple example, borrowed from the model of Herman's self-stabilisation algorithm, in which two modules repeatedly move in lockstep, with a probabilistic update that depends on the other module's state. (The second module is defined using module renaming, described below.)
// Two processes from Herman's self-stabilisation algorithm, moving in lockstep

dtmc

module process1

	x1 : [0..1] init 1;

	[step] (x1=x2) -> 0.5 : (x1'=0) + 0.5 : (x1'=1);
	[step] !(x1=x2) -> (x1'=x2);

endmodule

module process2 = process1 [ x1=x2, x2=x1 ] endmodule
Both commands of each module are labelled with action step,
and in every state exactly one of them is enabled, so every transition of the DTMC
is a synchronisation of both modules.
When the two modules synchronise, the probability of the resulting transition is
the product of the probabilities of the two individual updates.
So, in states (0,0) and (1,1), where x1=x2, both modules choose a new value at random,
giving four transitions, each with probability 0.5 * 0.5 = 0.25;
in states (0,1) and (1,0), each module copies the other's value,
and the model moves to the other one of these two states with probability 1.
Module renaming
PRISM also supports module renaming, which allows reuse of a module definition
when there are several modules with (almost) identical behaviour.
Below, we rewrite the compose-interleave.prism example from above,
using module renaming to define P2 in terms of P1:
// Two similar parallel processes, defined using module renaming

mdp

const double p1 = 0.9;
const double p2 = 0.8;

module P1
	s1 : [0..1] init 0;

	[a] s1=0 -> p1:(s1'=1) + 1-p1:(s1'=0);
	[a] s1=1 -> (s1'=s2);
endmodule

module P2 = P1 [ s1=s2, s2=s1, a=b, p1=p2 ] endmodule
The syntax is as follows:
module Mnew = Mold [ old1=new1, old2=new2, ... ] endmodule
where the renames old1=new1, old2=new2, ... specify how identifiers appearing in
the original module Mold are to be renamed in the new module Mnew.
The renaming is done at a textual level, so variables, constants and actions can all be renamed in this way.
In the example, s1 has to be renamed, in order to give P2 a distinct variable s2,
but we also need to rename s2, since P1 refers to it in its updates, and the action a.
Note also how we convert the literal probabilities (0.9 and 0.8) into constants,
which allows them to differ in the second module.
Take care when using module renaming in conjunction with formulas. Expansion of formulas is done before module renaming so, if a module which uses formulas is renamed to another module, it is the contents of the formula which will be renamed, not the formula itself.
Global variables
As seen in several of the examples above, variables within a module are considered to be local variables, in that they can only be written by that module. They can however be read by any module. PRISM also allows global variables, which can be written to, as well as read, by all modules. Like local variables, these can be integers or Booleans. Global variables are declared in identical fashion to a module's local variables, except that the declaration must not be inside the definition of any module. Some example declarations are as follows:
global g : [1..10];
global b : bool init true;
A global variable can be modified by any module and provides another way for modules to interact. An important restriction on the use of global variables is the fact that commands which synchronise with other modules cannot modify global variables. PRISM will detect this and report an error.
Process algebra operators
To make the concept of synchronisation described above more powerful,
PRISM allows you to define precisely the way in which the set of modules are composed in parallel.
This is specified using the system ... endsystem construct,
placed at the end of the model description, which should contain a process-algebraic expression.
This expression should feature each module exactly once, and can use the following (CSP-based) operators:
M1 || M2: alphabetised parallel composition of modulesM1andM2(synchronising on only actions appearing in bothM1andM2)M1 ||| M2: asynchronous parallel composition ofM1andM2(fully interleaved, no synchronisation)M1 |[a,b,...]| M2: restricted parallel composition of modulesM1andM2(synchronising only on actions from the set {a,b,...})M / {a,b,...}: hiding of actions {a,b, ...} in moduleMM {a<-b,c<-d,...}: renaming of actionsatob,ctod, etc. in moduleM
The first two types of parallel composition (|| and |||) are associative and can be applied to more than two modules at once.
When evaluating the expression, the hiding and renaming operators bind more tightly than the three parallel composition operators.
No other rules of precedence are defined and parentheses should be used to specify the order in which modules are composed.
Some examples of expressions which could be included in the system ... endsystem construct are as follows:
(station1 ||| station2 ||| station3) |[serve]| server((P1 |[a]| P2) / {a}) || Q((P1 |[a]| P2) {a<-b}) |[b]| Q
When no parallel composition is specified by the user,
PRISM implicitly assumes an expression of the form M1 || M2 || ... containing all of the modules in the model.
For a more formal definition of the process algebra operators described above, check the semantics of the PRISM language, available from the "Documentation" section of the PRISM website.
Costs and rewards
PRISM supports the specification and analysis of properties based on costs and rewards. This means that it can be used to reason, not just about the probability that a model behaves in a certain fashion, but about a wider range of quantitative measures relating to model behaviour. For example, PRISM can be used to compute properties such as "expected time", "expected number of lost messages" or "expected energy consumption".
To achieve this, PRISM allows states and transitions to be annotated with numerical values, representing for example the time taken for a transition or its energy consumption. Although these examples are all "costs" (which we would intuitively like to minimise), following classical definitions of MDPs in the literature, PRISM consistently refers to these values as rewards. In practice, though, they equally well represent costs. This section describes how to specify rewards in a PRISM model. We later describe reward-based property specifications.
State rewards
Rewards are associated with models using rewards ... endrewards constructs,
which can appear anywhere in a model file except within a module definition.
These constructs contain one or more reward items.
Consider the following simple example,
which defines state rewards for a model,
i.e., a mapping just from its states to numerical values:
rewards "r1"
    true : 1;
endrewards
This defines a reward structure with name r1 (the name is optional)
which assigns a reward of 1 to every state of the model.
It comprises a single reward item, the left part of which (true) is a guard
and the right part of which (1) is a reward.
States of the model which satisfy the predicate in the guard are assigned the corresponding reward.
More generally, state rewards can be specified using multiple reward items,
each of the form guard : reward;,
where guard is a predicate (over all the variables of the model)
and reward is an expression (containing any variables, constants, etc. from the model).
For example:
rewards "r2"
    x=0 : 100;
    x>0 & x<10 : 2*x;
    x=10 : 100;
endrewards
assigns a reward of 100 to states satisfying x=0 or x=10
and a reward of 2*x to states satisfying x>0 & x<10.
Note that a single reward item can assign different rewards to different states,
depending on the values of model variables in each one.
Any states which do not satisfy the guard of any reward item will have no reward assigned to them.
For states which satisfy multiple guards, the reward assigned to the state
is the sum of the rewards for all the corresponding reward items.
Transition rewards
Rewards can also be assigned to transitions of a model.
These are specified in a similar fashion to state rewards,
within the rewards ... endrewards construct.
Reward items describing transition rewards are of the form [action] guard : reward;,
the interpretation being that transitions from states which satisfy the guard guard
and are labelled with the action action acquire the reward reward.
For example:
rewards "r3"
    [] true : 1;
    [a] true : x;
    [b] true : 2*x;
endrewards
assigns a reward of 1 to all transitions in the model with no action label,
and rewards of x and 2*x to all transitions labelled with actions a and b, respectively.
As is the case for states, multiple reward items can specify rewards for a single transition,
in which case the resulting reward is the sum of all the individual rewards.
A model description can specify rewards for both states and transitions.
These are all placed together in a single rewards...endrewards construct.
Multiple reward structures
A PRISM model will often have multiple reward structures, for example:
rewards "total_time"
    true : 1;
endrewards

rewards "num_failures"
    [fail] true : 1;
endrewards
The first assigns a reward of 1 to every state, which, for a CTMC, accumulates as time passes;
the second counts transitions labelled fail, as in the repair example.
A property can then refer to a reward structure by its name,
e.g., R{"num_failures"}=? [ C<=10 ] gives the expected number of failures up to time 10.
Property specification
In order to verify or analyse a probabilistic model with PRISM, one or more properties of the model are specified. This is done using the PRISM property specification language, which is based on temporal logic and subsumes several well-known logics:
- PCTL (probabilistic computation tree logic)
- PLTL (probabilistic linear temporal logic)
- PCTL* (which subsumes PCTL and PLTL)
- CSL (continuous stochastic logic)
- CTL (computation tree logic)
- LTL (linear temporal logic)
and also includes reward-based properties and various other extensions.
We give a few illustrative examples of properties below, and then describe the property specification language in more detail in the rest of this section. The presentation given here is relatively informal. For the precise syntax and semantics of the various logics, see [HJ94],[BdA95] for PCTL, [ASSB96],[BKH99] for CSL and, for example, [Bai98] for LTL and PCTL*. You can also find various pointers to useful papers in the About and Documentation sections of the PRISM website.
Examples
Some simple examples of specifications in the PRISM property specification language, along with their natural language interpretations, are given below:
P>=1 [ F "terminate" ]
"the algorithm eventually terminates with probability 1"
P<0.1 [ F<=100 num_errors > 5 ]
"the probability that more than 5 errors occur within the first 100 time units is less than 0.1"
S<0.01 [ num_sensors < min_sensors ]
"in the long-run, the probability that an inadequate number of sensors are operational is less than 0.01"
R{"time"}<=10 [ F "terminate" ]
"the expected time for the algorithm to terminate is at most 10"
Note that the above properties are all assertions, i.e., ones to which we would expect a "yes" or "no" answer. This is because all references to probabilities or rewards are associated with an upper or lower bound which can be checked to be either true or false. In PRISM, we can also directly specify numerical properties:
P=? [ !proc2_terminate U proc1_terminate ]
"the probability that process 1 terminates before process 2 does"
Pmax=? [ F<=T messages_lost > 10 ]
"the maximum probability that more than 10 messages have been lost by time T"
Rmax=? [ F "terminate" ]
"the worst-case expected termination time for the algorithm"
Furthermore, PRISM makes it easy to combine such properties into more complex expressions, compute their values for a range of parameters and plot graphs of the results using experiments. This is often a very useful way of identifying interesting patterns or trends in the behaviour of a system. See the "Case studies" section of the PRISM website for many examples of this kind of analysis.
Contents
- Properties files: specifying a set of properties
- The P operator: the probability of an event, numerical queries, specifying temporal behaviour
- The S operator: long-run (steady-state) behaviour
- Reward-based properties: expected costs and rewards
- Multi-objective properties: trade-offs between objectives for MDPs
- Non-probabilistic properties: CTL and LTL, without probabilities
- Filters: results for sets of states other than the initial ones
Property specification for real-time, partially observable and uncertain models is described later.
Properties files
Properties can be specified individually to PRISM
or can be collated together into a properties file,
a plain text file with file extension .props.
This contains one or more properties,
each of which should be terminated with a semicolon (but the parser is not strict on this).
Properties can refer to various aspects of the model to which they relate
(variable names, labels, etc.) but can also define further
constants and labels
in the same style as in model files.
Comments are allowed too.
An example file is:
const int T;
const int k;

label "phase1" = s=4 & phase=1;

// The algorithm eventually terminates successfully with probability 1
P>=1 [ F "terminate" ];

// The probability of completing phase 1 within time T
P=? [ F<=T "phase1" ];

// The expected time to complete phase k
R=? [ F s=4 & phase=k ];
As in the examples above, labels (such as "terminate" or "phase1") are frequently used in properties to identify sets of states.
These are essentially the same as atomic propositions in temporal logic.
Labels are just Boolean-valued expressions over the state variables of the model (and, optionally, constants).
Such expressions can also be used directly in properties, without labels, as in the final example above.
This is useful when a property is parameterised by a constant.
Two special cases of labels are the "init" and "deadlock" labels which are always defined.
These are true in initial states of the model and states where deadlocks were found (and, usually, fixed by adding self-loops), respectively.
Property names
For convenience, properties can be annotated with names, as shown in the following example:
"surely_terminate": P>=1 [ F "terminate" ];
which gives the name "surely_terminate" to the property.
The name can be referred to when telling PRISM which properties to model check. It can also be referred to in other properties, as in this example of a nested property:
// "Safe" states, where we can return to the base
// in at most 10 time units with probability at least 0.99
"safe_return": P>=0.99 [ F<=10 "base" ];

// What is the probability of always remaining in the safe states?
"stay_safe": P=? [ G "safe_return" ];
Notice that the syntax for referring to named properties is identical to the syntax for labels. For this reason, property names must be disjoint from those of any existing labels.
The P operator
One of the most important operators in the PRISM property specification language is the P operator,
which is used to reason about the probability of an event's occurrence.
This operator was originally proposed in the logic PCTL
but also features in the other logics, such as CSL.
The P operator is applicable to all types of models supported by PRISM.
Informally, the property:
P bound [ pathprop ]
is true in a state of a model if
"the probability that path property pathprop is satisfied by the paths from the state
meets the bound bound".
A typical example of a bound would be:
P>0.98 [ pathprop ]
which means: "the probability that pathprop is satisfied by the paths from the state is greater than 0.98".
More precisely, bound can be any of >=p, >p, <=p or <p,
where p is any constant expression evaluating to a double in the range [0,1], for example:
P>=1 [ pathprop ]
P<q [ pathprop ]
P<=(1-2*q) [ pathprop ]
The types of path property supported by PRISM and their semantics will be discussed shortly.
Nondeterminism
Many of the model types supported by PRISM exhibit nondeterminism, notably MDPs and their various generalisations, such as PTAs and POMDPs. These models use the notion of a policy (called a strategy in PRISM, and also sometimes referred to as a scheduler or adversary) which defines one possible way of resolving the nondeterministic choices in a model.
For such models, the meaning of the property P bound [ pathprop ] is:
"the probability that pathprop is satisfied meets the bound bound
for all possible policies/strategies".
This means that properties using the P operator effectively reason about the
minimum or maximum probability, over all possible resolutions of nondeterminism,
that a certain type of behaviour is observed.
Numerical properties
It is very often useful to compute the actual probability that some behaviour of a model is observed,
rather than just verifying whether or not the probability is above or below a given bound.
Hence, PRISM allows the P operator to take the following numerical form:
P=? [ pathprop ]
This asks "what is the probability that pathprop is satisfied?"
and returns a numerical rather than a Boolean value.
The S and R operators, discussed later, can also be used in this way.
For nondeterministic models such as MDPs (discussed above), either minimum or maximum probability values can be queried in this way:
Pmin=? [ pathprop ]
Pmax=? [ pathprop ]
which return the minimum and maximum probabilities, respectively, over all policies/strategies. As well as computing an optimal value, PRISM can also generate a strategy that achieves it.
PRISM properties generalise the syntax for expressions in the PRISM language so further numerical properties can be constructed by combining them with arithmetic operators and functions, e.g.:
1 - P=? [ pathprop ]
"the probability that pathprop is not true"
P=? [ F fail_A ] / P=? [ F any_fail ]
"the (conditional) probability that component A eventually fails, given that at least one component fails"
Path properties
PRISM supports a wide range of path properties that can be used with the P operator.
A path property is a formula that evaluates to either true or false for a single path in a model.
Here, we review some of the simpler properties that feature a single temporal operator,
as used for example in the logics PCTL and CSL. Later, we briefly describe how PRISM also supports more complex LTL-style path properties.
The basic different types of path property that can be used inside the P operator are:
X: "next"U: "until"F: "eventually" (sometimes called "future")G: "always" (sometimes called "globally")W: "weak until"R: "release"
In the following sections, we describe each of these temporal operators. We then discuss the (optional) use of time bounds with these operators. Finally, we also discuss LTL-style path properties.
"Next" path properties
The property X prop is true for a path if prop is true in its second state.
An example of this type of property, used inside a P operator, is:
P<0.01 [ X y=1 ]
which is true in a state if "the probability of the expression y=1 being true in the next state is less than 0.01".
"Until" path properties
The property prop1 U prop2 is true for a path if
prop2 is true in some state of the path and prop1 is true in all preceding states.
A simple example of this would be:
P>0.5 [ z<2 U z=2 ]
which is true in a state if "the probability that z is eventually equal to 2, and that z remains less than 2 up until that point, is greater than 0.5".
"Eventually" path properties
The property F prop is true for a path if prop eventually becomes true at some point along the path. The F operator is in fact a special case of the U operator (you will sometimes see F prop written as true U prop). A simple example is:
P<0.1 [ F z>2 ]
which is true in a state if "the probability that z is eventually greater than 2 is less than 0.1".
"Globally" path properties
Whereas the F operator is used for "reachability" properties, G represents "invariance". The property G prop is true of a path if prop remains true at all states along the path. Thus, for example:
P>=0.99 [ G z<10 ]
states that, with probability at least 0.99, z never exceeds 10.
"Weak until" and "release" path properties
Like F and G, the operators W and R are derivable from other temporal operators.
Weak until (a W b), which is equivalent to (a U b) | G a, requires that a remains true until b becomes true, but does not require that b ever becomes true (i.e., a remains true forever). For example, a weak form of the until example used above is:
P>0.5 [ z<2 W z=2 ]
which states that, with probability greater than 0.5, either z is always less than 2, or it is less than 2 until the point where z is 2.
Release (a R b), which is equivalent to !(!a U !b), informally means that b is true until a becomes true, or b is true forever.
Time-bounded path properties
All of the temporal operators given above, with the exception of X,
have time-bounded variants, where an additional bound is imposed on
the time taken for the property to be satisfied.
For discrete-time models (e.g., DTMCs and MDPs), this is a step bound,
counting the number of transitions that have occurred,
often also referred to as finite-horizon properties
(as opposed to the "infinite-horizon" properties).
For continuous-time models (notably CTMCs), this is a bound the actual time elapsed.
The most common case is to use an upper time bound, i.e., of the form "<=t" or "<t", where t is a PRISM expression evaluating to a constant, non-negative value.
For example, a bounded until property prop1 U<=t prop2, is satisfied along a path if prop2 becomes true within t steps and prop1 is true in all states before that point.
A typical example of this would be:
P>=0.98 [ y<4 U<=7 y=4 ]
which is true in a state if "the probability of y first exceeding 3 within 7 time units is greater than or equal to 0.98". Similarly:
P>=0.98 [ F<=7 y=4 ]
is true in a state if "the probability of y being equal to 4 within 7 time units is greater than or equal to 0.98" and:
P>=0.98 [ G<=7 y=4 ]
is true if the probability of y staying equal to 4 for 7 time units is at least 0.98.
The time bound can be an arbitrary (constant) expression, but note that you may need to bracket it, as in the following example:
P>=0.98 [ G<=(2*k+1) y=4 ]
You can also use lower time-bounds (i.e. >=t or >t) and time intervals [t1,t2], e.g.:
P>=0.98 [ F>=10 y=4 ]
P>=0.98 [ F[10,20] y=4 ]
which refer to the probability of y becoming equal to 4 after 10 or more time units, and after between 10 and 20 time-units respectively.
For CTMCs, the time bounds can be any (non-negative) numerical values - they are not restricted to integers, as for discrete-time models. For example:
P>=0.25 [ y<=1 U<=6.5 y>1 ]
means that the probability of y being greater than 1 within 6.5 time-units (and remaining less than or equal to 1 at all preceding time-points) is at least 0.25.
Transient probabilities
We can also use the bounded F operator to refer to a single time instant, e.g.:
P=? [ F[10,10] y=6 ]
or, equivalently:
P=? [ F=10 y=6 ]
both of which give the probability of y being 6 at time instant 10.
LTL-style path properties
PRISM supports probabilistic model checking of the temporal logic LTL (and, in fact, PCTL*). LTL provides a richer set of path properties for use with the P operator, by permitting temporal operators to be combined. Here are a few examples of properties expressible using this functionality:
P>0.99 [ F ( "request" & (X "ack") ) ]
"with probability greater than 0.99, a request is eventually received, followed immediately by an acknowledgement"
P>=1 [ G F "send" ]
"a message is sent infinitely often with probability 1"
P=? [ F G ("error" & !"repair") ]
"the probability of an error occurring that is never repaired"
Note that logical operators have precedence over temporal ones, so you will often need to include parentheses when using logical operators, e.g.:
P=? [ (F "error1") & (F "error2") ]
For temporal operators, unary operators (such as F, G and X) have precedence over binary ones (such as U). Unary operators can be nested, without parentheses, but binary ones cannot.
So, these are allowed:
P=? [ F X X X "a" ]
P=? [ "a" U X X X "error" ]
P=? [ ("a" U "b") U "c" ]
but this is not:
P=? [ "a" U "b" U "c" ]
The S operator
The S operator is used to reason about the steady-state behaviour of a model,
i.e., its behaviour in the long-run or equilibrium.
PRISM only provides support for DTMCs and CTMCs.
The definition of steady-state (long-run) probabilities for finite DTMCs and CTMCs is well defined (see e.g. [Ste94]).
Informally, the property:
S bound [ prop ]
is true in a state s of a DTMC or CTMC if
"starting from s, the steady-state (long-run) probability of being in a state which satisfies the (Boolean-valued) PRISM property prop, meets the bound bound".
A typical example of this type of property would be:
S<0.05 [ queue_size / max_size > 0.75 ]
which means: "the long-run probability of the queue being more than 75% full is less than 0.05".
Like the P operator, the S operator can be used in a numerical form, which returns the actual probability value, e.g.:
S=? [ queue_size / max_size > 0.75 ]
and can be further customised with the use of filters.
Reward-based properties
PRISM models can be augmented with information about rewards (or, equivalently, costs).
The tool can then analyse properties which relate to the expected values of these rewards.
This is achieved using the R operator, which works in a similar fashion to the
P and S operators, and can be used either in a Boolean-valued query, e.g.:
R bound [ rewardprop ]
where bound takes the form <r, <=r, >r or >=r for an expression r evaluating to a double,
or a real-valued query, e.g.:
R query [ rewardprop ]
where query is =?, min=? or max=?.
In the latter case, filters can be used, as for the P and S operators.
Informally, "R bound [ rewardprop ]" is true in a state of a model if
"the expected reward associated with rewardprop of the model when starting from that state"
meets the bound bound and "R query [ rewardprop ]" returns the actual expected reward value.
There are various different types of reward properties:
- "reachability reward":
F prop - "co-safe LTL reward": e.g.
F (prop1 & (F prop2)) - "cumulative reward":
C<=t - "total reward":
C - "instantaneous reward":
I=t - "steady-state reward":
S
Below, we consider each of these cases in turn. The descriptions here are kept relatively informal. Precise definitions for most of these can be found in, for example, [KNP07a] (for DTMCs and CTMCs) or [FKNP11] (for MDPs).
For all but instantaneous reward properties, it is required that rewards are non-negative.
"Reachability reward" properties
"Reachability reward" properties associate a reward with each path of a model. More specifically, they refer to the reward accumulated along a path until a certain point is reached. The manner in which rewards are accumulated depends on the model type. For DTMCs and MDPs, the total reward for a path is the sum of the state rewards for each state along the path plus the sum of the transition rewards for each transition between these states. The situation for CTMCs is similar, except that the state reward assigned to each state of the model is interpreted as the rate at which rewards are accumulated in that state, i.e., if t time units are spent in a state with state reward r, the reward accumulated in that state is r x t. Hence, the total reward for a path in a CTMC is the sum of these products for each state along the path plus the sum of the transition rewards for each transition between these states.
The reward property "F prop" corresponds to the reward accumulated along a path
until a state satisfying property prop is reached,
where rewards are accumulated as described above.
State rewards for the prop-satisfying state reached are not included in the accumulated value.
In the case where the probability of reaching a state satisfying prop is less than 1, the reward is equal to infinity.
A common application of this type of property is the case when the rewards associated with the model correspond to time. One can then state, for example:
R<=9.5 [ F z=2 ]
which is true in a state if "the expected time taken to reach a state where z equals 2 is less than or equal to 9.5".
"Co-safe LTL reward" properties
These generalise the "reachability" properties above. Again, reward is accumulated along a path up until some point,
but this is specified in a more general way, by giving a formula in the co-safe fragment of linear temporal logic (LTL).
Rewards are accumulated up until the point where the formula is first satisfied. For example, this property, for a DTMC or CTMC,
queries the expected reward accumulated until first goal equals 1 and then subsequently goal equals 2:
R=? [ F (goal=1 & F goal=2) ]
and this property, for an MDP, minimises the expected reward until loc equals 1,
having passed only through states where loc never equals 4:
Rmin=? [ loc!=4 U loc=1 ]
As for reachability rewards, if the probability of satisfying the formula is less than 1, then the expected reward is defined to be infinite.
Intuitively, a co-safe formula is one that is satisfied within a finite period of time,
and remains true for ever once it becomes true for the first time.
For simplicity, PRISM actually supports the syntactic co-safe fragment of LTL,
which is defined as any LTL formula that only uses the temporal operators F, U and X
(but not G, for example).
PRISM's notation for LTL formulas is described in "LTL-style path properties".
"Cumulative reward" properties
"Cumulative reward" properties also associate a reward with each path of a model,
but only up to a given time bound.
The property C<=t corresponds to the reward accumulated along a path
until t time units have elapsed.
For DTMCs and MDPs, the bound t must evaluate to an integer;
for CTMCs, it can evaluate to double.
State and transition rewards along a path are accumulated exactly as described in the previous section.
A typical application of this type of property is the following. Consider a model of a disk-drive controller which includes a queue of incoming disk requests. If we assign a reward of 1 to each transition of the model corresponding to the situation where an incoming request is lost because the queue is full, then the property:
R=? [ C<=15.5 ]
would return, for a given state of the model, "the expected number of lost requests within 15.5 time units of operation".
"Total reward" properties
"Total reward" properties refer to the accumulation of state and transition rewards in the same way as for "reachability reward" and "cumulative reward" properties, but the reward is accumulated indefinitely, i.e., the total reward accumulated along the whole (infinite) path. Note that this means that, unless a path ends up remaining forever in states with zero reward, the total reward will be infinite.
Re-using the reward structure in the previous example,
R=? [ C ]
returns "the expected total number of lost requests".
"Instantaneous reward" properties
"Instantaneous reward" properties refer to the reward of a model at a particular instant in time.
The reward property I=t associates with a path the reward in the state
of that path when exactly t time units have elapsed.
For DTMCs and MDPs, the bound t must evaluate to an integer;
for CTMCs, it can evaluate to double.
Returning to our example from the previous section of a model for a disk-request queue in a disk-drive controller, consider the case where the rewards assigned to each state of the model give the current size of the queue in that state. Then, the following property:
R<4.4 [ I=100 ]
would be true in a state of the model if "the expected queue size exactly 100 time units later is less than 4.4". Note that, for this type of reward property, state rewards for CTMCs do not have to refer to rates; they can refer to any instantaneous measure of interest for a state.
"Steady-state reward" properties
Unlike the previous types of property, "steady-state reward" properties relate not to paths, but rather to the reward in the long-run. A typical application of this type of property would be, in the case where the rewards associated with the model correspond to power consumption, the property:
R<=0.7 [ S ]
which is true in a state s if "starting from s, the long-run average power consumption is less than 0.7". As for the S operator, these properties are only supported for DTMCs and CTMCs.
Which reward structure?
In the case where a PRISM model has multiple reward structures you may need to specify which reward structure your property refers to. This is done by placing the information in braces ({}) after the R operator. You can do so either using the name assigned to a reward structure (if any) or using the index (where 1 means the first reward structure in the PRISM model file, 2 the second, etc.). Examples are:
R{"num_failures"}=? [ C<=10.0 ]
R{"time"}=? [ F step=final ]
R{2}=? [ F step=final ]
Note that when using an index to specify the reward structure, you can actually put any expression that evaluates to an integer. This allows you to, for example, write a property of the form R{c}=?[...] where c is an undefined integer constant. You can then vary the value of c in an experiment and compute values for several different reward structures at once.
If you don't specify a reward structure to the R operator, by default, the first one in the model file is used.
Discounts
For the reward operators that refer to accumulated rewards,
i.e., F prop, C<=t and C,
rewards on DTMCs and MDPs can be discounted using a specified factor. Examples are:
Rmin=? [ F{discount=0.9} "goal" ]
R=? [ C{discount=0.5}<=100 ]
Rmax=? [ C{discount=0.9} ]
With a discount factor R=? [ C{discount=d}<=k ] gives, for a state
where C<=k.
For MDPs, the value is minimised or maximised over strategies, as for other reward properties.
Multi-objective properties
For MDPs, PRISM supports multi-objective properties. Consider a property that uses the P operator. For example:
P<0.01 [ F "error" ]
This states that, for all strategies (or policies) of the MDP, the probability of reaching an "error" state is less than 0.01.
Multi-objective queries differ in two important ways. Firstly, (by default) they ask about the existence of a strategy. Secondly they refer to multiple properties of a strategy. For example:
multi(P<0.01 [ F "error1" ], P<0.02 [ F "error2" ])
means: "does there exist a strategy of the MDP under which the probability of reaching an "error1" state is less than 0.01 and the probability of reaching an "error2" state is less than 0.02?"
To use the terminology from [FKP12], the above is an "achievability" query (i.e., is this combination of objectives achievable by some strategy?). PRISM also supports two other kinds of multi-objective query: "numerical" and "Pareto" queries.
A "numerical" query looks like:
multi(Pmin=? [ F "error1" ], P<0.02 [ F "error2" ])
meaning "what is the minimum possible probability of reaching "error1", over all strategies of the MDP for which the probability of reaching "error2" is less than 0.02?".
A "Pareto" query leaves both of the objectives unbounded, e.g.:
multi(Pmin=? [ F "error1" ], Pmin=? [ F "error2" ])
This asks PRISM to compute (approximately), the Pareto curve for this pair of objectives. Intuitively, this is the set of pairs of probabilities (of reaching "error1"/"error2") such that reducing one probability any more would necessitate an increase in the other probability.
Types of objectives
For simplicity, the examples above all refer to the probability of reaching classes of states in the model. Other types of property (objective) are also possible.
Firstly, we can extend the examples above by referring to the probability of any LTL property. For example:
multi(Pmax=? [ G "good1" ], P>=0.9 [ G F "good2" ])
"What is the maximum probability of staying forever in "good1" states, such that the probability of visiting "good2" states infinitely often remains at least 0.9?".
We can also use more than 2 objectives, e.g.:
multi(Pmax=? [ G "good1" ], P>=0.9 [ G F "good2" ], P>=0.95 [ G F "good3" ])
"What is the maximum probability of staying forever in "good1" states, such that the probability of visiting "good2" states infinitely often remains at least 0.9 and the probability of visiting "good3" states infinitely often remains at least 0.95?".
Multi-objective queries can also refer to the expected total cumulative value of a reward structure. We write such properties in the form:
multi(R{"time"}min=?[ C ], R{"energy"}<=1.45 [ C ])
"What is the minimum expected cumulative value of reward structure "time", such that the expected cumulative value of reward structure "energy" is below 1.45?"
Note that this C reward operator differs from the F "target" operator, usually used for standard (single-objective) MDP model checking. Whereas the F "target" operator refers to the expected reward accumulated until a "target" state is reached, the C operator refers to the expected total reward.
A few important notes regarding rewards:
- Only transition rewards are supported; state rewards are not.
- Certain assumptions are made regarding the finiteness of rewards; see p.7 of [FKP12] for details.
Finally, time-bounded variants of both probabilistic reachability and expected cumulative rewards objectives can be used. Here is an example that uses the latter:
multi(R{"power"}min=? [ C<=k ], R{"queue"}<=r [ C<=k ])
Solution methods
PRISM can perform multi-objective model checking using two distinct solution methods,
which are described in [FKN+11] and [FKP12].
The former is based on the use of linear programming;
the latter reduces multi-objective model checking to a sweep over a series of simpler problems,
each solved using value iteration (or the Gauss-Seidel variant of value iteration).
The default is "Value iteration". You can change this in the GUI using the option "MDP multi-objective solution methods", or using the command-line switches -lp, -valiter, -gs.
There are some restrictions
- Multi-objective queries are implemented in the sparse engine only. If the hybrid engine is selected, PRISM switches to the sparse engine automatically; the MTBDD and explicit engines are not supported.
- Linear programming does not support time-bounded objectives or Pareto queries; use value iteration for these.
- Values are only computed from a single initial state.
- Fairness and interval iteration are not supported.
Non-probabilistic properties
PRISM also supports model checking of the non-probabilistic temporal logics CTL (computation tree logic) and LTL (linear temporal logic).
Properties in these logics use the A (for all) and E (there exists) operators,
instead of the probabilistic P operator used in many other properties supported by PRISM.
They can be checked on any model type, including
non-probabilistic models such as labelled transition systems (LTSs).
Properties take the form:
A [ pathprop ]
E [ pathprop ]
which are true in a state s of a model if
"path property pathprop is satisfied by all paths from state s"
and
"path property pathprop is satisfied by some path from state s",
respectively.
The syntax for LTL formulas is the same as that allowed within the P operator.
Example properties include:
// There exists a path that reaches a state satisfying "goal"
E [ F "goal" ];

// Variable x is always at most 10 along all paths of the model
A [ G x<=10 ];

// There exists a path along which label "ready" eventually becomes true
// and label "launch" is true immediately afterwards
E [ F "ready" & (X "launch") ];

// Along all paths, either x=1 or x=2 is true infinitely often
A [ (G F x=1) | (G F x=2) ];
Counterexamples and witnesses
If you check a CTL property of the form A [ G "inv" ] and it is false, PRISM will generate a counterexample in the form of a path that reaches a state where "inv" is not true. This is displayed either in the simulator (from the GUI) or at the command-line. Similarly, if you check E [ F "goal" ] and the result is true, a witness (a path reaching a "goal" state) will be generated.
Filters
A property in the PRISM property language is evaluated with respect to a particular state of a model, and can yield a value of various types (Boolean, numerical, etc.), depending on the type of property. When performing model checking, PRISM often computes the value of a property for all states of the model, but typically just reports the result as a single value. Usually, this is the value for the (single) initial state of the model. For example, this:
P=? [ F "error" ]
will report the probability, from the initial state of the model, of reaching an "error" state. This:
P>0.5 [ F "error" ]
will return true if and only if the probability, from the initial state, is greater than 0.5.
For models with multiple initial states, we need to adapt these definitions slightly. In this case, the two properties above will yield, respectively:
- the range of values (over all initial states) of the probability of reaching "error"
trueif and only if the probability is greater than 0.5 from all initial states.
Using filters, you can ask PRISM to obtain different results.
This is done using filter properties, which have the form:
filter(op, prop, states)
where op is the filter operator (see below), prop is any PRISM property and states is a Boolean-valued expression identifying a set of states over which to apply the filter.
In fact, the states argument is optional; if omitted, the filter is applied over all states. So, the following properties are equivalent:
filter(op, prop)
filter(op, prop, true)
Here's a simple example of a filter:
filter(max, P=? [ F "error" ], x=0)
This gives the maximum value, starting from any state satisfying x=0, of the probability of reaching an "error" state.
Here's another simple example, which checks whether, starting from any reachable state, we eventually reach a "done" state with probability 1.
filter(forall, P>=1 [ F "done" ])
We could modify this property slightly to instead check whether, from any state that satisfies the label "ready", we eventually reach a "done" state with probability 1. This could be done with either of the following two equivalent properties:
filter(forall, "ready" => P>=1 [ F "done" ])
filter(forall, P>=1 [ F "done" ], "ready")
Filter operators
Most filters of the form filter(op, prop, states)
apply some operator op to the values of property prop
for all the states satisfying states,
resulting in a single value.
The full list of filter operators op in this category is:
min: the minimum value ofpropover states satisfyingstatesmax: the maximum value ofpropover states satisfyingstatescount: counts the number of states satisfyingstatesfor whichpropis truesum(or+): sums the value ofpropfor states satisfyingstatesavg: the average value ofpropover states satisfyingstatesfirst: the value ofpropfor the first (lowest-indexed) state satisfyingstatesrange: the range (interval) of values ofpropover states satisfyingstatesforall(or&): returnstrueifpropistruefor all states satisfyingstatesexists(or|): returnstrueifpropistruefor some states satisfyingstatesstate: returns the value for the single state satisfyingstates(if there is more than one, this is an error)
There are also a few filters that, rather than returning a single value, return different values for each state, like a normal PRISM property:
argmin: returnstruefor the states satisfyingstatesthat yield the minimum value ofpropargmax: returnstruefor the states satisfyingstatesthat yield the maximum value ofpropprint: does not change the result ofpropbut prints the (non-zero) values to the logprintall: likeprint, but displays all values, even for states where the value is zero
Examples
Here are some further illustrative examples of properties that use filters.
Filters provide a quick way to print the results of a model checking query for several states. In most cases, for example, a P=? query just returns the probability from the initial state. To see the probability for all states satisfying x>2, use:
filter(print, P=? [ ... ], x>2)
Values are printed in the log (i.e. to the "Log" tab in the GUI or to the terminal from the command-line). For small models, you could omit the final states argument (x>2 here) and view the probabilities from all states. You can also use PRISM's verbose mode to view values for all states, but filters provide an easier and more flexible solution.
print filters do not actually alter the result returned so, in the example above, PRISM will still return the probability for the initial state, in addition to printing other probabilities in the log.
You can also use print filters to display lists of states. For example, this property:
filter(print, filter(argmax, P=? [ F "error" ]))
prints the states which have the highest probability of reaching an error state.
However, you should exercise caution when using argmax (or argmin) on properties such as P=? [ ... ] (or S=? [ ... ] or R=? [ ... ]), whose results are only approximate due to the nature of the methods used to compute them (or because of round-off errors.)
Another common use of filters is to display the value for a particular state of the model (rather than the initial state, which is used by default). To achieve this, use e.g.:
filter(state, P=? [ F "error" ], x=2&y=3)
where x=2&y=3 is assumed to specify one particular state.
A state filter will produce an error if the filter expression is not satisfied by exactly one state of the model.
Filters can also be built up into more complex expressions. For example, the following two properties are equivalent:
filter(avg, P=? [ F "error" ], "init")
filter(sum, P=? [ F "error" ], "init") / filter(count, "init")
The range filter, unlike most PRISM expressions which are of type Boolean, integer or double, actually returns an interval: a pair of integers or doubles. For example:
filter(range, P=? [ F count=10 ], count=0)
gives the range of all possible values for the probability of reaching a state satisfying count=10, from all states satisfying count=0.
This kind of value also results from numerical properties on models with multiple initial states (see above).
Default filters
Finally, for completeness, we show what the default filters are in PRISM, i.e. how the way that PRISM returns values from properties by default could have been achieved equivalently using filters.
Queries of the form:
P>0.5 [ F "error" ]
are the same as:
filter(forall, P>0.5 [ F "error" ], "init")
and queries of the form:
P=? [ F "error" ]
are the same as either:
filter(state, P=? [ F "error" ], "init")
filter(range, P=? [ F "error" ], "init")
for the cases where the model has a single initial state or multiple initial states, respectively.
Extended model types
Most of this manual describes PRISM's core model types: discrete-time Markov chains (DTMCs), continuous-time Markov chains (CTMCs) and Markov decision processes (MDPs). This section covers features of the PRISM modelling language that allow it to specify a wider range of model types, including non-probabilistic ones. Each page describes how such models are written in the PRISM language, which properties can be checked for them, and how they are analysed, including any restrictions.
Contents
- Real-time models: using real-valued clocks to represent time, notably probabilistic timed automata (PTAs)
- Partially observable models: where strategies only see observations of the state, notably partially observable Markov decision processes (POMDPs)
- Uncertain models: where transition probabilities are not fully known, such as interval discrete-time Markov chains (IDTMCs) and interval Markov decision processes (IMDPs)
- Non-probabilistic models: models with no probabilities, notably labelled transition systems (LTSs)
Real-time models
PRISM supports real-time models, in particular, probabilistic timed automata (PTAs), which extend MDPs with the ability to model real-time behaviour. This is done in the style of timed automata [AD94], by adding clocks, real-valued variables modelling the elapse of time.
The state of a PTA is made up of its clocks, plus other variables.
The non-clock part of the state is often called the location of the PTA.
The values of the clock variables are assumed to increase at the same rate, as time elapses.
But the model can also include clock resets, which reset a clock's
value to a (non-negative integer) value, usually 0, at certain points.
Transitions of the model between its locations can be made dependent on the values of the clocks: clock invariants dictate the range of values within which clocks must stay for each location before moving to another location; clock guards can be used to restrict transitions to when clocks have certain values.
For background material on PTAs, see for example [NPS13].
You can also find several example PTA models included in the PRISM distribution. Look in the prism-examples/ptas directory.
Modelling
Here is a simple example of a PTA, modelled in PRISM.
It represents a system that attempts to send a message,
which happens at a time instant in the range [1,2]
and succeeds with probability 0.9.
In the case of failure, it then repeatedly retries to send the message,
waiting for a delay in the range [2,3] each time.
// A simple PTA model with a single clock x

pta

module M

    s : [0..2] init 0; // 0=send, 1=success, 2=retry
    x : clock;

    invariant
        (s=0 => x<=2) &
        (s=2 => x<=3)
    endinvariant

    [send] s=0 & x>=1 -> 0.9:(s'=1)&(x'=0) + 0.1:(s'=2)&(x'=0);
    [retry] s=2 & x>=2 -> 0.95:(s'=1) + 0.05:(s'=2)&(x'=0);

endmodule
The model type is indicated as pta at the top of the file
(in fact PRISM will also detect an MDP model with clock variables and treat it as a PTA).
Clocks use the variable type clock, and are declared in the same way as other variables.
This example uses a single clock variable x.
Other variables can be declared in the usual way and make up the rest of the state of the model (its location).
In the example above, we use just a single integer variable s with range [0..2].
Clock guards are embedded within the usual guarded command notation
(see, for example, the inclusion of x>=1 in the guard for the send-labelled command).
Clock resets are included with the variable updates of commands
(see, for example, the instances of (x'=0) in the example).
Additionally, an invariant construct in each module, placed after its variable declarations,
specifies clock invariants as an expression over clocks and other variables.
The format used in the example (a conjunction of implications)
is a convenient way to specify a separate clock invariant for each PTA location.
In the example, the clock x must satisfy x<=2 or x<=3
when local variable s is 0 or 2, respectively.
If s is 1, there is no restriction
(since the invariant is effectively true in this case).
The resulting PTA is shown below, where states (locations) are identified by the value of s.
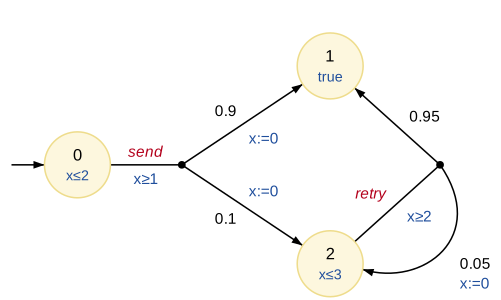
Rewards: PTA models can include reward structures in the same way as MDPs. However, the reward structures for PTAs are restricted to only include state and transition rewards that do not depend on clock variables. Formally, the class of PTAs with this kind of reward structure is sometimes called linearly priced PTAs (see e.g. [KNPS06]).
Restrictions:
Expressions in PTA models that include reference to clocks, whether in guards or invariants, must satisfy certain conditions to facilitate model checking. In particular, references to clocks must appear as conjunctions of simple clock constraints, i.e., conjunctions of expressions of the form x~c or x~y where x and y are clocks, c is an integer-valued expression and ~ is one of <, <=, >=, > or =.
Clock resets must set a clock to a non-negative integer value that is constant,
such as (x'=0) or (x'=K) for an integer constant K:
it cannot depend on the values of other variables or clocks.
PRISM makes several assumptions about PTAs, regardless of the engine used.
-
Firstly, PTAs should not exhibit timelocks, i.e., the possibility of reaching a state where no transitions are possible and time cannot elapse beyond a certain point (due to invariant conditions). PRISM checks for timelocks and reports an error if one is found.
-
Secondly, PTAs should be well-formed and non-zeno (see e.g. [KNSW07] for details). PRISM does not check automatically that these assumptions are satisfied.
There are also some further restrictions, which depend on the engine used: see below.
Properties
The classes of property that can be checked for real-time models are more restricted than for the other kinds of models that PRISM supports. This is because the model checking procedures are quite different for this type of model. The situation also depends on which of the engines is being used.
Broadly speaking, PRISM allows single (non-nested) instances of unbounded or time-bounded probabilistic reachability properties and reachability reward properties, i.e., queries of the form:
Pmin=? [ F target ]
Pmax=? [ F target ]
Pmin=? [ F<=T target ]
Pmax=? [ F<=T target ]
Rmin=? [ F target ]
Rmax=? [ F target ]
where target is a Boolean-valued expression that does not include
references to any clock variables and T is an integer-valued expression.
In some cases (see below), PRISM also allows until (U) properties.
Solution methods
PRISM has three distinct engines that can be used for analysing PTAs.
-
The stochastic games engine uses abstraction-refinement techniques based on stochastic two-player games [KNP09c].
-
The digital clocks engine performs a discretisation, in the form of a language-level model translation, that reduces the problem to one of model checking over a finite-state MDP [KNPS06]. If you want to see the MDP PRISM model that was generated, add the switch
-exportdigital digital.prismwhen model checking a property to export the model file todigital.prism. -
The backwards reachability engine is a zone-based method based on a backwards traversal of the state space and solution of the resulting finite-state MDP [KNSW07].
The default engine for PTAs is "stochastic games". The engine to be used can be specified using the "PTA model checking method" setting in the "PRISM" options panel in the GUI. From the command-line, switch -ptamethod <name> should be used where <name> is either games, digital or backwards.
Restrictions: The choice of engine affects the models that can be analysed, as well as the properties that can be checked.
For the stochastic games and backwards reachability engines:
- The model must have a single initial state (i.e., the
init...endinitconstruct is not permitted). - Only
Pmin=?andPmax=?queries are supported (not, e.g.,P>=0.9); reward properties are not supported. - Filters and the
"init"and"deadlock"labels cannot be used in properties.
Additionally, for the backwards reachability engine:
- Only maximum probabilities are handled.
For the digital clocks engine:
- Until (
U) formulas are also allowed in thePoperator, in addition to reachability (F) formulas. - Properties can refer to clock variables, so
targetis not restricted as above. - Arithmetic expressions in properties, such as
1 - Pmin=? [ F target ], are allowed. - Clock constraints in both models and properties
cannot use strict comparison operators
(e.g.,
x<=5is allowed, butx<5is not). - In both models and properties, diagonal clock constraints are not allowed,
i.e., those containing references to two clocks, such as
x<=y.
Partially observable models
PRISM supports analysis of partially observable probabilistic models, most notably partially observable Markov decision processes (POMDPs), but also partially observable probabilistic timed automata (POPTAs).
POMDPs are a variant of MDPs in which the strategy (or policy) that resolves nondeterministic choices in the model cannot see the precise state of the model, but instead just observations of it. A strategy can therefore only base its choices on the history of observations so far or, equivalently, on a belief: a probability distribution over the states that the model could be in.
For background material on POMDPs and POPTAs, see for example [NPZ17].
You can also find several example models included in the PRISM distribution.
Look in the prism-examples/pomdps and prism-examples/poptas directories.
Modelling
Here is a simple example of a POMDP, modelled in PRISM.
First, a hidden variable h is set randomly to 1, 2 or 3 (with probabilities 0.1, 0.3 and 0.6).
Then, a single guess is made of its value.
// A simple POMDP: guess the value of a hidden variable

pomdp

observables s endobservables

module M

    s : [0..3]; // 0=start, 1=guessing, 2=correct, 3=wrong
    h : [0..3]; // hidden variable

    // Assign hidden variable randomly
    [toss] s=0 -> 0.1:(s'=1)&(h'=1) + 0.3:(s'=1)&(h'=2) + 0.6:(s'=1)&(h'=3);
    // Guess the value of the hidden variable
    [guess1] s=1 -> (s'=(h=1)?2:3);
    [guess2] s=1 -> (s'=(h=2)?2:3);
    [guess3] s=1 -> (s'=(h=3)?2:3);
    // Done
    [done] s>=2 -> true;

endmodule

label "correct" = s=2;
The model type is indicated as pomdp at the top of the file
(in fact PRISM will also detect an MDP model with observables and treat it as a POMDP).
PRISM supports state-based observations:
this means that, upon entering a new POMDP state,
the observation is determined by that state.
In the same way that a model state comprises the values of one or more variables,
an observation comprises one or more observables.
In the example above, only the variable s is observable;
the hidden variable h is not.
The resulting POMDP is shown below. The three states in which the guess is made
all have the same observation (s=1), so a strategy cannot distinguish between them
and must make the same guess in each one.
For clarity, the final states are shown merged, since the value of h no longer matters there.
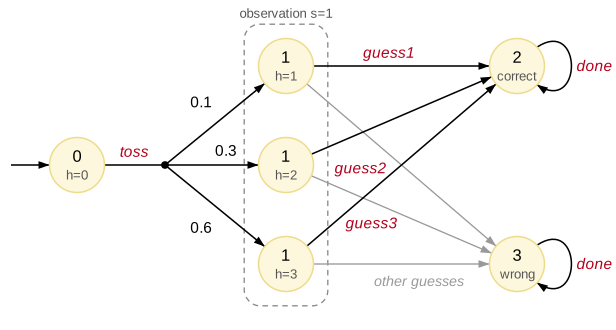
There are several ways to define observables.
The simplest, used above, is to specify a subset of the model's variables
that are designated as being observable. The rest are unobservable.
For example, in a POMDP with 3 variables, s, l and h, the following:
observables s, l endobservables
specifies that s and l are observable and h is not.
Alternatively, observables can be specified as arbitrary expressions over variables.
For example, assuming the same variables s, l and h, this specification:
observable "s" = s;
observable "pos" = l>0;
defines 2 observables. The first is, as above, the variable s.
The second, named "pos", determines if variable l is positive.
Other than this, the values of l and h are unobservable.
The above two styles of definition can also be mixed to specify a combined set of observables.
POPTAs:
Partially observable PTAs (POPTAs) combine the features of both PTAs and POMDPs.
The model type is indicated as popta
(PRISM will also detect a PTA model with observables and treat it as a POPTA).
For a POPTA, all clock variables must be observable.
Properties
For partially observable models (POMDPs and POPTAs),
PRISM uses the same property language as their fully observable equivalents (MDPs and PTAs).
However, a more limited range of properties is available.
For POMDPs, PRISM supports probabilistic reachability,
probabilistic until, probabilistic invariance (G) or expected reachability rewards properties, i.e.:
Pmin=? [ F target ]
Pmax=? [ F target ]
Pmin=? [ remain U target ]
Pmax=? [ remain U target ]
Pmin=? [ G safe ]
Pmax=? [ G safe ]
Rmin=? [ F target ]
Rmax=? [ F target ]
or variants with a probability or reward bound (e.g., P>=0.5)
instead of the min=? or max=?.
The expressions such as target, remain and safe above
can, as usual, refer to labels
(with some restrictions, see below)
but also to additional named observables defined in the model
(e.g., "pos" in the example above).
An example property for the guess.prism model above is:
// Maximum probability of guessing the value correctly
Pmax=? [ F "correct" ]
This yields a result of 0.6: the best strategy is always to guess the most likely value (3).
In an MDP, where h would be visible, the probability would be 1.
Restrictions: There are some additional constraints on properties for partially observable models:
- The
target(andremainorsafe) expression in the property must be observable. In other words, if any state of the POMDP satisfies the expression, then all other observationally equivalent states must also satisfy it. This is easily achieved by only using either observable variables or named observables in the expression, but that is not required. - Values are only computed from a single initial state.
- Time-bounded properties (e.g.,
F<=k) and nested properties are not supported.
POPTAs are verified using the "digital clocks" approach to translate them into a POMDP, so the same restrictions apply, as well as those of the digital clocks engine (e.g., strict or diagonal clock comparisons are not allowed). However, for POPTAs, time-bounded probabilistic reachability is also supported.
Solution methods
POMDPs are analysed with the explicit engine,
which PRISM switches to automatically.
The method used is a fixed-resolution grid approximation of the (infinite) belief MDP [Lov91],
as described in [NPZ17].
The resolution of the grid is set with the -gridresolution switch (default 10).
Higher values give more accurate results, at the expense of time and memory.
Since the result is approximate, PRISM computes two bounds on the true value: an outer bound, from the grid approximation, and an inner bound, from the strategy that the approximation generates. Both are shown in the log, and the result is reported as the interval between them, e.g.:
prism guess.prism guess.props
 ...
 Outer bound: 0.6 (exact floating point)
 Inner bound: 0.6 (exact floating point)
 Result bounds: [0.6,0.6]
If the bounds are far apart, try increasing the grid resolution.
The generated strategy can be exported or viewed, as for MDPs (see Strategies). It maps beliefs (rather than states) to actions.
Uncertain models
PRISM has support for uncertain models, in which there is epistemic uncertainty regarding some quantitative aspects of the probabilistic models being verified. In particular, it supports interval MDPs (IMDPs) and interval DTMCs (IDTMCs), which are MDPs or DTMCs in which transition probabilities are specified as intervals, indicating that the exact probability is not precisely known. This can be useful, for example, when the transition probabilities have been estimated from data.
You can find some example models included in the PRISM distribution.
Look in the prism-examples/imdps and prism-examples/idtmcs directories.
Modelling
Here is a simple example of an IMDP, modelled in PRISM.
A robot can choose between two routes to a goal:
a fast route, whose probability of success is only known to lie in the range [0.7,0.9],
and a slower route, whose probability of success is known to be 0.8.
// A simple IMDP: a robot chooses between a fast route with
// an uncertain chance of success and a slower but reliable one

mdp

module M

    s : [0..3]; // 0=start, 1=slow route, 2=goal, 3=crash

    [fast] s=0 -> [0.7,0.9]:(s'=2) + [0.1,0.3]:(s'=3);
    [slow] s=0 -> (s'=1);
    [slow] s=1 -> 0.8:(s'=2) + 0.2:(s'=3);
    [done] s>=2 -> true;

endmodule

label "goal" = s=2;
Intervals are used by simply replacing the probabilities attached to updates in commands
with intervals, such as [0.7,0.9] above.
Single values (e.g., 0.8 in the example) are treated as single-point intervals ([0.8,0.8]).
There is no separate model type keyword for interval models:
a dtmc or mdp model containing intervals is treated as an IDTMC or IMDP, respectively.
Intervals can also be used in POMDPs, giving interval POMDPs (IPOMDPs),
but these can only be built, not model checked.
The resulting IMDP is shown below.
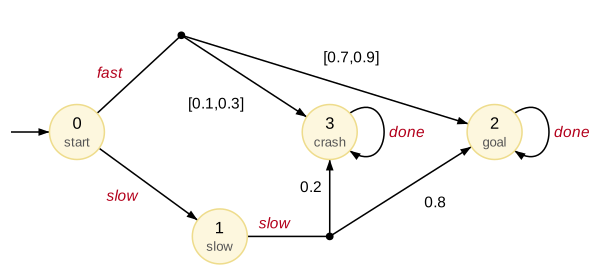
As usual, the interval bounds can be expressions involving constants or state variables, for example:
[] x=0 -> [p,p+0.1]:(x'=0) + [0.9-p,1-p]:(x'=1);
The intervals in each command must allow at least one probability distribution, i.e., the lower bounds must sum to at most 1 and the upper bounds to at least 1. PRISM checks this when the model is built and reports an error otherwise.
When two commands in different modules synchronise and specify the probabilities for updates to variables as intervals, these are considered to be independent, i.e., the probability of each combined transition is taken to be the product of the two component intervals.
Properties
For uncertain models, PRISM performs robust verification, which considers the best- or worst-case behaviour that can arise depending on the way that probabilities are selected from intervals.
For example, instead of a property for a DTMC such as
P=? [ F "goal" ]
which asks for the probability to reach a state satisfying "goal", IDTMCs use MDP-style queries:
Pmin=? [ F "goal" ]
Pmax=? [ F "goal" ]
which compute the minimum or maximum possible probability that can arise.
For an IMDP, there are two separate quantifications,
firstly over strategies (policies) and secondly over the distinct ways
that transition probabilities can be selected from intervals.
For these, min or max appear in that order in the query.
For example, for the IMDP above:
// Maximum probability of reaching the goal (worst case)
Pmaxmin=? [ F "goal" ];

// Maximum probability of reaching the goal (best case)
Pmaxmax=? [ F "goal" ];
The first property asks for the maximum probability of reaching the goal,
assuming the worst case for the uncertain probabilities;
the result is 0.8, achieved by taking the slow route.
The second assumes the best case instead;
the result is 0.9, achieved by taking the fast route.
Similarly, minmin and minmax are used for the minimum probability of reaching "goal".
If only one of min or max is given (e.g., Pmax=?), it is used for both.
Model checking is supported for:
- the
Poperator, including single temporal operators and LTL formulae - the
Roperator, for the expected reward to reach a target or satisfy a co-safe LTL formula, or total (possibly discounted) reward
Solution methods
Uncertain models are analysed with the explicit engine,
which PRISM switches to automatically.
The method used is robust value iteration,
which is like the value iteration used for MDPs,
except that each iteration also finds the best or worst probabilities within the intervals.
By default, the Gauss-Seidel variant is used;
standard value iteration can be selected with the -valiter switch
(or the "IMDP/DTMC solution method" setting in the GUI).
Strategies can be generated and exported for IMDPs as for MDPs.
For the example above, the strategy chooses slow in state 0 for Pmaxmin=?
and fast for Pmaxmax=?.
Non-probabilistic models
As well as probabilistic models, PRISM supports non-probabilistic models, in particular labelled transition systems (LTSs). An LTS is like an MDP but without probabilities: in each state, there is a nondeterministic choice between one or more transitions, each of which leads to a single successor state.
LTSs can be used to check functional (rather than quantitative) correctness of a system, using the temporal logics CTL and LTL, for example as a first step before adding probabilities to a model.
Modelling
LTSs are modelled using the usual PRISM language features (modules, variables, commands, synchronisation, formulas, labels, etc.), but with no probabilities attached to the updates of commands. Here is a simple example: two processes, each of which can be idle, trying or in a critical section, which use a lock to ensure mutual exclusion.
// Two processes sharing a lock (no probabilities)

module P1

    x : [0..2]; // 0=idle, 1=trying, 2=critical

    [try1] x=0 -> (x'=1);
    [enter1] x=1 -> (x'=2);
    [exit1] x=2 -> (x'=0);

endmodule

module P2 = P1 [ x=y, try1=try2, enter1=enter2, exit1=exit2 ] endmodule

module Lock

    l : bool; // locked?

    [enter1] !l -> (l'=true);
    [enter2] !l -> (l'=true);
    [exit1] l -> (l'=false);
    [exit2] l -> (l'=false);

endmodule

label "both" = x=2 & y=2;
The two processes do not synchronise with each other,
but each one synchronises
with the Lock module when it enters or leaves its critical section:
for example, the action enter1 can only occur when the lock is free (!l),
and it then sets the lock.
There is no model type keyword for LTSs.
If a model has no keyword (which would usually result in the default model of an MDP) and does not use any probabilities, it is treated as an LTS.
If instead it starts with the mdp keyword, it is treated as an MDP
(in which each choice has a single transition with probability 1).
The resulting LTS is shown below, where each state shows the values of x, y and l,
and transitions are labelled with their actions.
Note that the lock is set exactly when one process is in its critical section,
and that there is no state with x=2 and y=2, where both processes are in the critical section.
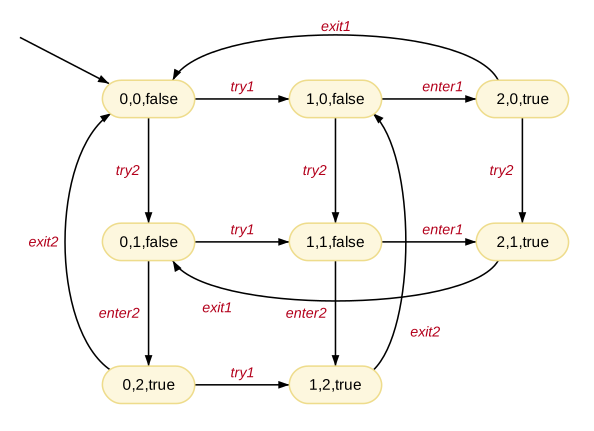
Properties
LTSs can be analysed with non-probabilistic properties,
i.e., CTL and LTL formulas using the A (for all paths) and E (there exists a path) operators.
For example, for the model above:
// The two processes are never both in the critical section
A [ G !"both" ];

// It is possible for process 1 to reach the critical section
E [ F x=2 ];

// Whenever process 1 is trying, it eventually reaches the critical section
A [ G ((x=1) => (F x=2)) ];
The first two properties are true: the protocol ensures mutual exclusion, and process 1 can reach its critical section. The third is false, since process 2 can repeatedly enter its critical section while process 1 waits forever. PRISM does not make any fairness assumptions about the choices in the model.
For some properties, PRISM also generates a counterexample or witness, e.g., a path along which process 1 reaches its critical section for the second property above.
Solution methods
LTSs are analysed with the explicit engine, which PRISM switches to automatically. CTL properties are checked with standard graph-based algorithms and LTL properties by building the product of the LTS with a Büchi automaton.
Running PRISM
There are two versions of PRISM, one based on a graphical user interface (GUI), the other based on a command line interface (CLI). Both use the same underlying model checker. The latter is useful for running large batches of jobs, leaving long-running model checking tasks in the background, or simply for running the tool quickly and easily once you are familiar with its operation.
Details of how to run PRISM can be found in the installation instructions.
In short, to run the PRISM GUI:
- (on Windows) click the short-cut (to
xprism.bat) installed on the Desktop/Start Menu - (on other OSs) run the
xprismscript in thebindirectory
and for the command-line:
- run the
prismscript in thebindirectory
This section describes the main functionality offered by PRISM, from both the GUI and command line.
Contents
- Loading and building a model: loading a model, building it, and dealing with deadlocks
- Model checking: checking properties, in the GUI and on the command line
- Experiments: checking properties for ranges of constants, and plotting the results
- Strategies: generating and exporting strategies (policies) for MDPs and other models
- Simulation: exploring a model step by step, and generating random paths
- Statistical model checking: approximate results by simulation
- Transient and steady-state probabilities: probability distributions over a model's states
- Parametric model checking: results as functions of model parameters
- Importing and exporting models: writing a built model to files, and building one from files
- Other modelling languages: models written in the PEPA process algebra, or in SBML
Loading and building a model
Typically, when using PRISM, the first step is to load a model that has been specified in the PRISM modelling language.
If using the GUI, select menu option "Model | Open Model" and choose a file.
There is a selection of sample PRISM model files in the prism-examples directory of the distribution.
A few very small models are contained in the subdirectory simple;
the rest are in subdirectories grouped by model type.
The model will then be displayed in the editor in the "Model" tab of the GUI window. The file is parsed upon loading. If there are no errors, a green tick will be visible. If there are errors in the file, a red cross will appear instead and the errors will be highlighted in the model editor. To view details of the error, position the mouse pointer over the source of the error (or over the red cross). Alternatively, select menu option "Model | Parse Model" and the error message will be displayed in a message box. Models can be edited or written from scratch in the GUI's editor.
Building the model
In order to perform model checking, PRISM will (in most cases) need to construct the corresponding probabilistic model, i.e., convert the PRISM model description to an MDP, DTMC, etc. During this process, PRISM computes the set of states in the model which are reachable from the initial states and the transition matrix which represents the model.
Model construction is done automatically when you perform model checking. However, you may also want to explicitly ask PRISM to build the model in order to test for errors or to see how large the model is. From the GUI, you can do this by selecting "Model | Build Model". If there are no errors during model construction, the number of states and transitions in the model will be displayed in the bottom left corner of the window.
From the command-line, simply type:
prism model.prism
where model.prism is the name of the file containing the model description.
For some types of models, notably PTAs, models are not constructed in this way (because the models are infinite-state). In these cases, analysis of the model is not performed until model checking is performed.
Deadlocks
You should be aware of the possibility of deadlock states in the model, i.e., states which are reachable but from which there are no outgoing transitions. PRISM will automatically search your model for deadlocks and, by default, "fix" them by adding self-loops in these states. Since deadlocks are sometimes caused by modelling errors, PRISM will display a warning message in the log when deadlocks are fixed in this way.
You can control whether deadlocks are automatically fixed in this way using the "Automatically fix deadlocks" option (or with command-line switches -nofixdl and -fixdl). When fixing is disabled, PRISM will report an error when the model contains deadlocks.
If you have unwanted or unexpected deadlocks in your model, there are several ways you can detect them. Firstly, by disabling deadlock fixing (as described above), PRISM will display a list of deadlock states in the log. Alternatively, you can model check the filter property filter(print, "deadlock"), which has the same effect.
To find out how deadlocks occur, i.e., which paths through the model lead to a deadlock state, there are several possibilities.
Firstly, you can model check the CTL property E[F "deadlock"].
When checked from the GUI, this will provide you with the option of displaying a path to a deadlock in the simulator.
From the command-line, a path to a deadlock will be displayed in the log, for example with:
prism model.prism -pf 'E[F "deadlock"]'
Finally, in the eventuality that the model is too large to be model checked, you can still use the simulator to search for deadlocks. This can be done either by manually generating random paths using the simulator in the GUI or, from the command-line, e.g. by running:
prism dice.prism -simpath deadlock stdout
Model checking
Properties to be checked on a model are specified as described in the "Property specification" section,
and are usually kept in properties files with extension .props.
There are properties files accompanying most of the sample PRISM models in the prism-examples directory.
GUI
A properties file can be loaded into the GUI along with a model when starting it, e.g.:
xprism example.prism example.props
Otherwise, after first loading a model, select menu option "Properties | Open properties list". The file can only be loaded if there are no errors, otherwise an error is displayed. Note that it may be necessary to have loaded the corresponding model first, since the properties will probably make reference to labels, variables or constants declared in the model file. Once loaded, the properties contained in the file are displayed in a list in the "Properties" tab of the GUI. Additional constants and labels defined in the properties file are displayed in separate lists below. You can modify or create new properties, constants and labels from the GUI, by right-clicking on the appropriate list and selecting from the pop-up menu which appears. Properties with errors are shaded red and marked with a warning sign. Positioning the mouse pointer over the property displays the corresponding error message.
The pop-up menu for the properties list also contains a "Verify" option,
which allows you to instruct PRISM to model check the currently selected properties
(hold down Ctrl/Cmd to select more than one property simultaneously).
All properties can be model checked at once by selecting "Verify all".
PRISM verifies each property individually.
Upon completion, the icon next to the property changes according to the result of model checking. For Boolean-valued properties, a result of true or false is indicated by a green tick or red cross, respectively. For properties which have a numerical result (e.g. P=? [ ...]), position the mouse pointer over the property to view the result.
In addition, this and further information about model checking is displayed in the log in the "Log" tab.
Command-line
From the command-line, model checking is achieved by passing both a model file and a properties file as arguments, e.g.:
prism poll2.prism poll.props -const T=10
Here, poll2.prism is a CTMC model of a simple polling system
and the properties file poll.props has a constant T with no value,
which is given here with the -const switch (see "Experiments").
The results of model checking are sent to the display and are as described above for the GUI version.
By default, all properties in the file are checked.
To model check only a single property, use the -prop switch.
For example, to check only the fourth property in the file:
prism poll2.prism poll.props -prop 4
Properties can also be referred to by name.
For example, if a properties file model.props contains a property named "safe", it can be checked on its own with:
prism model.prism model.props -prop safe
You can also provide a comma-separated list of multiple properties to check, using numerical indices, property names or a mix of the two:
prism model.prism model.props -prop 4,5,safe
Alternatively, the contents of a properties file can be specified directly from the command-line, using the -pf switch:
prism poll2.prism -pf 'P>=0.5 [ F<=5 (s=1 & a=0) ]'
The switches -pctl and -csl are aliases for -pf.
Note the use of single quotes ('...') to avoid characters such as
( and > being interpreted by the command-line shell.
Single quotes may be preferable to double quotes since PRISM properties often include double quotes, e.g., for references to labels or properties.
Accuracy of results
The default methods used for model checking in most cases are iterative numerical methods implemented using floating point arithmetic. The accuracy of the resulting values is impacted by both the method chosen and parameters such as the threshold for termination; these are discussed more in the "Configuration and performance" section.
When PRISM prints the result of a (numerical) model checking query, it typically shows an indication of the accuracy too, for example:
prism model.prism model.props
 ...
 Result: 0.15625 (exact floating point)
 ...
 Result: 0.1666666865348816 (+/- 1.1920933218335556E-7; rel err 7.152559078349847E-7)
 ...
 Result: 0.16666650772094727 (+/- 1.1920928955078125E-6 estimated; rel err 7.1525641942636435E-6)
The first result is exact, up to the precision of floating point arithmetic., in this case because it was the result of a step-bounded (finite-horizon) query needing a fixed number of iterations to compute. The second was computed using interval iteration, which is an iterative method but that provides a guaranteed error bound on the result. The third was computed by value iteration, and its error bound is only an estimate, based on the check for convergence.
Here is an example of the output when using the exact engine, which uses arbitrary precision arithmetic to compute precise results:
prism model.prism model.props -ex
 ...
 Result: 1/6 (exact) (~0.16666666666666666)
An approximate decimal value is also shown, for convenience.
Experiments
PRISM supports experiments, which are a way of automating multiple instances of model checking. This is done by leaving one or more constants undefined, e.g.:
const int N;
const double T;
This can be done for constants in the model file, the properties file, or both.
Before any verification can be performed, values must be provided for any such constants. In the GUI, a dialog appears in which the user is required to enter values. From the command line, the -const switch must be used, e.g.:
prism cluster.prism cluster.props -prop 4 -const N=4,T=85.9
Here, the model cluster.prism and properties cluster.props are a CTMC of a workstation cluster and some of its properties,
and -prop 4 checks just the fourth property in the file.
Running experiments
To run an experiment, provide a range of values for one or more of the constants. Model checking will be performed for all combinations of the constant values provided. For example:
prism cluster.prism cluster.props -prop 4 -const N=4:6,T=60:10:100
where N=4:6 means that values of 4,5 and 6 are used for N,
and T=60:10:100 means that values of 60, 70, 80, 90 and 100 (i.e., steps of 10) are used for T.
For convenience, constant specifications can be split across separate instances of the -const switch, if desired.
You can also specify double-valued constants as fractions rather than decimals. For example:
prism cluster.prism cluster.props -prop 4 -const N=4 -const T=1/3
Experiments in the GUI
From the GUI, an experiment is created by selecting a single property, right clicking on it and selecting "New experiment" (or alternatively using the popup menu in the "Experiments" panel). Values or ranges for each undefined constant can then be supplied in the resulting dialog. If you wish, you can tick the "Use Simulation" box at this point to use statistical model checking for the experiment, rather than normal model checking.
Details of the new experiment and its progress are shown in the panel. To stop the experiment before it has completed, click the red "Stop" button and it will halt after finishing the current iteration of model checking. Once the experiment has finished, right clicking on the experiment produces a pop-up menu, from which you can view the results of the experiment or export them to a file.
Plotting graphs
For experiments based on properties which return numerical results, you can also use the GUI to plot graphs of the results. This can be done either before the experiment starts, by selecting the "Create graph" tick-box in the dialog used to create the experiment (in fact this box is ticked by default), or after the experiment's completion, by choosing "Plot results" from the pop-up menu on the experiment. A dialog appears, where you can choose which constant (if there are more than one) to use for the x-axis of the graph, and for which values of any other constants the results should be plotted.
The graph will appear in the panel below the list of experiments. Right clicking on a graph and selecting "Graph options" brings up a dialog from which many properties of the graph can be configured. From the pop-up menu of a graph, you can also choose to print the graph (to a printer or Postscript file) or export it in a variety of formats: as an image (PNG or JPEG), as an encapsulated Postscript file (EPS), in an XML-based format (for reloading back into PRISM), or as code which can be used to generate the graph in Matlab.
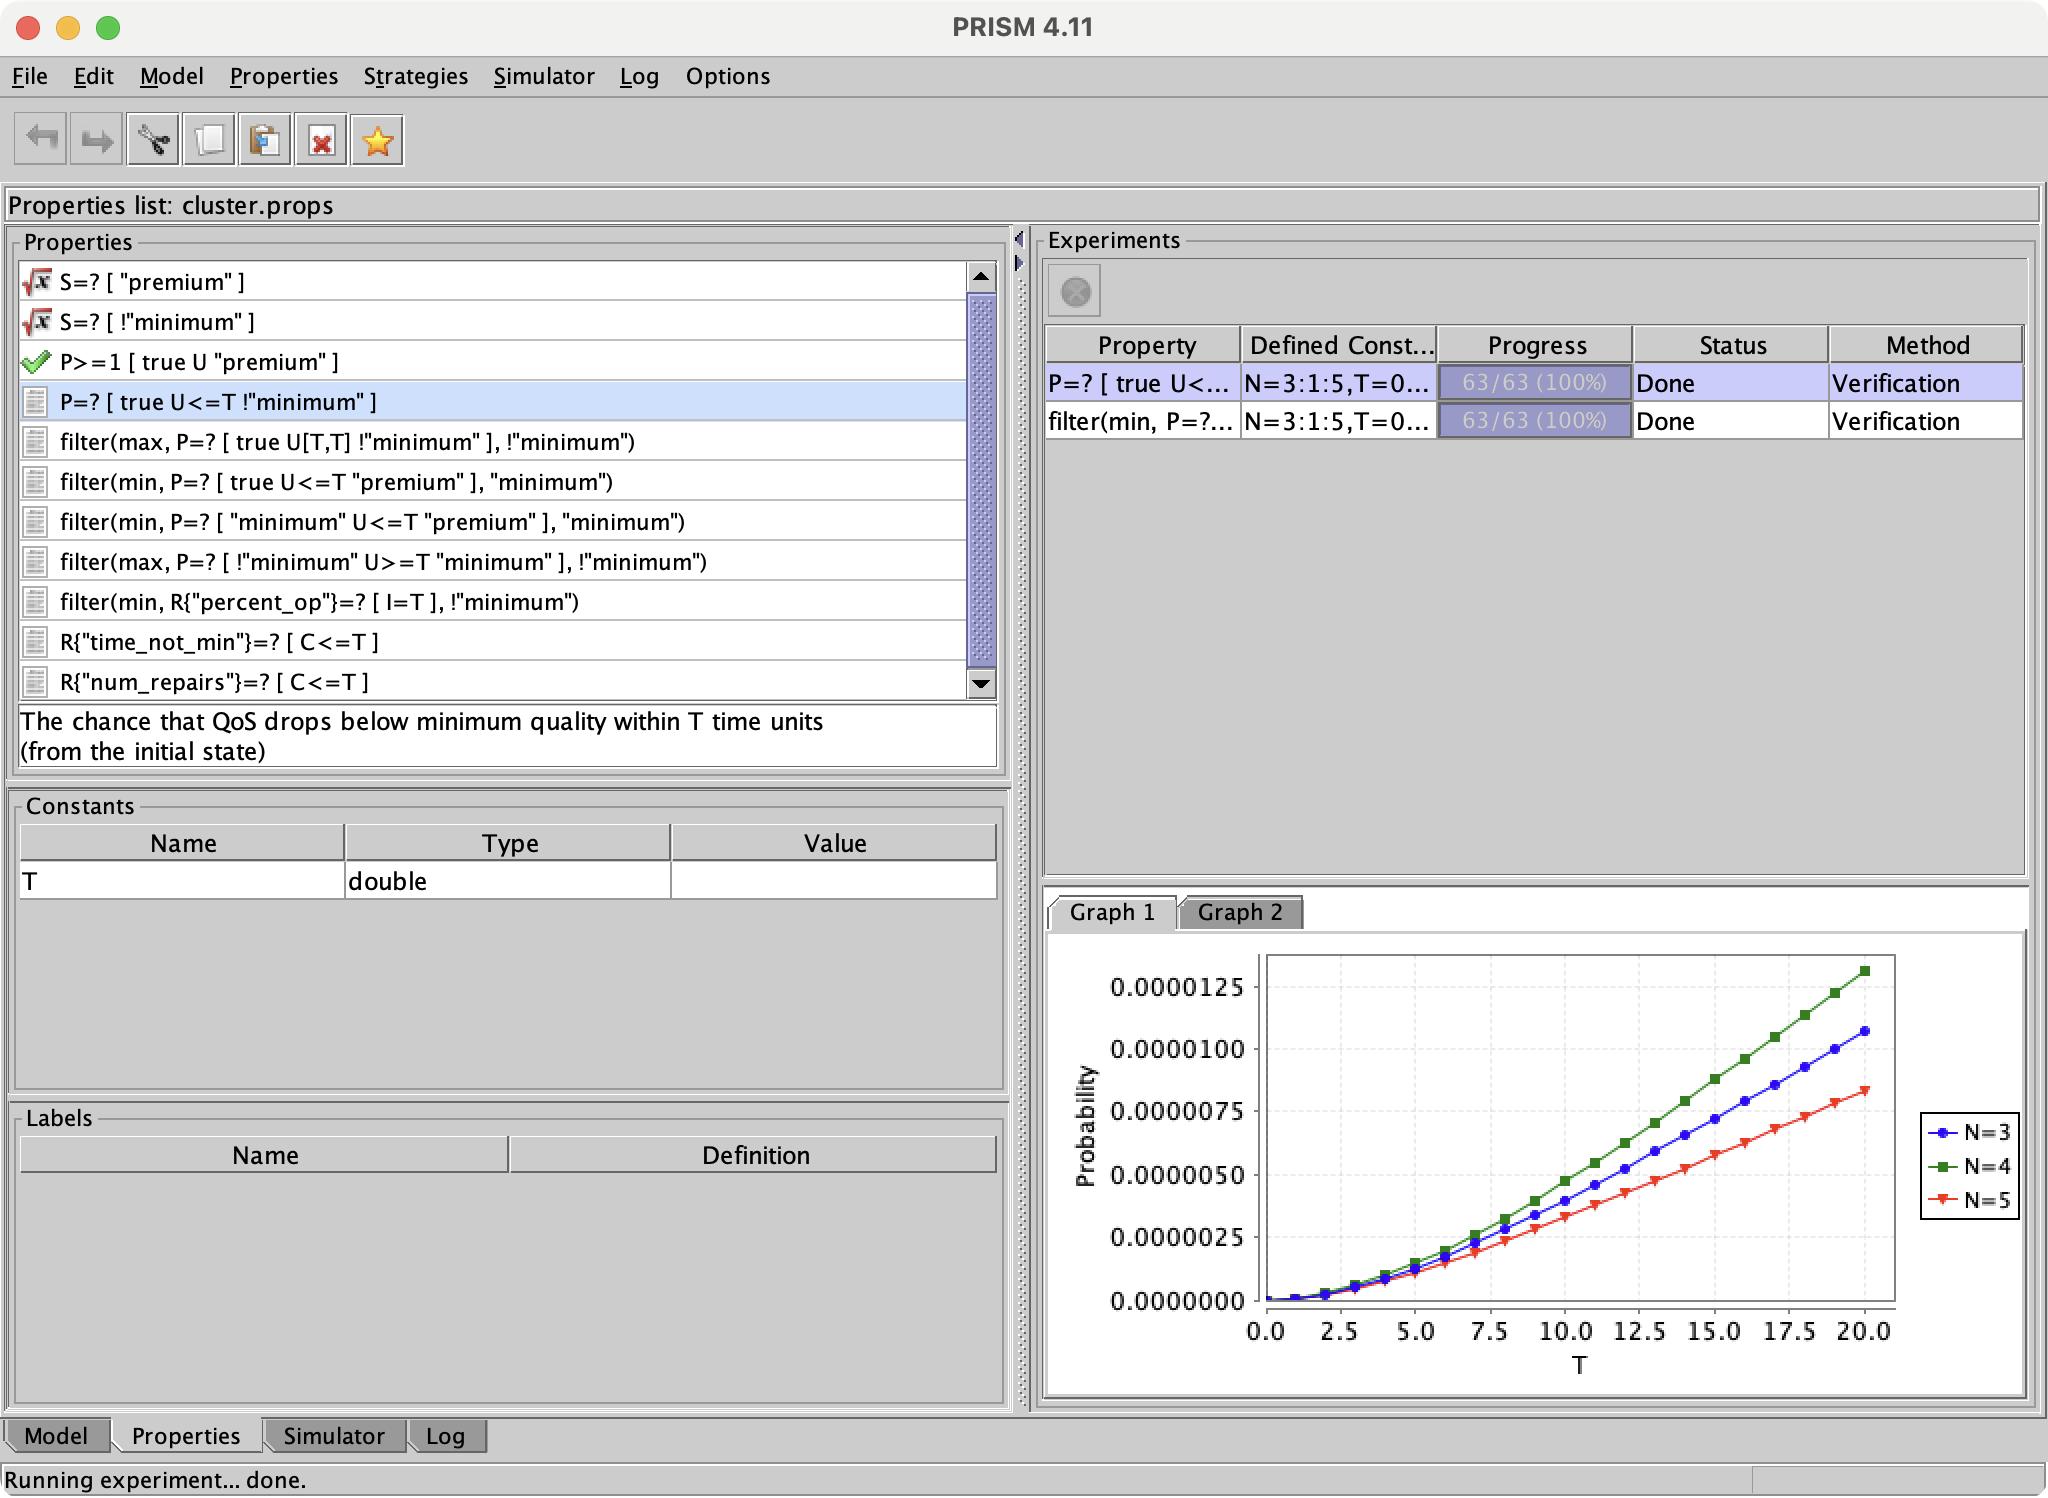
Exporting results
You can export all the results from an experiment to a file or to the screen. From the command-line, use the -exportresults switch, for example:
prism cluster.prism cluster.props -prop 4 -const N=4:5,T=0:10:20 -exportresults res.txt
to send to output file res.txt, or:
prism cluster.prism cluster.props -prop 4 -const N=4:5,T=0:10:20 -exportresults stdout
to send the results straight to the screen. From the GUI, right click on the experiment and select "Export results".
The default behaviour is to export a list of results in text form, using tabs to separate items. The above examples produce:
N	T	Result
4	0	0.0
4	10	4.707364688019771E-6
4	20	1.3126420636755292E-5
5	0	0.0
5	10	3.267731327728599E-6
5	20	8.343575060356386E-6
You can change the format in which the results are exported by appending one or more comma-separated options to the end of the -exportresults switch, for example to export in CSV (comma-separated values) format:
prism cluster.prism cluster.props -prop 4 -const N=4:5,T=0:10:20 -exportresults res.txt:csv
N, T, Result
4, 0, 0.0
4, 10, 4.707364688019771E-6
4, 20, 1.3126420636755292E-5
5, 0, 0.0
5, 10, 3.267731327728599E-6
5, 20, 8.343575060356386E-6
or in DataFrame format:
prism cluster.prism cluster.props -prop 4 -const N=4:5,T=0:10:20 -exportresults res.txt:dataframe
N,T,Result
4,0,0
4,10,4.70736468802e-06
4,20,1.31264206368e-05
5,0,0
5,10,3.26773132773e-06
5,20,8.34357506036e-06
You can also add the matrix option, to export the results as one or more 2D matrices, rather than a list.
This is particularly useful if you want to create a surface plot from results that vary over two constants.
prism cluster.prism cluster.props -prop 4 -const N=4:5,T=0:10:20 -exportresults res.txt:csv,matrix
"N\T"
, 0.0, 10.0, 20.0
4, 0.0, 4.707364688019771E-6, 1.3126420636755292E-5
5, 0.0, 3.267731327728599E-6, 8.343575060356386E-6
The matrix option is also available in normal (non-CSV) mode.
You can also export results in the form of comments, used by PRISM's regression testing functionality:
prism cluster.prism cluster.props -prop 4 -const N=4:5,T=0:10:20 -exportresults res.txt:comment
// RESULT (N=4,T=0): 0.0
// RESULT (N=4,T=10): 4.707364688019771E-6
// RESULT (N=4,T=20): 1.3126420636755292E-5
// RESULT (N=5,T=0): 0.0
// RESULT (N=5,T=10): 3.267731327728599E-6
// RESULT (N=5,T=20): 8.343575060356386E-6
From the GUI, it is also possible to import previously exported results (in DataFrame format).
A related option is the -exportvector <file> switch, useful in general contexts, not for experiments.
This exports the results for all states of the model
(typically, the log just displays the result for the initial state, unless a filter has been used)
to the file file.
Strategies
Properties to be model checked on MDPs (and their variants, such as POMDPs or IMDPs) usually quantify over strategies (or policies) of the model, i.e., over the different possible ways that nondeterminism can be resolved in the model. For example, this property:
Pmax=? [ F "goal" ]
determines the maximum probability, over all strategies, of reaching a state satisfying the label "goal".
When checking such properties, you can also ask PRISM to generate a corresponding (optimal) strategy,
which yields this maximum probability when followed. The strategy can then be viewed, exported or simulated.
Note: PRISM uses the term strategy for all model types (other common names are policy, scheduler and adversary). Strategy generation is implemented in the "explicit" model checking engine, which is used automatically if strategy generation is requested. The "sparse" engine has a more limited adversary generation feature (see below).
Generating strategies
Optimal strategies can be generated either from the command-line or the graphical user interface (GUI). For the former, use the -exportstrat switch. Simple examples are:
prism mdp.prism -pf 'Pmax=? [ F "goal" ]' -exportstrat stdout
prism mdp.prism -pf 'Pmax=? [ F "goal" ]' -exportstrat strat.pexp
prism mdp.prism -pf 'Pmax=? [ F "goal" ]' -exportstrat strat.umb
prism mdp.prism -pf 'Pmax=? [ F "goal" ]' -exportstrat strat.dot
prism mdp.prism -pf 'Pmax=? [ F "goal" ]' -exportstrat strat.tra
The first of these exports actions, the others export induced models (see below).
From the GUI, you can trigger strategy generation by ticking the "Generate strategy" box either on the popup menu that appears when you right-click a property, or from the "Strategies" menu at the top. As long as it is supported, a strategy will then be generated once "Verify" is clicked.
From the same menu(s), you can then
- export the strategy to a file
- view the strategy by printing it in the log
- explore the strategy in the simulator
Export formats
Strategies can be viewed or exported in several different formats:
Action list
An action list gives the action taken in each state of the model, e.g.:
(0,0):east
(0,1):north
(0,2):north
(1,0):south
...
where states, by default, are shown as a tuple of variable values.
Induced model
An induced model is a representation of the model that is induced when the strategy is applied. There are two "modes" for this export. The first (and default) is reduce, which removes the nondeterminism resolved by the strategy (e.g., an MDP becomes a DTMC). This can be useful to re-import the model back into PRISM and analyse the induced model. The second is restrict, which shows the original model but with a restricted set of choices (e.g., an MDP with just one choice in each state).
In each case, the induced model can be exported in various formats,
as for regular model export,
including UMB or explicit format,
the latter either a combined (.pexp) file or just the transitions (.tra).
Dot file
A Dot file is, like an induced model, a view of the model induced by the strategy, but in Dot format, which allows it to be visualised.
Configuring strategy export
As hinted in the command-line examples above, the -exportstrat switch uses the file extension to determine the preferred format: if the strategy is exported to a file with extension .umb/.pexp/.tra or .dot, then it uses an induced model or Dot file, respectively. Otherwise, the default is an action list. You can specify the desired format:
prism mdp.prism -pf 'Pmax=? [ F "goal" ]' -exportstrat file.txt:type=actions
prism mdp.prism -pf 'Pmax=? [ F "goal" ]' -exportstrat file.txt:type=induced
prism mdp.prism -pf 'Pmax=? [ F "goal" ]' -exportstrat file.txt:type=dot
Further options can be added, e.g., to specify whether an induced model is exported in "restrict" or "reduce" mode:
prism mdp.prism -pf 'Pmax=? [ F "goal" ]' -exportstrat file.txt:type=induced,mode=restrict
A list of available options is as follows:
type(actions,inducedordot): the type of strategy export to use (action list, induced model or Dot file)mode(restrictorreduce): when exporting as an induced model or Dot file, whether to "restrict" or "reduce" the model (see above); the default is "reduce"reach(trueorfalse): whether to restrict the strategy to states that are reachable when it is applied to the model (this is only used for exporting induced models and Dot files, and the default value is true, except for exporting just transitions in.traformat)states(trueorfalse): whether to show states, rather than state indices, for actions lists or Dot files; this is true by defaultmergeobs(trueorfalse): for partially observable models, whether to merge observationally equivalent states; this is true by default (and was previously calledobs).
Mirroring the -exportmodel switch (see here),
several other options are available for induced model export:
format(explicit,dotorumb): the format to export instates(trueorfalse): whether to include statesrewards(trueorfalse): whether to include rewardslabels(trueorfalse): whether to include labelsactions(trueorfalse): whether to include actions on choices/transitionsobs(trueorfalse): whether to include observationsprecision(<n>): use<n>significant figures for floating point values (in text)zip(true,false,gziporxz): whether to zip the output and in what formatheaders(trueorfalse): whether to include headers when exporting rewardstext(trueorfalse): whether to use textual form for UMB
Strategy types
PRISM generates several types of strategies. The simplest are memoryless deterministic strategies, which pick a single action in each state, as in the examples above. For some query types (e.g., step-bounded properties, or LTL-based properties), finite-memory strategies are generated, where an additional memory value is used. For these, induced models or Dot files are most useful since they will also show how the memory values are updated as the strategy is executed. Note that, in these cases, the state indices of the strategy will correspond to the product model constructed during model checking, not the original model. The product model can be exported using the -exportprodtrans and -exportprodstates switches.
Adversary generation
The "sparse" engine still includes PRISM's older "adversary generation" functionality,
which exports the induced model of an optimal strategy for MDPs, as a DTMC or an MDP
(switches -exportadv and -exportadvmdp,
or the "Adversary export" option in the GUI).
This is superseded by -exportstrat, described above, whose reduce and restrict modes give the same two models.
Simulation
PRISM includes a simulator, a tool which can be used to generate sample paths (executions) through a PRISM model.
From the GUI, the simulator allows you to explore a model by interactively generating such paths.
This is particularly useful for debugging models during development and for running sanity checks on completed models.
Paths can also be generated from the command-line using the -simpath switch.
GUI
Once you have loaded a model into the PRISM GUI (note that it is not necessary to build the model), select the "Simulator" tab at the bottom of the main window. You can now start a new path by double-clicking in the bottom half of the window (or right-clicking and selecting "New path"). If there are undefined constants in the model (or in any currently loaded properties files) you will be prompted to give values for these. You can also specify the state from which you wish to generate a path. By default, this is the initial state of the model.
The main portion of the user interface (the bottom part) displays a path through the currently loaded model. Initially, this will comprise just a single state. The table above shows the list of available transitions from this state. Double-click one of these to extend the path with this transition. The process can be repeated to extend the path in an interactive fashion. Clicking on any state in the current path shows the transition which was taken at this stage. Click on the final state in the path to continue extending the path. Alternatively, clicking the "Simulate" button will select a transition randomly (according to the probabilities/rates of the available transitions). By changing the number in the box below this button, you can easily generate random paths of a given length with a single click. There are also options (in the accompanying drop-down menu) to allow generation of paths up until a particular length or, for CTMCs, in terms of the time taken.
The figure shows the simulator in action.
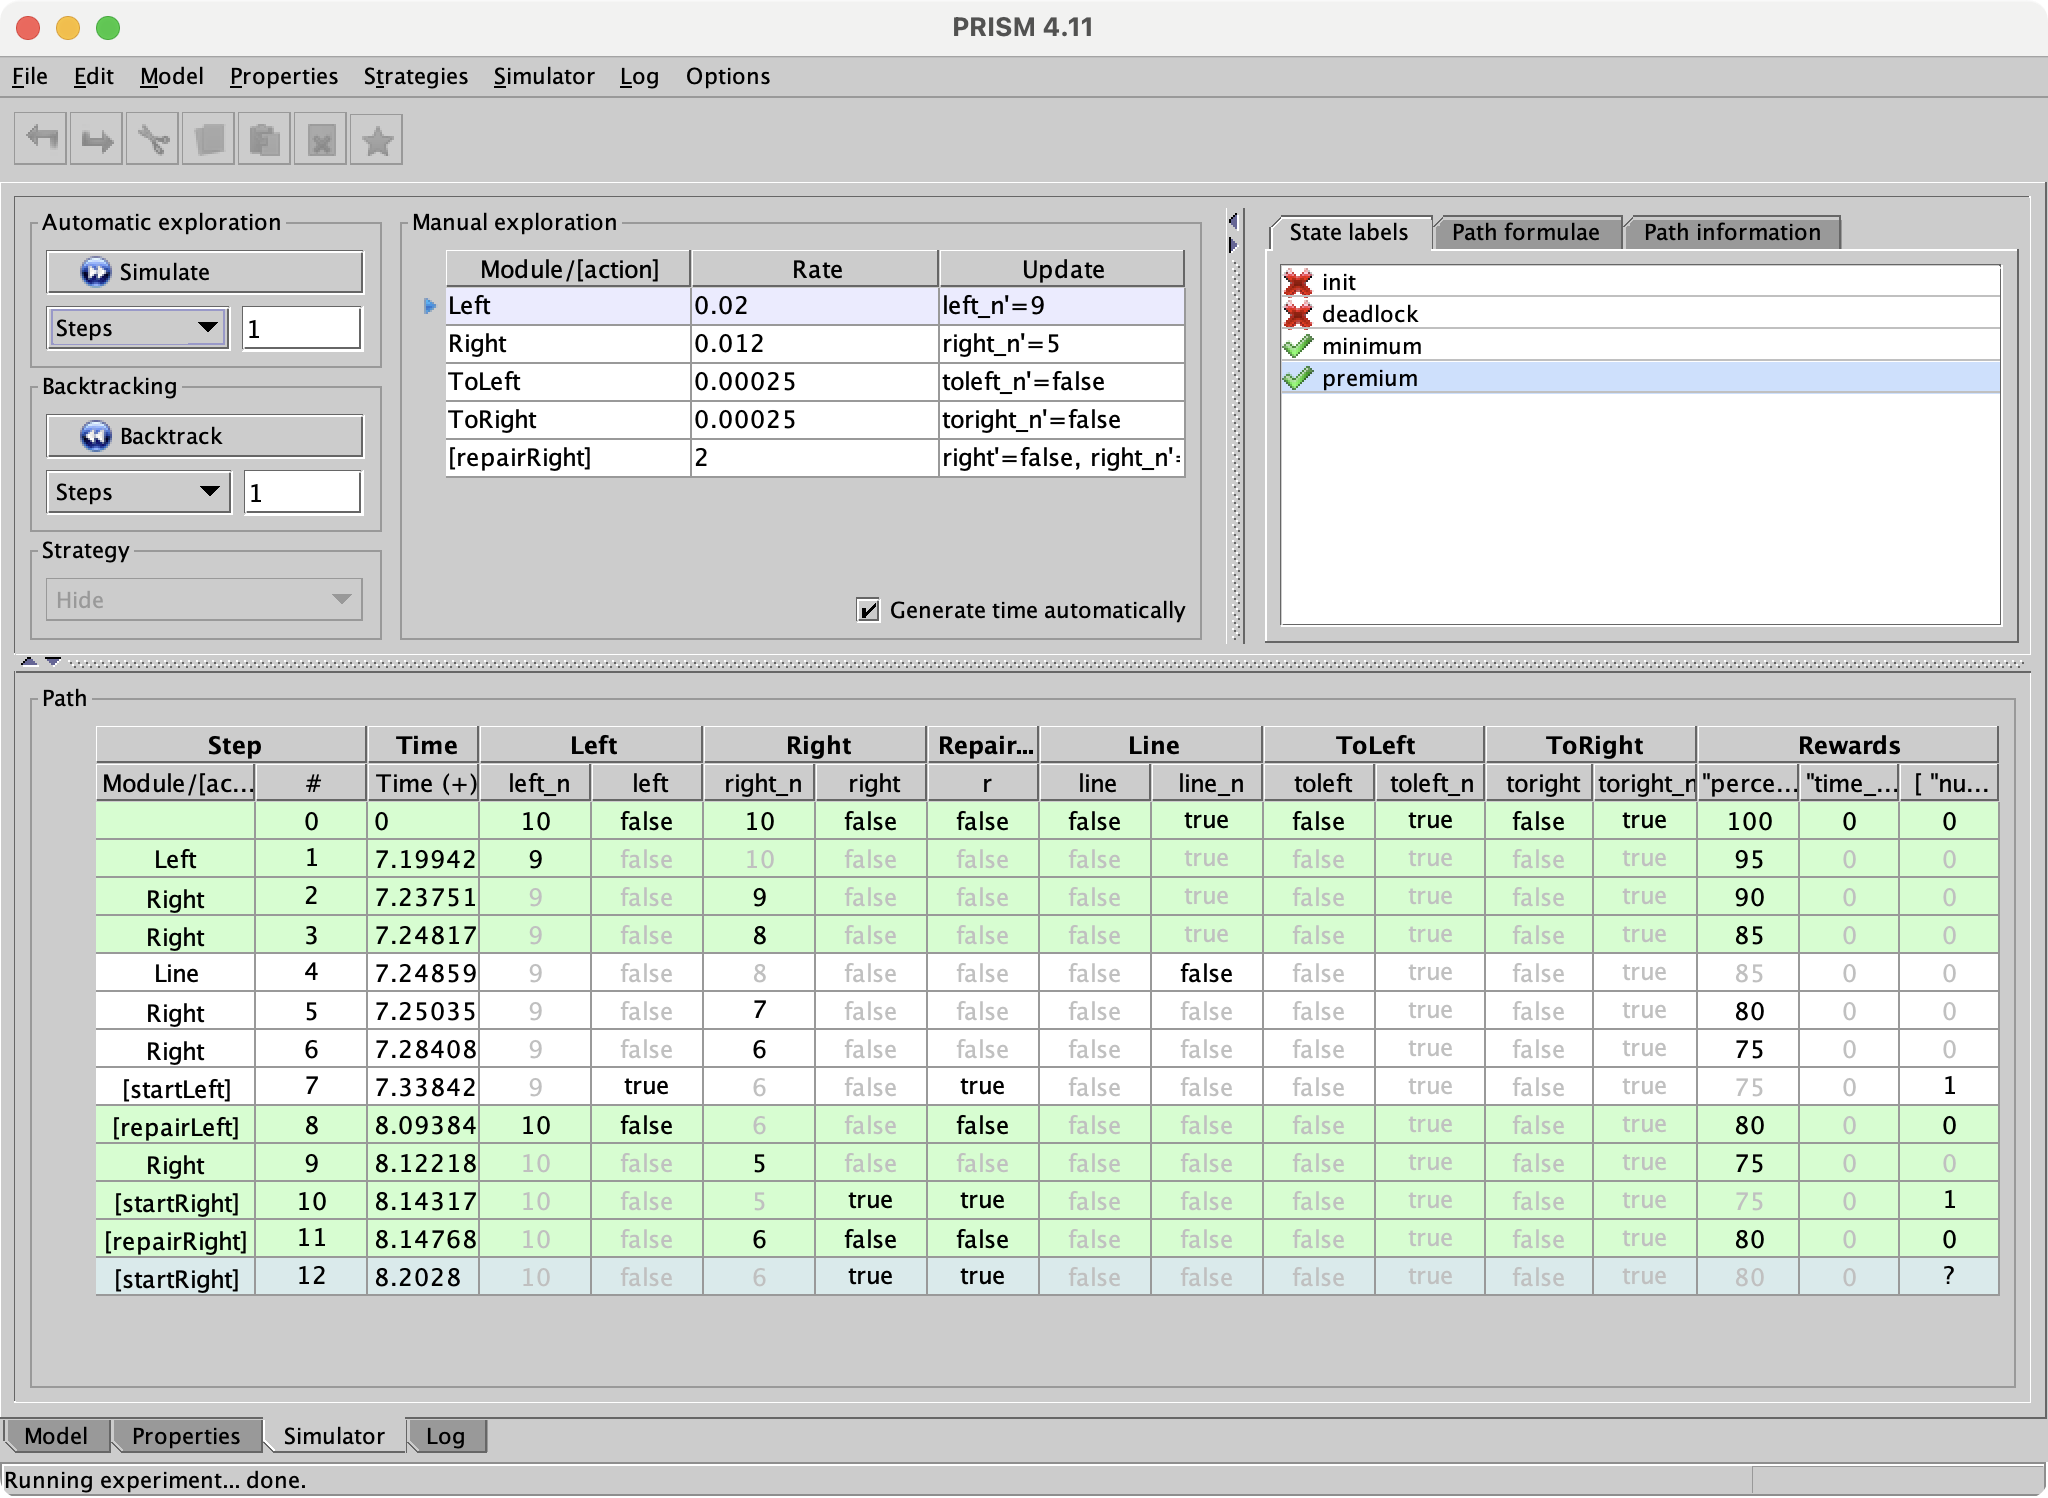
It is also possible to:
- backtrack to an earlier point in a path
- remove all of the states before some point in a path
- restart a path from its first state
- export a path to a text file
Notice that the table containing the path displays not just the value of each variable in each state but also the time spent in that state and any rewards accumulated there. You can configure exactly which columns appear by right-clicking on the path and selecting "Configure view". For rewards (and for CTMC models, for the time-values), you can opt to display the reward/time for each individual state and/or the cumulative total up until each point in the path.
At the top-right of the interface, any labels contained in the currently loaded model/properties file are displayed, along with their value in the currently selected state of the path. In addition, the built-in labels "init" and "deadlock" are also included. Selecting a label from the list highlights all states in the current path which satisfy it.
The other tabs in this panel allow the value of path operators (taken from properties in the current file) to be viewed for the current path, as well as various other statistics.
Another very useful feature for some models is to use the "Plot new path" option from the simulator, which generates a plot of some/all of the variable/reward values for a particular randomly generated path through the model.
Command-line
It is also possible to generate random paths through a model using the command-line version of PRISM. This is achieved using the -simpath switch, which requires two arguments, the first describing the path to be generated and the second specifying the file to which the path should be output (as usual, specifying stdout sends output to the terminal). The following examples illustrate the various ways of generating paths in this way:
prism model.prism -simpath 10 path.txt
prism model.prism -simpath time=7.5 path.txt
prism model.prism -simpath deadlock path.txt
These generate a path of 10 steps, a path of at least 7.5 time units and a path ending in deadlock, respectively.
Here's an example of the output:
prism poll2.prism -simpath 10 stdout
...
action step time s a s1 s2
- 0 0.0 1 0 0 0
[loop1a] 1 0.007479539729154247 2 0 0 0
[loop2a] 2 0.00782819795294666 1 0 0 0
[loop1a] 3 0.01570585559933703 2 0 0 0
[loop2a] 4 0.017061111948220263 1 0 0 0
[loop1a] 5 0.026816317516034468 2 0 0 0
[loop2a] 6 0.039878416276337814 1 0 0 0
[loop1a] 7 0.04456566315999103 2 0 0 0
[loop2a] 8 0.047368359683643765 1 0 0 0
[loop1a] 9 0.04934857366557349 2 0 0 0
[loop2a] 10 0.055031679365844674 1 0 0 0
poll2.prism is a CTMC model of a simple polling system (also shown, with a diagram, in "Explicit model files").
This shows the sequence of states in the path, i.e., the values of the variables in each state. In the example above, there are 4 variables: s, a, s1 and s2.
The first three columns show the type of transition taken to reach that state, its index within the path (starting from 0) and the time at which it was entered. The latter is only shown for continuous time models. The type of the transition is written as [act] if action label act was taken, and as module1 if the module named module1 takes an unlabelled transition.
Further options can also be appended to the first parameter. For example, option probs=true also displays the probability/rate associated with each transition. For example:
prism poll2.prism -simpath '5,probs=true' stdout
...
action probability step time s a s1 s2
- - 0 0.0 1 0 0 0
[loop1a] 200.0 1 0.0011880118081395378 2 0 0 0
[loop2a] 200.0 2 0.0037798355025401888 1 0 0 0
[loop1a] 200.0 3 0.01029212322894221 2 0 0 0
[loop2a] 200.0 4 0.023258883912578403 1 0 0 0
[loop1a] 200.0 5 0.027402404026254504 2 0 0 0
In this example, the rate is 200.0 for all transitions.
To show the state/transition rewards for each step, use option rewards=true.
If you are only interested in values of certain variables of your model, use the vars=(...) option. For example:
prism poll2.prism -simpath '500,probs=true,vars=(a,s1,s2)' stdout
...
action probability step time a s1 s2
- - 0 0.0 0 0 0
station2 0.5 110 0.5025332771499665 0 0 1
[loop2b] 200.0 111 0.5109407735244359 1 0 1
[serve2] 1.0 112 0.9960642154887506 0 0 0
station1 0.5 130 1.0645858553472822 0 1 0
[loop1b] 200.0 132 1.0732572896618477 1 1 0
[serve1] 1.0 133 2.939742026148121 0 0 0
station2 0.5 225 3.4311507854807677 0 0 1
[loop2b] 200.0 227 3.434285492243098 1 0 1
[serve2] 1.0 228 3.553118276800078 0 0 0
station2 0.5 250 3.6354431222941406 0 0 1
[loop2b] 200.0 251 3.637552738997181 1 0 1
[serve2] 1.0 252 3.7343375346150576 0 0 0
Note the use of single quotes around the path description argument to prevent the shell from misinterpreting special characters such as "(".
Notice also that the above only displays states in which the values of some variable of interest changes. This is achieved with the option changes=true, which is automatically enabled when you use vars=(...). If you want to see all steps of the path, add the option changes=false.
An alternative way of viewing paths is to only display paths at certain fixed points in time. This is achieved with the snapshot=x option, where x is the time step. For example:
prism poll2.prism -simpath 'time=5.0,snapshot=0.5' stdout
...
step time s a s1 s2
0 0.0 1 0 0 0
94 0.5 1 0 0 0
198 1.0 1 0 0 0
314 1.5 1 0 0 0
375 2.0 1 1 1 1
376 2.5 2 0 0 1
376 3.0 2 0 0 1
378 3.5 1 0 0 0
378 4.0 1 0 0 0
478 4.5 1 0 0 0
511 5.0 2 0 0 0
You can also use the sep=... option to specify the column separator. Possible values are space (the default), tab and comma. For example:
prism poll2.prism -simpath '200,vars=(a,s1),sep=comma' stdout
...
action,step,time,a,s1
-,0,0.0,0,0
[loop2b],71,0.30227293267212296,1,0
station1,72,0.7818965999769389,1,1
[serve2],73,1.132620216421162,0,1
[loop1b],74,1.1350805223051847,1,1
[serve1],76,5.305834484838731,0,0
...
When generating paths to a deadlock state, an additional repeat=... option is available, which will construct multiple paths until a deadlock is found. For example:
prism model.prism -simpath 'deadlock,repeat=100' stdout
By default, the simulator detects deterministic loops in paths (e.g., if a path reaches a state from which there is just a single self-loop leaving that state) and stops generating the path any further. You can disable this behaviour with the loopcheck=false option. For example:
prism model.prism -simpath 10 stdout
...
Warning: Deterministic loop detected after 6 steps (use loopcheck=false option to extend path).
action step s d
- 0 0 0
die 1 1 0
die 2 4 0
die 3 7 3
die 4 7 3
prism dice.prism -simpath 10,loopcheck=false stdout
...
action step s d
- 0 0 0
die 1 1 0
die 2 4 0
die 3 7 2
die 4 7 2
die 5 7 2
die 6 7 2
die 7 7 2
die 8 7 2
die 9 7 2
die 10 7 2
One final note: the -simpath switch only generates paths up to the maximum path length setting of the simulator (the default is 10,000). If you want to generate longer paths, either change the
default setting or override it temporarily from the command-line using the -simpathlen switch.
You might also use the latter to decrease the setting,
e.g., to look for a path leading to a deadlock state,
but only within 100 steps:
prism model.prism -simpath deadlock stdout -simpathlen 100
Statistical model checking
The discrete-event simulator built into PRISM can also be used to generate approximate results for PRISM properties, a technique often called statistical model checking. Essentially, this is achieved by sampling: generating a large number of random paths through the model, evaluating the result of the given properties on each run, and using this information to generate an approximately correct result. This approach is particularly useful on very large models when normal model checking is infeasible. This is because discrete-event simulation is performed using the PRISM language model description, without explicitly constructing the corresponding probabilistic model.
Statistical model checking can be used from the GUI (by selecting "Simulate")
and from the command-line (by using the -sim switch); more details are given below.
Methods and settings
You can select between four different methods for performing statistical model checking:
- CI (Confidence Interval)
- ACI (Asymptotic Confidence Interval)
- APMC (Approximate Probabilistic Model Checking)
- SPRT (Sequential Probability Ratio Test)
The first three of these are intended primarily for numerical properties (e.g., of the form P=?[...]), but can also be used for Boolean properties with a bound (e.g., of the form P<p[...]). The SPRT method is only applicable to Boolean properties.
Each method has several parameters that control its execution, i.e., the number of samples that are generated and the accuracy of the computed approximation. In most cases, these parameters are inter-related so one of them must be left unspecified and its value computed automatically based on the others. In some cases, this is done before simulation; in others, it must be done afterwards.
Below, we describe each method in more detail.
For simplicity, we describe the case of checking a P operator.
Details for the case of an R operator can be found in [Nim10].
CI (confidence interval) method
The CI method gives a confidence interval for the approximate value generated for a P=? property, based on a given confidence level and the number of samples generated.
The parameters of the method are:
- "Width" (
) - "Confidence" (
) - "Number of samples" (
)
Let P=?[...] and
To determine, for example, the width
where
where
For a bounded property P~p[...], the (Boolean) result is determined according to the generated approximation for the probability. This is not the case, however, if the threshold
ACI (asymptotic confidence interval) method
The ACI method works in exactly the same fashion as the CI method, except that it uses the Normal distribution to approximate the Student's t-distribution when determining the confidence interval. This is appropriate when the number of samples is large (because we can get a reliable estimation of the variance from the samples) but may be less accurate for small numbers of samples.
APMC (approximate probabilistic model checking) method
The APMC method, based on [HLMP04], offers a probabilistic guarantee on the accuracy of the approximate value generated for a P=? property, based on the Chernoff-Hoeffding bound.
The parameters of the method are:
- "Approximation" (
) - "Confidence" (
) - "Number of samples" (
)
Letting P=?[...] and
where the parameters are related as follows:
This imposes certain restrictions on the parameters,
namely that
In similar fashion to the CI/ACI methods, the APMC method can also be used for bounded properties such as P~p[...], as long as the threshold
SPRT (sequential probability ratio test) method
The SPRT method is specifically for bounded properties, such as P~p[...] and is based on acceptance sampling techniques [YS02]. It uses Wald's sequential probability ratio test (SPRT), which generates a succession of samples, deciding on-the-fly when an answer can be given with a sufficiently high confidence.
The parameters of the method are:
- "Indifference" (
) - "Type I/II error" (
/ )
Consider a property of the form P>=p[...]. The parameter P>=(p+delta)[...] or P<=(p-delta)[...] is true, based on which it will return either true or false, respectively. The parameters
Maximum path length
Another setting that can be configured is the maximum length of paths generated by PRISM during statistical model checking.
In order to perform statistical model checking, the property being checked needs to be evaluated along every generated path.
For example, when checking P=? [ F<=10 "end" ], PRISM must check whether F<=10 "end" is true for each path. On this example (assuming a discrete-time model), this can always be done within the first 10 steps. For a property such as P=? [ F "end" ], however, there may be paths along which no finite fragment can show F "end" to be true or false. So, PRISM imposes a maximum path length to avoid the need to generate excessively long (or infinite) paths.
The default maximum length is 10,000 steps.
If, for a given property, statistical model checking results in one or more paths on which the property cannot be evaluated, an error is reported.
GUI
To use statistical model checking from the GUI, load a model and some properties into PRISM, as described in "Model checking". To generate an approximate value for one or more properties, select them in the list, right-click and select "Simulate" (as opposed to "Verify"). As usual, it is first necessary to provide values for any undefined constants. Subsequently, a "Simulation Parameters" dialog appears. Here, the state from which approximate values are to be computed (i.e., from which the paths will be generated) can be selected. By default, this is the initial state of the model. The other settings in the dialog concern the methods used for simulation.
Command-line
Statistical model checking can also be enabled from the command-line version of PRISM, by using the -sim switch.
The default methods used are CI (Confidence Interval) for numerical properties and SPRT (Sequential Probability Ratio Test) for Boolean properties.
To select a particular method, use switch -simmethod <method> where <method> is one of ci, aci, apmc and sprt.
For example:
prism model.prism model.props -prop 1 -sim -simmethod aci
PRISM has default values for the various simulation method parameters, but these can also be specified using the switches -simsamples, -simconf, -simwidth and -simapprox. The exact meaning of these switches for each simulation method is given in the table below.
| Switch | CI | ACI | APMC | SPRT |
|---|---|---|---|---|
-simsamples |
"Number of samples" | "Number of samples" | "Number of samples" | n/a |
-simconf |
"Confidence" | "Confidence" | "Confidence" | "Type I/II error" |
-simwidth |
"Width" | "Width" | n/a | "Indifference" |
-simapprox |
n/a | n/a | "Approximation" | n/a |
The maximum length of simulation paths is set with switch -simpathlen.
Restrictions
Statistical model checking can only be applied to P or R operators.
It does not support nested properties, LTL formulas, filters,
cumulative reward properties without a time bound, or discounted rewards for continuous-time models.
The simulator also does not support every part of the PRISM modelling language. For example, it does not handle models with multiple initial states or with system...endsystem definitions.
It is also worth pointing out that statistical model checking techniques are not well suited to models that exhibit nondeterminism, such as MDPs. This is because the techniques rely on generation of random paths, which are not well defined for an MDP. PRISM does allow statistical model checking to be performed on an MDP, but does so by simply resolving nondeterministic choices in a (uniformly) random fashion (and displaying a warning message). PTAs are not supported by the simulator.
Transient and steady-state probabilities
If the model is a CTMC or DTMC, it is possible to compute corresponding vectors of
steady-state or transient probabilities directly
(rather than indirectly by analysing a property which requires their computation).
From the GUI, select an option from the "Model | Compute" menu.
For transient probabilities, you will be asked to supply the
time value for which you wish to compute probabilities.
From the command-line, add the -steadystate (or -ss) switch for steady-state probabilities
or the -transient (or -tr) switch for transient probabilities, again specifying a time value in the latter case:
prism poll2.prism -ss
prism poll2.prism -tr 2.0
Here, poll2.prism is a CTMC model of a simple polling system (also shown, with a diagram, in "Explicit model files").
The probabilities are computed for all states of the model and displayed,
either on the screen (from the command-line) or in the log (from the GUI).
To instead export the vector of computed probabilities to a file, use the "Model | Compute/export" option from the GUI, or the -exportsteadystate and -exporttransient switches from the command-line:
prism poll2.prism -ss -exportsteadystate poll2-ss.txt
prism poll2.prism -tr 2.0 -exporttransient poll2-tr2.txt
From the command-line, you can request that the probability vectors exported are in Matlab format by adding the -exportmatlab switch.
Initial probability distributions
By default, for both steady-state and transient probability computation,
PRISM assumes that the initial probability distribution of the model is
an equiprobable choice over the set of initial states.
You can override this and provide a specific initial distribution. This is done using the -importinitdist switch. The format for this imported distribution is identical to the ones exported by PRISM, i.e. simply a list of probabilities for all states separated by new lines. For example, this:
prism poll2.prism -tr 1.0 -exporttransient poll2-tr1.txt
prism poll2.prism -tr 1.0 -importinitdist poll2-tr1.txt -exporttransient poll2-tr2.txt
is (essentially) equivalent to this:
prism poll2.prism -tr 2.0 -exporttransient poll2-tr2.txt
Ranges of time values
Finally, you can compute transient probabilities for a range of time values, e.g.:
prism poll2.prism -tr 0.1:0.01:0.2
which computes transient probabilities for the time points 0.1, 0.11, 0.12, ..., 0.2. In this case, the computation is done incrementally, with probabilities for each time point being computed from the previous point for efficiency.
Parametric model checking
Often, PRISM models contain constants, representing parameters of the system being modelled, which define for example the transition probabilities in the model. In order to perform model checking, these constants have to be assigned concrete values. PRISM also allows experiments, where model checking is performed for a range of different values for the constants.
PRISM's parametric model checking [HHZ11b],[HHZ11] functionality, however, provides a more powerful method for analysing probabilistic models whose transition probabilities are specified as functions over a set of parameters. Depending on the property under consideration, the result is then given as either a rational function over the parameters or as a mapping from regions of these parameters to rational functions or truth values. This function (or functions) can then be used to, for example:
- plot a graph showing how the parameter affects the result of the property; or
- use optimisation methods to find parameter values that minimise or maximise the result.
PRISM's implementation of parametric model checking [CHH+13] re-implements the techniques previously included in the PARAM tool.
Parameters are specified as undefined constants in the model file, e.g.:
const double x;
These parameters can only be used to describe probabilities (or rates). For example:
[] s=0 -> x : (s'=1) + 1-x : (s'=2);
They may not be used in guards or updates. The parametric definitions of probabilities or rates (e.g. x and 1-x in the above) must be rational functions (fractions of polynomials). PRISM supports parametric versions of discrete-time Markov chains (DTMCs), continuous-time Markov chains (CTMCs) and Markov decision processes (MDPs). The classes of properties that can be checked on these models are as follows:
- parametric DTMCs/CTMCs: unbounded until, steady-state probabilities, reachability reward and steady-state reward;
- parametric MDPs: unbounded until and reachability rewards.
Parametric model checking can only be performed from the command-line. This is done by using the switch -param <vals>, where <vals> lists the undefined constants that should be treated as parameters. A range of possible values should also be provided for each parameter, in the form <parameter>=<lower-bound>:<upper-bound>. For example:
prism model.prism model.props -param x=0.2:0.4,y=-2:2
would specify a parameter x with lower bound 0.2 and upper bound 0.4, and a parameter y with values between -2 and 2. You can also omit the bounds for a parameter, in which case it will be assumed to have range 0 to 1.
The result of parametric model checking will be a mapping from regions (subsets of parameter valuations) to functions over the parameters. The regions are given as hyper-rectangles, e.g. "[ [0.2,0.3],[-2,0] ]" would represent the region of parameter valuations in which the first parameter is between 0.2 and 0.3 and the second is between -2 and 0. The results obtained are exact, that is no rounding errors are made during computation. Here is an example of the output of model checking:
prism model.prism model.props -param x=0:1
...
Result: ([0.0,1.0]): { 2 x - 5  | 8 x - 12  }
which indicates that, for the full range ([0,1]) of the parameter x, the result of model checking is the expression (2x-5)/(8x-12).
Parametric model checking can be configured with the following options:
-
-paramprecision <x>: PRISM uses regions in the form of hyper-rectangles to subsume parameter valuations with the same rational function or truth value. Because it is not always possible to cover the whole parameter space with hyper-rectangles, this option can be used to specify a precision, that is, an amount of the parameter space which may remain undecided. The default is 5/100. -
-paramsplit <name>: During model checking, undecided regions may have to be split into several parts, because there might not exist a single rational function or truth value to which all parameter valuations of the original regions can be mapped. When a region is split, it can either be split at only its longest side (<name>=longest) or at all sides at once (<name>=all). The default islongest. -
-parambisim <name>: The parametric analysis is costly in terms of time and memory, so it can help to perform bisimulation minimisation to speed up the analysis and use less memory. The possible options here are to use weak bisimulation (<name>=weak), strong bisimulation (<name>=strong) or none at all (<name>=none). The default isweak. In case an analysis is to be performed for which the current bisimulation type does not maintain validity of the results (e.g. weak bisimulation and a steady state analysis), an appropriate bisimulation engine is chosen automatically. -
-paramfunction <name>: Sets the way rational functions are represented. Only Java Algebra System (JAS) is supported. The options are to use JAS directly (<name>=jas) or to use a version in which results of some previous mathematical operations performed during the analysis are cached (<name>=jas-cached). This can speed up computation, but also needs more memory. The default is to use the cached version. -
-paramelimorder <name>: In the parametric engine, computations are performed by "eliminating" one state after the other, that is completely treating a state together with its incoming and outgoing transitions, rather than performing iterative methods. This option sets the order in which states are eliminated. The available values are: arbitrary order (<name>=arbitrary), forward starting from the initial states (<name>=forward), reversed forward order (<name>=forward-reversed), starting with target/unsafe states and then going backward (<name>=backward), the reverse of this order (<name>=backward-reversed) or random order (<name>=random). The default is the backward order. -
-paramrandompoints <n>: Under some conditions, it has to be decided whether certain properties hold for all parameter valuations of a given region. This is the case for instance when computing truth values of properties for parametric DTMCs, CTMCs and MDPs, and also when computing any value for MDPs. At the moment, the truth values are only computed approximately, by evaluating and checking values at the edges of regions (as they are hyper-rectangles) and some random points. The exact number of random points to use is given with this option. The default is 5. -
-paramsubsumeregions <b>: During the parametric analysis, quite a number of different regions might be created, which have to be stored in memory. If this option is used (<b>=true), PRISM tries to subsume neighbouring regions with the same value. The default is to use it.
Importing and exporting models
Once a model has been built, PRISM can export it to files, for examination or for use in another tool; conversely, you can import a model that has already been built, by PRISM or another tool. The file formats are described in "Explicit model files".
Exporting models
If required, once the model has been constructed, it can be exported, either for manual examination or for use in another tool. The following can all be exported:
- the transition matrix (or function);
- the rewards (state and transition rewards);
- the labels (in the model or properties) and the states that satisfy them
- the definition of (reachable) states, i.e., their variable values
- the definition of observations, i.e., their observable values, for partially observable models
From the command-line version of PRISM, the most convenient and flexible approach is to use the -exportmodel switch.
This will, by default, use the extension of the filename(s) to determine the format.
From the GUI, use the "Model | Export" menu to export the data to a file or, for small models, use the "Model | View" menu to print the details directly to the log. For the case of labels, if you want to export labels from the properties file too, use the "Properties | Export labels" option, rather than the "Model | Export" one.
The main formats for model export are:
- plain text files (sometimes referred to as "explicit" or ".tra" or ".pexp" files)
- UMB (Unified Markov binary) format, a binary format supported by other probabilistic model checkers
- Dot format, for a graphical view of the model
Plain text (explicit files)
This format either exports all/multiple parts of the model into a single combined file, or individual parts of the model in different files. The expected filename extensions are:
.pexp- all parts of the model ("PRISM explicit").tra- transition matrix.srew,.trew,.rew- rewards: states, transitions or both.lab- labels.sta- states.obs- observations
and appending .gz or .xz to these extensions causes the file to be zipped.
To export everything, use:
prism model.prism -exportmodel model.pexp
To export everything zipped, use:
prism model.prism -exportmodel model.pexp.gz
To export everything except states, use:
prism model.prism -exportmodel model.pexp:states=false
To export just the transition matrix in this format, use:
prism model.prism -exportmodel model.tra
To export multiple parts, use, e.g.:
prism model.prism -exportmodel model.tra,sta
If you omit the basename of the export files, the basename of the model will be used, so this is equivalent to the above:
prism model.prism -exportmodel .tra,sta
You can use the shorthand .all to export everything to separate files, and .rew to export both state and transition rewards. For example:
prism model.prism -exportmodel model.all
You can always use stdout instead of a filename. For example:
prism model.prism -exportmodel stdout
is a quick way to print all parts of a (small) model to the terminal, or
prism model.prism -exportmodel stdout.sta
prints its states.
The labels (.lab) export includes the built-in labels "init" and "deadlock",
providing a way to export information about initial states and (fixed) deadlock states.
When exporting multiple reward structures to individual files, a (1-indexed) suffix is added to distinguish them.
By default each part of the model is prefixed by a header (starting #),
identifying what it is, plus some additional details,
e.g., the name of a reward structure or the type of a model
(see "Explicit model files").
This can be omitted - see the options below - or via the option "Include headers in model exports" in the GUI.
UMB (Unified Markov binary) format
UMB is a binary format that can incorporate all parts of the model listed above.
prism model.prism -exportmodel model.umb
By default, everything is included. You can omit some parts with the -exportmodel
options rewards, labels, states and obs, e.g.:
prism model.prism -exportmodel model.umb:states=false,rewards=false
For a small model, you can also see a textual version of the UMB format
using file extension .umbt (or option text):
prism model.prism -exportmodel stdout.umbt
UMB files are compressed by default (but still have the extension .umb).
You can also configure the compression used: zip=false turns it off,
zip=gzip uses gzip and zip=xz uses xz (smaller but slower to read/write).
Other formats and options
If the file extension is not recognised, PRISM defaults to plain text (explicit) format.
You can always override this using the format option, e.g.:
prism model.prism -exportmodel model.txt:format=explicit
prism model.prism -exportmodel model.txt:format=umb,text
You can perform multiple model exports using several instances of -exportmodel, e.g.:
prism model.prism -exportmodel model.txt:format=explicit -exportmodel model.dot
Other file formats are also available:
Other -exportmodel options are:
states(trueorfalse): whether to include statesrewards(trueorfalse): whether to include rewardslabels(trueorfalse): whether to include labelsactions(trueorfalse): whether to include actions on choices/transitionsobs(trueorfalse): whether to include observationsprecision(<n>): use<n>significant figures for floating point values (in text)headers(trueorfalse): whether to include headers when exporting rewardsrows: export matrices with one row/distribution on each line (plain text)proplabels: also export labels from a properties file into a.labfilezip(true,false,gziporxz): whether to zip the output and in what format
For plain text export, -exportmodel is usually the best switch to use,
but there are also older switches. For example, you can export individual files using
-exporttrans <file>,
-exportstates <file>,
-exportstaterewards <file>,
-exporttransrewards <file>,
-exportrewards <file> <file>,
-exportlabels <file>, and
-exportproplabels <file>.
And you can use switches
-exportmodelprecision <x>,
-exportmatlab and
-exportrows
to specify format options affecting all of them.
Exporting (B)SCCs and end components
It is also possible to export the set of (bottom) strongly connected components (SCCs or BSCCs) for a model. This can only be done from the command-line. Use, for example:
prism model.prism -exportsccs stdout
prism model.prism -exportbsccs stdout
For an MDP, you can also export the set of maximal end components (MECs):
prism mdp.prism -exportmecs stdout
Importing models
It is also possible to construct models in PRISM through direct specification of their transition matrix. Two formats for explicit model import are supported:
- plain text files (sometimes referred to as "explicit" or "
.tra" or ".pexp" files) - UMB (Unified Markov binary) format, a binary format supported by other probabilistic model checkers
This functionality is only supported in the command-line version of the tool, usually using the -importmodel switch.
In a similar fashion to -exportmodel switch, the type of import is usually determined from the file extension.
For UMB, all model info is contained in a single file. An example of import is:
prism -importmodel poll2.umb
For the plain text files (.tra etc.), various options are possible.
To import everything (in the combined .pexp format) use:
prism -importmodel poll2.pexp
To just import the core part of the model (the transition function) use:
prism -importmodel poll2.tra
From explicit format, PRISM tries to determine the model type from the transitions data,
using the model type included in the header, if present,
and guessing from the format of the data if not.
If this does not work, the model type can be overwritten using the -dtmc, -ctmc and -mdp switches.
For example:
prism -importmodel poll2.tra -ctmc
Using the same formats as for model export, multiple other parts of the model can also be imported separately:
.lab- labels.srew,.trew- rewards: states, transitions.sta- states.obs- observations
Here is an example of also importing labels and states:
prism -importmodel poll2.tra,sta,lab
If state information is not imported, a single zero-indexed variable x is assumed.
Note also that, since details about the initial state(s) of a model are not preserved in the .tra file,
but are included in the labels file, this should also be used to designate a particular initial state for a model.
Otherwise, state 0 is assumed to be the initial state or,
if state information is imported, the state in which all variables take their minimum value is used.
Use the extension .all to import from multiple files containing separate parts of the model, named with appropriate file extensions:
prism -importmodel poll2.all
When providing the whole model, you can omit the -importmodel switch, e.g.:
prism poll2.pexp
prism poll2.all
Any files can be zipped, and this will be detected by their (.gz or .xz) filename extension.
These are decompressed automatically on import.
Efficiency
Please note, for PRISM's symbolic model construction/engines, which are often used by default, this explicit method of constructing models in PRISM is typically less efficient than using the PRISM language. This is because the underlying data structures used to represent the model function better when there is high-level structure and regularity to exploit. You may want to switch to the "explicit" engine:
prism -importmodel poll2.tra -ex
The situation can also be alleviated to a certain extent for the symbolic implementations by importing
the .sta file, since the composition of the states reintroduces some regularity
(although it is still typically inefficient to construct).
Other options
In a similar style to PRISM's -exportmodel switch, while -importmodel is usually the most convenient, you can also specify each part separately, e.g.:
prism -importtrans poll2.tra -importstates poll2.sta -importlabels poll2.lab -ctmc
There are also -importstaterewards and -importtransrewards switches.
You can import multiple reward structures using multiple instances of these switches.
If present in the rewards files (see "Explicit model files"),
the names of the reward structures are read too.
Other modelling languages
As well as models in the PRISM language, PRISM can work with models written in two other languages: the stochastic process algebra PEPA, and SBML, the Systems Biology Markup Language.
PEPA
For CTMCs, PRISM also accepts model descriptions in the stochastic process algebra PEPA [Hil96]. The tool compiles such descriptions into the PRISM language and then constructs the model as normal. The language accepted by the PEPA to PRISM compiler is actually a subset of PEPA. The restrictions applied to the language are firstly that component identifiers can only be bound to sequential components (formed using prefix and choice and references to other sequential components only). Secondly, each local state of a sequential component must be named. For example, we would rewrite:
P = (a,r).(b,s).P;
as:
P = (a,r).P';
P' = (b,s).P;
Finally, active/active synchronisations are not allowed since the PRISM
definition of these differs from the PEPA definition. Every PEPA
synchronisation must have exactly one active component.
Some examples of PEPA model descriptions which can be imported into PRISM
can be found in the prism-examples/pepa directory.
From the command-line version of PRISM, add the -importpepa switch and the model will be treated as a PEPA description.
From the GUI, select "Model | Open model" and then choose "PEPA models"
on the "Files of type" drop-down menu.
Alternatively, select "Model | New | PEPA model" and either type a description from scratch
or paste in an existing one from elsewhere.
Once the PEPA model has been successfully parsed by PRISM,
you can view the corresponding PRISM code (as generated by the PEPA-to-PRISM compiler)
by selecting menu option "Model | View | Parsed PRISM model".
SBML
PRISM includes a (prototype) tool to translate specifications in SBML (Systems Biology Markup Language) to model descriptions in the PRISM language. SBML is an XML-based format for representing models of biochemical reaction networks. The translator works with Level 2 SBML files (it was written for Level 2 Version 1); see the SBML specifications.
Since PRISM is a tool for analysing discrete-state systems, the translator is designed for SBML files intended for discrete stochastic simulation. A useful set of such files can be found in the CaliBayes Discrete Stochastic Model Test Suite. There are also many more SBML files available in the BioModels.
We first give a simple example of an SBML file and its PRISM translation. We then give some more precise details of the translation process.
Example
An SBML file comprises a set of species and a set of reactions which they undergo. Below is the SBML file for the simple reversible reaction: Na + Cl ↔ Na+ + Cl-, where there are initially 100 Na and Cl atoms and no ions, and the base rates for the forwards and backwards reactions are 100 and 10, respectively.
<?xml version="1.0" encoding="UTF-8"?>
<sbml xmlns="http://www.sbml.org/sbml/level2" metaid="_000000" level="2" version="1">
  <model id="nacl" name="Na+Cl">

    <listOfCompartments>
      <compartment id="compartment"/>
    </listOfCompartments>

    <listOfSpecies>
      <species id="na" initialAmount="100" hasOnlySubstanceUnits="true"/>
      <species id="cl" initialAmount="100" hasOnlySubstanceUnits="true"/>
      <species id="na_plus" initialAmount="0" hasOnlySubstanceUnits="true"/>
      <species id="cl_minus" initialAmount="0" hasOnlySubstanceUnits="true"/>
    </listOfSpecies>

    <listOfReactions>
      <reaction id="forwards" reversible="false">
        <listOfReactants>
          <speciesReference species="na"/>
          <speciesReference species="cl"/>
        </listOfReactants>
        <listOfProducts>
          <speciesReference species="na_plus"/>
          <speciesReference species="cl_minus"/>
        </listOfProducts>
        <kineticLaw>
          <math xmlns="http://www.w3.org/1998/Math/MathML">
            <apply><times/><ci>forwards_rate</ci>
              <apply><times/><ci>na</ci><ci>cl</ci></apply></apply>
          </math>
          <listOfParameters>
            <parameter id="forwards_rate" value="100"/>
          </listOfParameters>
        </kineticLaw>
      </reaction>

      <reaction id="backwards" reversible="false">
        <listOfReactants>
          <speciesReference species="na_plus"/>
          <speciesReference species="cl_minus"/>
        </listOfReactants>
        <listOfProducts>
          <speciesReference species="na"/>
          <speciesReference species="cl"/>
        </listOfProducts>
        <kineticLaw>
          <math xmlns="http://www.w3.org/1998/Math/MathML">
            <apply><times/><ci>backwards_rate</ci>
              <apply><times/><ci>na_plus</ci><ci>cl_minus</ci></apply></apply>
          </math>
          <listOfParameters>
            <parameter id="backwards_rate" value="10"/>
          </listOfParameters>
        </kineticLaw>
      </reaction>
    </listOfReactions>

  </model>
</sbml>
And here is the resulting PRISM code:
// File generated by automatic SBML-to-PRISM conversion
// Original SBML file: nacl.xml

ctmc

const int MAX_AMOUNT = 100;

// Parameters for reaction forwards
const double forwards_rate = 100; // forwards_rate

// Parameters for reaction backwards
const double backwards_rate = 10; // backwards_rate

// Species na
const int na_MAX = MAX_AMOUNT;
module na

	na : [0..na_MAX] init 100; // Initial amount 100

	// forwards
	[forwards] na > 0 -> (na'=na-1);
	// backwards
	[backwards]  na <= na_MAX-1 -> (na'=na+1);

endmodule

// Species cl
const int cl_MAX = MAX_AMOUNT;
module cl

	cl : [0..cl_MAX] init 100; // Initial amount 100

	// forwards
	[forwards] cl > 0 -> (cl'=cl-1);
	// backwards
	[backwards]  cl <= cl_MAX-1 -> (cl'=cl+1);

endmodule

// Species na_plus
const int na_plus_MAX = MAX_AMOUNT;
module na_plus

	na_plus : [0..na_plus_MAX] init 0; // Initial amount 0

	// forwards
	[forwards]  na_plus <= na_plus_MAX-1 -> (na_plus'=na_plus+1);
	// backwards
	[backwards] na_plus > 0 -> (na_plus'=na_plus-1);

endmodule

// Species cl_minus
const int cl_minus_MAX = MAX_AMOUNT;
module cl_minus

	cl_minus : [0..cl_minus_MAX] init 0; // Initial amount 0

	// forwards
	[forwards]  cl_minus <= cl_minus_MAX-1 -> (cl_minus'=cl_minus+1);
	// backwards
	[backwards] cl_minus > 0 -> (cl_minus'=cl_minus-1);

endmodule

// Reaction rates
module reaction_rates

	// forwards
	[forwards] (forwards_rate*(na*cl)) > 0 -> (forwards_rate*(na*cl)) : true;
	// backwards
	[backwards] (backwards_rate*(na_plus*cl_minus)) > 0 -> (backwards_rate*(na_plus*cl_minus)) : true;

endmodule

// Reward structures (one per species)

// 1
rewards "na" true : na; endrewards
// 2
rewards "cl" true : cl; endrewards
// 3
rewards "na_plus" true : na_plus; endrewards
// 4
rewards "cl_minus" true : cl_minus; endrewards
From the latter, we can use PRISM to generate a simple plot of the expected amount of Na and Na+ over time (using both model checking and a single random trace from the simulator):
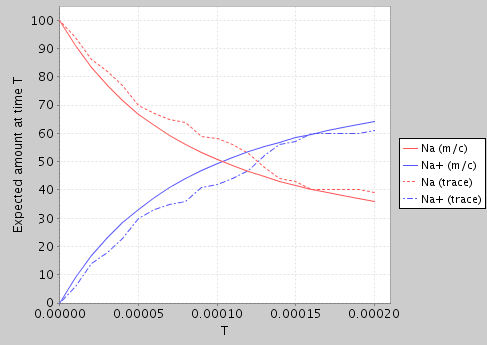
Using the translator
The SBML-to-PRISM translator is included in the PRISM code-base, but not integrated into the application itself.
cd prism
java -cp classes prism.SBML2Prism sbml_file.xml > prism_file.prism
If you are using a binary (rather than source code) distribution of PRISM, replace classes with lib/prism.jar in the above.
Alternatively (on Linux or macOS), ensure prism is in your path and then save the script below as an executable file called sbml2prism:
#!/bin/sh

# Startup script for SBML-to-PRISM translator

# Launch using main PRISM script
PRISM_MAINCLASS="prism.SBML2Prism"
export PRISM_MAINCLASS
prism "$@"
Then use:
sbml2prism sbml_file.xml > prism_file.prism
The following PRISM properties file will also be useful:
const double T;
const int c;

R{c}=? [I=T]
This contains a single property which, based on the reward structures in the PRISM model generated by the translator, means "the expected amount of species c at time T". The constant c is an integer index which can range between 1 and N, where N is the number of species in the model. To view the expected amount of each species over time, create an experiment in PRISM which varies c from 1 to N and T over the desired time range.
Details of the translation
The basic structure of the translation process is as follows:
-
Each species in the SBML file is represented by a module in the resulting PRISM file. This module, which (where possible) retains the SBML species id as its name, contains a single variable whose value represents the amount of the species present. A corresponding reward structure for computing the expected amount of the species at a given time instant is also created. Species for which the
boundaryConditionflag is set totruein the SBML file do not have a corresponding module. -
Each reaction in the SBML file is associated with a unique synchronisation action label. The module for each species which takes part in the reaction will include a synchronous command to represent this. An additional PRISM module called
reaction_ratesstores the expression representing the rate of each reaction (from the correspondingkineticLawsection in the SBML file). Reaction stoichiometry information is respected but must be provided in the scalarstoichiometryfield of aspeciesReferenceelement, not in a separateStoichiometryMathelement. -
Each parameter in the SBML file, either global to the file or specific to a reaction, becomes a constant in the PRISM file. If a value for this parameter is given, it is used. If not, the constant is left as undefined.
As described above, this translation process is designed for discrete systems and so the amount of each species in the model is represented by an integer variable. It is therefore assumed that the initial amount for each species specified in the SBML file is also given as an integer. If this is not the case, then the values will need to be scaled accordingly first.
Furthermore, since PRISM is primarily a model checking (rather than simulation) tool, it is important that the amount of each species also has an upper bound (to ensure a finite state space). When model checking, the efficiency (or even feasibility) of the process is likely to be very sensitive to the upper bound(s) chosen. When using the discrete-event simulation functionality of PRISM, this is not the case and the bounds can be set much higher. By default the translator uses an upper bound of 100 (which is increased if the initial amount exceeds this). A different value can be specified through a second command-line argument as follows:
cd prism
java -cp classes prism.SBML2Prism sbml_file.xml 1000 > prism_file.prism
Alternatively, upper bounds can be modified manually after the translation process.
Finally, the following aspects of SBML files are not supported and are ignored during the translation process:
- compartments
- events/triggers
Configuration and performance
PRISM is highly configurable, in terms of the various model checking algorithms and techniques that it uses, and the different ways that they are implemented and parameterised.
Changing settings
GUI: In the GUI, select "Options" from the main menu to bring up the "Options" dialog. The first two tabs contain core PRISM settings, discussed in this section, and simulator options; the others configure aspects of the GUI itself. If you wish, you can choose "Save Options" to store your changes in a settings file, to be reloaded as defaults next time. To restore the default settings, click "Load Defaults" and then "Save Options".
Command line:
From the command line, settings are changed via switches.
You can use either -switch or --switch and many options have abbreviations,
so for example these are all equivalent:
prism model.prism model.props -ex
prism model.prism model.props -explicit
prism model.prism model.props --explicit
See the "Command-line switches" section for a full list, or type prism -help.
To display details of a switch, use:
prism -help exportmodel
The command-line version ignores the GUI settings file,
unless you choose to load it with the -settings switch,
e.g., on Linux: prism -settings ~/.config/prism.settings.
Contents
This section guides you through some of the key settings for PRISM.
- Computation engines: PRISM's various computation engines and how to choose one
- Solution methods and options: methods available for numerical computation and their configuration
- Automata generation: how LTL formulas are converted to automata, including with external tools
- Memory and model size: memory settings for PRISM, Java and the CUDD library
- Other options: output and logging, model construction and model checking options, and more
See also the guidance on running out of memory.
Settings file
The PRISM settings file, used primarily by the GUI, is in a simple textual format and can also be edited by hand, or deleted to restore the default settings the next time the GUI is started. Where it is stored depends on the operating system:
$HOME/.prism(if this file already exists, as created by PRISM versions before 4.5)$XDG_CONFIG_HOME/prism.settings(on Linux, if that environment variable is set)$HOME/.config/prism.settings(on Linux, if$XDG_CONFIG_HOMEis not set)$HOME/Library/Preferences/prism.settings(on macOS).prismin the user's home directory, e.g.C:\Users\username(on Windows)
Computation engines
PRISM contains multiple engines: these are distinct implementations of model checking, differing in the data structures and technologies used, and in the range of models and properties that they can handle.
Core engines
There are four core engines, listed below, which are general purpose and all cover the majority of PRISM's functionality for the three most commonly used models of DTMCs, MDPs and CTMCs. These should yield the same results for the same model and property (assuming that the same algorithms and settings are used) but vary in performance and scalability (i.e., time and memory usage). The latter is discussed in more detail in "Which engine should I use?" below.
-
The explicit engine: implemented purely in Java, using explicit-state data structures (sparse matrices and variants). This supports the widest selection of solution methods, and also the most different model types, for example, it is the only engine that supports POMDPs and uncertain MDPs/DTMCs. PRISM will usually switch to this engine automatically if it is the only one that can handle a particular model, property or solution method.
-
The MTBDD engine: fully symbolic, storing both the model and the value vectors computed from it as binary decision diagrams (BDDs) and multi-terminal BDDs (MTBDDs). This engine can handle extremely large models, as long as they are structured and regular.
-
The sparse engine: builds the model symbolically, as an MTBDD, but then converts it to a sparse matrix for numerical computation. This typically makes it faster to solve, but may use more memory.
-
The hybrid engine (the default): builds the model symbolically, like the sparse engine, and performs numerical computation with a combination of MTBDDs (for the model) and arrays (for vectors), representing a trade-off between memory usage and solution speed [KNP04b].
PRISM's MTBDD, sparse and hybrid engines are referred to collectively as its symbolic engines, since they all rely on a symbolic (MTBDD-based) representation of the model being built first. These engines are mostly implemented in C++, using the CUDD library for BDDs and MTBDDs.
When using the PRISM GUI, the engine to be used for model checking can be selected from the "Engine" option under the "PRISM" tab of the "Options" dialog. From the command-line, engines are activated using the -explicit, -mtbdd, -sparse and -hybrid (or -ex, -m, -s and -h, respectively) switches, e.g.:
prism model.prism model.props -ex
prism model.prism model.props -m
prism model.prism model.props -s
prism model.prism model.props -h
Other engines
PRISM's other engines typically work on a specific set of models and/or properties, and may also vary in the accuracy of the results that they compute.
-
The statistical model checking engine generates approximate results using discrete-event simulation, and without building the full model, often improving scalability but at the cost of accuracy. From the GUI, it is used by choosing "Simulate" menu items or tick boxes; from the command-line, add the
-simswitch. See "Statistical model checking" for details. -
The exact engine computes exact numerical results, using arbitrary precision arithmetic. You can enable this functionality using the "Do exact model checking" option in the GUI or using switch
-exactfrom the command line. This is implemented as a special case of parametric model checking, which limits its application to relatively small models. It can be used for analysing DTMCs/CTMCs (unbounded until, steady-state probabilities, reachability reward and steady-state reward) or MDPs (unbounded until and reachability rewards). -
The parametric engine computes results exactly, as functions of the model's parameters. It is used with the
-paramswitch: see "Parametric model checking". -
PTA model checking is performed with one of three specific engines, stochastic games, digital clocks and backwards reachability, which are described in "Real-time models". These are chosen with the "PTA model checking method" setting in the GUI or the
-ptamethodswitch on the command line.
Which engine should I use?
Sometimes a specific engine is required for a particular model (e.g., for PTAs) or is requested in order to achieve a particular accuracy (e.g., exact or parametric results). Similarly, the explicit engine is sometimes the only option for a model class, such as POMDPs and uncertain MDPs/DTMCs.
In other cases, any of the four core engines can normally be used, with the current default being the hybrid engine. If PRISM is using too much time or memory with one engine, it may be worth experimenting with others, since their performance can vary, depending on the size of the model and how it is described. Details of the memory usage and model size are displayed during model checking (from the GUI, check the "Log" tab).
-
The explicit engine has the most predictable performance, with time and memory usage increasing as the size of the model does. Unlike the symbolic engines, performance does not depend on how compact a model's MTBDD-based representation is, which can be unpredictable. Building the model is often slower using the explicit engine, but the solution time is more comparable to that of the other core engines. The explicit engine is usually the best choice when:
-
importing from explicit-state formats, such as UMB (
.umb) or PRISM's own "explicit" file formats (.pexp,.tra, etc.); -
building "explicit-style" PRISM models (i.e., essentially comprising an unstructured list of states/transitions, but encoded into a textual description in the PRISM modelling language);
-
building models that are potentially very large, in terms of the number of model variables and their range, but where only a small fraction of states are reachable.
-
-
The hybrid engine, amongst the three symbolic engines, generally provides the best compromise between time and memory usage: it uses less memory than the sparse engine, but is typically slightly slower.
-
The sparse engine can be a good alternative to the hybrid engine when model checking takes a long time, but the model is small enough to fit in memory (as a rule of thumb, the sparse engine scales up to models about a factor of 10 smaller than the hybrid one).
-
The MTBDD engine has the potential to scale up to very large models, beyond the range of what can be handled by the other three, but is much more unpredictable in terms of performance. Roughly speaking, when the model description (in the PRISM language) exhibits a lot of structure and regularity, it can be very effective. But the MTBDD engine often performs poorly when the model (or solutions computed from it) contain many distinct probabilities/rates; it performs best when there are few such values. For this reason the engine is often successfully applied to MDP models, but much less frequently to CTMCs.
For all three symbolic engines (MTBDD, sparse, hybrid), various aspects of the (PRISM language) model description can impact performance, including its variable ordering; see "PRISM modelling" in the FAQ for details.
Symbolic engine options
A few further settings fine-tune the symbolic engines. The defaults are usually fine.
- Hybrid engine: to speed up numerical computation, the hybrid engine replaces the lowest levels of its MTBDDs with sparse matrices [Par02].
The number of levels replaced is set with
-sbl <n>(the default, -1, lets PRISM choose) and the memory these sparse matrices can use, in KB, with-sbmax <n>(default 1024). For the hybrid engine's Gauss-Seidel and SOR methods, the matrix is also divided into blocks:-gsl <n>and-gsmax <n>(or-sorland-sormax) set the number of MTBDD levels used for this division and its memory limit in KB. - Sparse and hybrid engines: by default, sparse matrices and vectors with many repeated values are compressed further;
-nocompactswitches this off. - CUDD, the BDD/MTBDD library: besides its memory limit (see "Memory and model size"),
-cuddepsilon <x>sets the precision used when CUDD compares values in its cache (default), and -ddextrastatevars <n>and-ddextraactionvars <n>set how many extra MTBDD variables are preallocated for transformations of the model (default 20 each).-ddsanityenables internal sanity checks, for debugging (this slows PRISM down).
Solution methods and options
Separately from the choice of engines, PRISM often offers several different solution methods that can be used for the computation of probabilities and expected costs/rewards during model checking. Many, but not all, of these are iterative numerical methods. The choice of method (and their settings) depends on the type of analysis that is being done (i.e., what type of model and property) and can also be configured using various options.
This page focuses on core properties for the most common model types (DTMCs, MDPs and CTMCs). See the other sections of the manual for solution methods available for real-time models, partially observable models, and uncertain/interval models.
Convergence
Many of the methods below are iterative: they compute a sequence of approximations to the solution and stop once it has converged sufficiently. PRISM checks for convergence by comparing the solution vectors from successive iterations (or, for interval iteration, the vectors from the iterations from below and from above). The following settings control this, and apply to all of these methods:
- "Termination epsilon" (switch
-epsilon <val>): iteration stops when the maximum difference between elements of the two vectors drops below this threshold. The default is. - "Termination criteria" (switches
-relativeand-absolute, or-reland-abs): whether that maximum difference is relative or absolute. The default is relative. - "Termination max. iterations" (switch
-maxiters <val>): an upper limit on the number of iterations, to trap cases where computation will not converge. The default is 10,000. Reaching the limit causes an error during model checking.
Linear equation systems
For many properties of Markov chains (e.g. "reachability"/"until" properties for DTMCs and CTMCs, steady-state properties for CTMCs and "reachability reward" properties for DTMCs), PRISM solves a set of linear equation systems, for which several numerical methods are available. Below is a list of the alternatives and the switches used to select them from the command-line. The corresponding GUI option is "Linear equations method".
- Power method:
-power(or-pow,-pwr) - Jacobi method:
-jacobi(or-jac) - Gauss-Seidel method:
-gaussseidel(or-gs) - Backwards Gauss-Seidel method:
-bgaussseidel(or-bgs) - JOR method (Jacobi with over-relaxation):
-jor - SOR method:
-sor - Backwards SOR method:
-bsor
When using the MTBDD engine, Gauss-Seidel/SOR based methods are not available.
When using the hybrid engine, pseudo variants of Gauss-Seidel/SOR based methods can also be used [Par02]
(see "Command-line switches" for the corresponding switches).
For methods which use over-relaxation (JOR/SOR), the over-relaxation parameter (between 0.0 and 2.0)
can also be specified with option "Over-relaxation parameter" (switch -omega <val>).
All of these are iterative methods, so the convergence settings above apply.
MDP solution methods
When analysing MDPs, there are multiple solution methods on offer. A summary, and their command-line switches, are given below. From the GUI, the first five can be selected under the "MDP solution method" option. The last two are variants that are selected as separate options, and can also be used for DTMCs. All except value iteration are only supported by the explicit engine, which PRISM switches to automatically (with a warning) if one of them is selected. Where they are iterative, the convergence settings above apply.
- Value iteration (switch
-valiter) [this is the default]: repeatedly updates the value of every state from the values of its successors, until the values converge. - Gauss-Seidel (switch
-gs): a variant of value iteration that uses newly computed values straight away, within the same iteration, which often makes it converge faster. - Policy iteration (switch
-politer): alternates between computing the values for a fixed policy/strategy and improving it, until there is no change. - Modified policy iteration (switch
-modpoliter): like policy iteration, but computes the values for each policy/strategy approximately, with a few steps of value iteration. This is only implemented for probabilities: for reward properties, PRISM switches to Gauss-Seidel (with a warning). - Linear programming (switch
-lp): encodes the problem as a linear program and solves it directly, rather than iteratively. - Interval iteration [HM14],[BKLPW17]
(switch
-intervaliteror-ii, or GUI option "Use interval iteration"): performs two separate instances of iterative solution, one from below and one from above. This gives clearer information about the accuracy of the computed values and avoids possible problems with premature convergence. A variety of options can be configured, either using-intervaliter:option1,option2,...or by setting the string "option1,option2,..." under "Interval iteration options" in the GUI. See-intervaliterin the list of command-line switches (or typeprism -help intervaliter) for the options and [BKLPW17] for the details. - Topological value iteration (switch
-topological, or GUI option "Use topological value iteration"): improves the efficiency of value iteration by analysing the graph structure of the model, and using this to update the values of states in an order that speeds up convergence. It can also be used to optimise interval iteration and the numerical solution of DTMCs. It is only implemented in the explicit engine, which PRISM switches to automatically (with a warning) if another engine is selected. The exception is DTMC/CTMC solution with a linear equation method that the explicit engine does not support (such as pseudo Gauss-Seidel or SOR), where-topologicalis ignored (again, with a warning).
CTMC transient analysis
When computing transient probabilities of a CTMC
(either directly or when verifying time-bounded operators of CSL), there are two options:
uniformisation and fast adaptive uniformisation (FAU). These can be selected using the GUI option "Transient probability computation method", or using the command-line switch -transientmethod <name>, where <name> is either unif or fau.
Uniformisation
Uniformisation is a standard iterative numerical method for computing transient probabilities on a CTMC, which works by reducing the problem to an analysis of a "uniformised" DTMC.
As an optimisation, when it is detected that the transient probabilities have converged, no further iterations are performed. If necessary (e.g. in case of round-off problems), this optimisation can be disabled with the "Use steady-state detection" option (command-line switch -nossdetect).
Fast adaptive uniformisation (FAU)
Fast adaptive uniformisation (FAU) [MWDH10] is a method to efficiently approximate transient properties of large CTMCs. The basic idea is that only the parts of the model that are relevant for the current time period are kept in memory. In more detail, starting with the initial states, in each step FAU explores further states in a DTMC which is a discrete-time version of the original CTMC. By combining the probabilities there with those of a certain continuous-time stochastic process (a birth process), transient properties in the original CTMC can be computed. If it turns out that the probability of being in some state in the DTMC is below a given threshold, this state is removed from the model explored so far. After a given number of steps, which corresponds to the number of steps which are likely to happen within the time bound, the exploration can be stopped. In the implementation in PRISM [DHK13], FAU can be used to compute transient probability distributions and to model check the following types of non-nested CSL formulas: time-bounded until, instantaneous reward, cumulative reward.
The following options can be used to configure FAU:
-
"FAU epsilon" (switch
-fauepsilon <x>): FAU analyses the DTMC for a number of iterations such that the probability of more steps being relevant is below this value. The default is 1e-6. -
"FAU cut off delta" (switch
-faudelta <x>): States that have a lower probability than this value are discarded. The default is 1e-12. -
"FAU array threshold" (switch
-fauarraythreshold <x>): After this number of steps without any new states being explored or discarded, FAU will switch to a faster, fixed-size data structure until further states have to be explored or discarded. The default is 100. -
"FAU time intervals" (switch
-fauintervals <x>): In some cases, it is advantageous to divide the time interval the analysis is done for into several smaller intervals. This option dictates the number of (equal length) intervals used for this split. The default is 1, meaning that only one time interval is used. -
"FAU initial time interval" (switch
-fauinitival <x>): It is also possible to specify an additional initial time interval which is handled separately from the rest of the time. This is often advantageous, because in this interval certain parameters of the model can be explored, which can subsequently be used to speed up the computation of the remaining time interval. The default for this option is 1.0.
Automata generation
When PRISM performs verification of LTL formulas, it does so by converting the formula into an automaton (such as a deterministic Rabin automaton) and then analysing a larger product model, constructed from the model being verified and the omega automaton. For this reason, the size of the automaton has an important effect on the efficiency of verification.
By default PRISM uses a port of the ltl2dstar library to construct these automata. But it also allows the use of external LTL-to-automata converters producing deterministic automata through support for the Hanoi Omega Automaton (HOA) format. From the command line, an example of this is:
prism model.prism -pf "P=? [ G F x=1 ]" -ltl2datool hoa-ltl2dstar-for-prism -ltl2dasyntax lbt
The -ltl2datool switch specifies the location of the program to be executed to perform the LTL-to-automaton conversion. This will be called by PRISM as "exec in-file out-file", where exec is the executable, in-file is the name of a file containing the LTL formula to be converted and out-file is the name of a file where the resulting automaton should be written, in HOA format. Typically, the executable will be a script. Here is a simple example (called as hoa-ltl2dstar-for-prism in the above example), which calls an external copy of ltl2dstar in the required fashion (assuming that the ltl2dstar and ltl2ba executables are located in the current directory or on the PATH).
#! /bin/bash
ltl2dstar --output=automaton --output-format=hoa "$1" "$2"
PRISM is known to work with these HOA-enabled tools:
and contains ready-made scripts for calling them in the etc/scripts/hoa directory of the distribution:
hoa-ltl2dstar-for-prism
(ltl2dstar, using Spot'sltl2tgba,ltl2baor LTL3BA as the LTL-to-NBA tool)hoa-ltl2tgba-for-prism
(Spot'sltl2tgba)hoa-ltl3dra-for-prism
(ltl3dra)hoa-rabinizer-for-prism
(Rabinizer'sltl2dra)
See the files themselves for details of any configuration required, possible options and for a reminder of the PRISM command-line arguments required.
There is also a hoa-rabinizer-for-prism.bat script for connecting to Rabinizer on Windows.
The -ltl2dasyntax switch is used to specify the textual format for passing the LTL formula to the external converter (i.e., in the file in-file). The options are:
lbt: LBT formatspin: SPIN formatspot: Spot formatrabinizer: Rabinizer format
Typical usage is:
prism model.prism -pf "P=? [ G F x=1 ]" -ltl2datool hoa-ltl2dstar-for-prism -ltl2dasyntax lbt
prism model.prism -pf "P=? [ G F x=1 ]" -ltl2datool hoa-ltl2tgba-for-prism -ltl2dasyntax lbt
prism model.prism -pf "P=? [ G F x=1 ]" -ltl2datool hoa-ltl3dra-for-prism -ltl2dasyntax spin
prism model.prism -pf "P=? [ G F x=1 ]" -ltl2datool hoa-rabinizer-for-prism -ltl2dasyntax rabinizer
From the GUI, configuring the external LTL converter is done with the two options "Use external LTL->DA tool" and "LTL syntax for external LTL->DA tool".
Another related option is "All path formulas via automata" (command-line switch -pathviaautomata), which forces construction of an automaton
when computing the probability of a path formula, even if it is not needed. This is primarily intended for debugging/testing, not regular use.
Likewise, by default PRISM simplifies the automata it builds, and their acceptance conditions, where it can;
-nodasimplify (GUI option "Do not simplify deterministic automata") switches this off.
As mentioned above, PRISM's external LTL-to-automaton interfacing works using the
HOA format
(and, in particular, using the jhoafparser HOA parser).
PRISM can handle automata in HOA format that are
deterministic and complete, with state-based acceptance.
Automata with transition-based acceptance are converted to state-based acceptance by PRISM.
For DTMC and CTMC model checking, generic acceptance conditions are supported, i.e.,
anything that can be specified as an Acceptance: header in HOA format.
For MDP model checking, Rabin and generalised Rabin acceptance
specified via the acc-name: header are supported. See the HOA format specification for details.
Memory and model size
Probabilistic model checking can need a lot of memory. This page describes how PRISM uses memory, and how to give it more. See also the "Memory problems" section of the FAQ.
CUDD memory
CUDD, the underlying BDD and MTBDD library used in PRISM's symbolic engines, has an upper memory limit.
By default, this limit is 1 GB. If you are working on a machine with significantly more memory than this and PRISM runs out of memory when model checking, it may help to change this. To set the limit, from the command-line, use the -cuddmaxmem switch. For example:
prism -cuddmaxmem 2g big_model.prism
Above, g denotes GB. You can also use m for MB.
You can also change the CUDD maximum memory setting from the options panel in the GUI, but you will need to close and restart the GUI (saving the settings as you do) for this to take effect.
Java memory
The Java virtual machine (JVM) used to execute PRISM also has upper memory limits.
This is more likely to impact the explicit engine.
Sometimes this limit will be exceeded and you will see an error of the form java.lang.OutOfMemoryError. To resolve this problem, you can increase this memory limit. On Unix, Linux or macOS platforms, this can be done by using the -javamaxmem switch, passed either to the command-line script prism or the GUI launcher xprism. For example:
prism -javamaxmem 4g big_model.prism
xprism -javamaxmem 4g big_model.prism
each set the limit to 4 GB. Alternatively, you can set the environment variable PRISM_JAVAMAXMEM before running PRISM. For example, under a bash shell:
PRISM_JAVAMAXMEM=4g
export PRISM_JAVAMAXMEM
prism big_model.prism
If you get an error of the form java.lang.StackOverflowError, then you can try increasing the stack size of the JVM.
On Unix, Linux or macOS platforms, this can be done by using the -javastack switch or the PRISM_JAVASTACKSIZE environment variable.
Examples are:
prism -javastack 1g big_model.prism
xprism -javastack 1g big_model.prism
or:
PRISM_JAVASTACKSIZE=1g
export PRISM_JAVASTACKSIZE
prism big_model.prism
If you are running PRISM on Windows you will have to make adjustments to Java memory manually, by modifying the prism.bat or xprism.bat scripts.
To set the memory to 4 GB, for example, add -Xmx4g to the list of arguments in the call to java or javaw at the end of the file.
To change the stack size to 1 GB, add -Xss1g.
Other Java options
If you want to pass additional switches to the JVM used to run PRISM, you can use the -javaparams switch.
For example:
prism -javaparams "-XX:AutoBoxCacheMax=100000000 -Xmn2g" -javamaxmem 12g big_model.prism
Alternatively (or in conjunction with -javaparams), the PRISM_JAVA_PARAMS environment variable passes switches to the JVM.
Finally, the PRISM_JAVA environment variable can be used to specify the java executable to use (by default, it is the one on your path).
Other options
This page describes some further options, not covered elsewhere in this section. All the options available from the command line are listed in "Command-line switches".
Output and logging
From the command line, the log can be written to a file instead of the screen with -mainlog <file>;
add :append (e.g. -mainlog log.txt:append) to add to the end of an existing file rather than overwrite it.
To increase the amount of information displayed by PRISM (in particular, to display lists of states and probability vectors), you can use the "Verbose output" option (activated with command-line switch -verbose or -v). To display additional statistics about MTBDDs after model construction, use the "Extra MTBDD information" option (switch -extraddinfo) and, to view MTBDD sizes during the process of reachability, use option "Extra reachability information" (switch -extrareachinfo).
To see how iterative numerical methods progress, the switch -exportiterations
(or GUI option "Export iterations (debug/visualisation)") writes the solution vector at each iteration to the file iterations.html, for debugging or visualisation.
Model construction
Probability/rate checks
By default, when constructing a model, PRISM checks that all probabilities and rates are within acceptable ranges (i.e. are between 0 and 1, or are non-negative, respectively). For DTMCs and MDPs, it also checks that the probabilities sum up to one for each command. These checks are often very useful for highlighting user modelling errors and it is strongly recommended that you keep them enabled, however if you need to disable them you can do so via option "do prob checks?" in the GUI or command-line switch -noprobchecks.
You can also change the level of precision used to check that probabilities sum to 1 using the option "Probability sum threshold" (or command-line switch -sumroundoff).
Model checking
Precomputation
By default, PRISM's probabilistic model checking algorithms use an initial precomputation step which uses graph-based techniques to efficiently detect trivial cases where probabilities are 0 or 1. This can often result in improved performance and also reduce round-off errors. Occasionally, though, you may want to disable this step for efficiency (e.g. if you know that there are no/few such states and the precomputation process is slow). This can be done with the -nopre switch. You can also disable the individual algorithms for probability 0/1 using switches -noprob0 and -noprob1.
The explicit engine speeds up precomputation (and some other graph algorithms) by first computing the predecessor relation of the model;
-noprerel switches this off, saving the memory it needs.
Fairness
Sometimes, model checking of properties for MDPs requires fairness constraints to be taken into account.
See e.g. [BK98],[Bai98] for more information.
To enable the use of fairness constraints (for P operator properties), use the -fair switch.
End components
For maximum probabilities in MDPs, the switch -pmaxquotient
makes PRISM first collapse each maximal end component (MEC) of the model into a single state, and compute in this quotient model.
SCC decomposition
Some algorithms, e.g. for steady-state probabilities and LTL model checking, decompose the model into strongly connected components (SCCs).
For the symbolic engines, the algorithm used for this can be chosen with -sccmethod <name>
(or the GUI option "SCC decomposition method"): xiebeerel, lockstep (the default) or sccfind.
Time-outs
The command-line version of PRISM has a time-out option, specified using the switch -timeout <n>.
This causes the program to exit after <n> seconds if it has not already terminated by that point.
This is particularly useful for benchmarking scenarios where you wish to ignore runs of PRISM that exceed a certain length of time.
Reference
Here, we collate various reference documents related to PRISM and its usage/configuration.
Contents
- PRISM language syntax: precise details for various aspects of the PRISM language
- Command-line switches: all the switches of the command-line version of PRISM, as listed by
prism -help - Explicit model files: specification of "explicit" files formats for model exports/imports
- References: papers cited in this manual
PRISM language syntax
This reference documents various aspects of the PRISM language syntax, covering both model and property specification.
Model and property files
Files containing models specified in the PRISM modelling language
and properties expressed in the PRISM property specification language
are stored as plain text files, with the file extensions .prism and .props, respectively.
Files can contain any amount of white space (spaces, tabs, new lines, etc.),
all of which is ignored when the file is parsed.
Comments are written using //, which starts a comment that runs to the end of the line.
Model types
A model type keyword, usually at the very start of a model file, indicates the type of model being specified, and can be any of the following:
dtmc(DTMC: discrete-time Markov chain)ctmc(CTMC: continuous-time Markov chain)mdp(MDP: Markov decision process)pta(PTA: probabilistic timed automaton)pomdp(POMDP: partially observable MDP)popta(POPTA: partially observable PTA)
Based on features that are included in a model, PRISM will, to some extent, auto-detect the model type if no keyword is given and adapt the model type beyond the keyword if features are added that require a different type. Indeed, some model types do not have explicit keywords (e.g., interval MDPs), and are only identified by the features that they use.
- The default model type is MDP, unless no probabilities are used, in which case it is an LTS (labelled transition system).
- An MDP model with clock variables
is treated as a PTA, even if the
ptakeyword is not used. - An MDP or PTA with observables is treated as a POMDP or POPTA (partially observable PTA), respectively.
- If a model uses intervals for probabilities, it is treated as an interval variant: an IDTMC (interval DTMC) or IMDP (interval MDP).
Identifiers and keywords
Identifiers (names of modules, variables, constants, formulas and so on)
are made up of letters, digits and underscores, but cannot start with a digit:
they match [A-Za-z_][A-Za-z0-9_]*. They are case-sensitive.
They cannot be any of PRISM's keywords:
A, bool, C, clock, const, ctmc, double, dtmc, E, endinit, endinvariant, endmodule, endobservables, endrewards, endsystem, F, false, filter, formula, func, G, global, I, init, int, invariant, label, max, maxmax, maxmin, mdp, min, minmax, minmin, module, nondeterministic, observable, observables, P, Pmax, Pmaxmax, Pmaxmin, Pmin, Pminmax, Pminmin, pomdp, popta, prob, probabilistic, pta, R, rate, rewards, Rmax, Rmaxmax, Rmaxmin, Rmin, Rminmax, Rminmin, S, stochastic, system, true, U, W, X.
Uniqueness: The names of variables (global, or local to any module), constants and formulas share a single namespace,
so they must all be distinct.
Constants defined in a properties file must also be distinct from all of these names in the model.
Modules, actions and reward structures each have their own, separate, namespace,
so their names only need to be unique within their own category, not across all names in the model.
Names written in quotes, i.e., those of labels, observables and named properties, form another namespace:
these must be distinct from each other, across both the model and the properties file.
The labels "init" and "deadlock" are built in and cannot be redefined.
Expressions
Expressions are used in both models and properties. Depending on the context, they can include references to variables, constants and labels, as well as various operators, literals and functions.
Operators
The table below lists operators that can be used in expressions, from the most strongly binding (1) to least.
| Precedence | Operator | Meaning | Associativity |
|---|---|---|---|
| 1 | - |
unary minus | |
| 2 | ^ |
power | right |
| 3 | *, / |
multiplication, division | left |
| 4 | +, - |
addition, subtraction | left |
| 5 | <, <=, >=, > |
relational operators | left |
| 6 | =, != |
equality operators | left |
| 7 | ! |
negation | |
| 8 | & |
conjunction | left |
| 9 | | |
disjunction | left |
| 10 | <=> |
if-and-only-if | left |
| 11 | => |
implication | right |
| 12 | ? : |
condition: c ? a : b is a if c is true and b otherwise |
right |
So, for example, -x^2 means (-x)^2, and 2^3^2 means 2^(3^2).
Division / always gives a double, not integer division: 22/7 is 3.142857..., not 3.
In properties, the temporal operators bind less tightly than all of these.
Literals
- Integers:
0,42 - Doubles:
0.5,.5,1e-3,2.5E+6 - Booleans:
true,false
Built-in functions
| Function | Result |
|---|---|
min(a,b,...), max(a,b,...) |
minimum or maximum of two or more numbers |
floor(x), ceil(x) |
x rounded down or up to an integer |
round(x) |
x rounded to the nearest integer (ties round up: round(-1.5) is -1) |
pow(x,y) |
x to the power y (as x^y) |
mod(i,n) |
i modulo n (mod(-7,3) is 2) |
log(x,b) |
logarithm of x to base b |
Legacy syntax
Older versions of PRISM used some different conventions and syntax, which are still accepted for compatibility. New models and properties should use the current forms.
- File extensions: model files used to have extensions
.pm(DTMCs),.nm(MDPs, PTAs) or.sm(CTMCs), not.prism. - File extensions: property files used to have extensions
.pctlor.csl, not.props. - Model types:
probabilistic,nondeterministicandstochasticwere formerly synonyms fordtmc,mdp,ctmc. - Integer-valued constants: were previously declared as
const N = 5;, meaningconst int N = 5;. - Double-valued constants: could previously also be written as
rate r = 0.5;orprob p = 0.1;, meaningconst double r = 0.5;. - Functions: could be written with a special
funckeyword, e.g.,func(floor, x)orfunc(min, a, b), instead of the current formsfloor(x)andmin(a, b). - Filters: the old-style syntax for filters in properties was, e.g.,
P=? [ path {states} ]forfilter(state, P=? [ path ], states), with{states}{min},{states}{max}and{states}{min}{max}for themin,maxandrangefilters.
Command-line switches
This page lists the switches accepted by the command-line version of PRISM,
grouped as in the output of prism -help.
Many of them are described in more detail elsewhere in this manual,
and most of the settings they change can also be made in the GUI (from the Options menu)
or in the settings file.
For switches whose syntax is not obvious, prism -help followed by the switch, e.g., prism -help exportmodel,
gives the details shown below.
The list is generated from PRISM itself, so it is complete for this version of PRISM.
Switches are typed with a single -, as shown, but -- also works, e.g., --version.
General
-
-mainlog <file>[:<options>]: Write the log to <file> instead of stdoutIf provided, <options> is a comma-separated list of options taken from:
append: Append to the log file, rather than overwriting it
-
-pf <props>(or-pctl,-csl): Model check properties <props> -
-property <refs>(or-prop): Only model check properties included in list <refs> of indices/names -
-const <vals>: Define constant values as <vals> (e.g. for experiments)<vals> is a comma-separated list of values or value ranges for undefined constants in the model or properties (i.e. those declared without values, such as "const int a;"). You can either specify a single value (a=1), a range (a=1:10) or a range with a step (a=1:2:50). For convenience, constant definitions can also be split across multiple -const switches.
Examples:
-const a=1,b=5.6,c=true -const a=1:10,b=5.6 -const a=1:2:50,b=5.6 -const a=1:2:50 -const b=5.6 -
-steadystate(or-ss): Compute steady-state probabilities (D/CTMCs only) -
-transient <x>(or-tr): Compute transient probabilities for time (or time range) <x> (D/CTMCs only) -
-simpath <options> <file>: Generate a random path with the simulatorGenerate a random path with the simulator and export it to <file> (or to the screen if <file>="stdout"). <options> is a comma-separated list of options taken from:
<n>: generate a path of <n> stepstime=<x>: generate a path of at least <x> time unitsdeadlock: generate a path until a deadlock is reachedrepeat=<n>: try <n> paths until a deadlock is foundsep=<val>: use <val> as column separator (space, tab, comma)vars=<x1,x2,...>: show values for variables x1,x2,.. onlyloopcheck=<true|false>: whether to detect deterministic loopssnapshot=<x>: view states at fixed timepoints of interval <x>probs=<true|false>: display probability (or rate) of transitions takenrewards=<true|false>: display state/transition rewardschanges=<true|false>: only display states where displayed variables change
-
-test[:<options>]: Enable "test" modeIf provided, <options> is a comma-separated list of options taken from:
umb: Enable UMB round trip testpexp: Enable explicit (.pexp) round trip test
-
-javamaxmem <x>: Set the maximum heap size for Java, e.g. 500m, 4g [default: 1g] -
-javaparams <x>: Pass additional command-line arguments to Java -
-timeout <n>: Exit after a time-out of <n> seconds if not already terminated -
-ng: Run PRISM in Nailgun server mode; subsequent calls are then made via "ngprism"
Imports
-
-importpepa: Model description is in PEPA, not the PRISM language -
-importmodel <files>[:<options>]: Import the model directly from file(s)Import the model directly from one or more file(s). Use a list of file extensions to indicate which files should be read, e.g.:
-importmodel in.tra,staPossible extensions are: .tra, .sta, .obs, .lab, .srew, .trew, .pexp, .umb Use extension .all to import all explicit files (.tra/sta/obs/lab/srew/trew), e.g.:
-importmodel in.allIf provided, <options> is a comma-separated list of options taken from:
format(=explicit/umb): model import format
-
-importtrans <file>: Import the transition matrix directly from a text file -
-importstates <file>: Import the list of states directly from a text file -
-importobs <file>: Import the list of observations directly from a text file -
-importlabels <file>: Import the list of labels directly from a text file -
-importstaterewards <file>: Import the state rewards directly from a text file -
-importtransrewards <file>: Import the transition rewards directly from a text file -
-importinitdist <file>: Specify initial probability distribution for transient/steady-state analysis -
-importresults <file>: Import results from a data frame stored in CSV fileImport results from a data frame stored as comma-separated values in <file>.
Exports
-
-exportresults <file[:<options>]>: Export the results of model checking to a fileExports the results of model checking to <file> (or to the screen if <file>="stdout"). The default behaviour is to export a list of results in text form, using tabs to separate items. If provided, <options> is a comma-separated list of options taken from:
csv: Export results as comma-separated valuesmatrix: Export results as one or more 2D matrices (e.g. for surface plots)dataframe: Export results as dataframe in comma-separated valuescomment: Export results in comment format for regression testing
-
-exportvector <file>: Export results of model checking for all states to a file -
-exportmodel <files[:<options>]>: Export the built model to file(s)Export the built model to file(s) (or to the screen if <file>="stdout"). Use a list of file extensions to indicate which files should be generated, e.g.:
-exportmodel out.tra,sta
-exportmodel out.umb
Possible extensions are: .tra, .srew, .trew, .lab, .sta, .obs, .dot, .umb, .drn Use extension .all to export all explicit files (.tra/srew/trew/lab/sta/obs), e.g.:
-exportmodel out.allOmit the file basename to use the basename of the model file, e.g.:
-exportmodel .allUse extension .rew to export both .srew/.trew files
If provided, <options> is a comma-separated list of options taken from:
format(=explicit/matlab/dot/drn/umb): model export formatrewards(=true/false, or bare for true): whether to include rewardslabels(=true/false, or bare for true): whether to include labelsstates(=true/false, or bare for true): whether to include state definitionsobs(=true/false, or bare for true): whether to include observation definitionsactions(=true/false, or bare for true): whether to include actions on choices/transitionsprecision(=<n>): use <n> significant figures for floating point values (in text)zip(=true/false/gzip/xz): whether to zip UMB filestext: show binary formats in textual formmatlab: same as format=matlabrows: export matrices with one row/distribution on each lineproplabels: also export labels from a properties file into the same file, tooheaders(=true/false, or bare for true): include headers in explicit model files
-
-exporttrans <file>[:<options>]: Export the transition matrix to a fileIf provided, <options> is a comma-separated list of options taken from:
precision(=<n>): use <n> significant figures for floating point values (in text)headers(=true/false, or bare for true): include headers in explicit model files
-
-exportstaterewards <file>[:<options>]: Export the state rewards vector to a fileIf provided, <options> is a comma-separated list of options taken from:
precision(=<n>): use <n> significant figures for floating point values (in text)headers(=true/false, or bare for true): include headers in explicit model files
-
-exporttransrewards <file>[:<options>]: Export the transition rewards matrix to a fileIf provided, <options> is a comma-separated list of options taken from:
precision(=<n>): use <n> significant figures for floating point values (in text)headers(=true/false, or bare for true): include headers in explicit model files
-
-exportrewards <file1[:<options>]> <file2[:<options>]>: Export state/transition rewards to files 1/2Export state/transition rewards to files 1/2 (or to the screen if <file>="stdout").
If provided, <options> is a comma-separated list of options (for either file) taken from:
precision(=<n>): use <n> significant figures for floating point values (in text)headers(=true/false, or bare for true): include headers in explicit model files
-
-exportstates <file>[:<options>]: Export the list of reachable states to a fileIf provided, <options> is a comma-separated list of options taken from:
precision(=<n>): use <n> significant figures for floating point values (in text)headers(=true/false, or bare for true): include headers in explicit model files
-
-exportobs <file>[:<options>]: Export the list of observations to a fileIf provided, <options> is a comma-separated list of options taken from:
precision(=<n>): use <n> significant figures for floating point values (in text)headers(=true/false, or bare for true): include headers in explicit model files
-
-exportlabels <file[:<options>]>: Export the list of labels and satisfying states to a fileIf provided, <options> is a comma-separated list of options taken from:
precision(=<n>): use <n> significant figures for floating point values (in text)headers(=true/false, or bare for true): include headers in explicit model filesmatlab: export data in Matlab formatproplabels: export labels from a properties file into the same file, too
-
-exportproplabels <file[:<options>]>: Export the list of labels and satisfying states from the properties file to a fileIf provided, <options> is a comma-separated list of options taken from:
precision(=<n>): use <n> significant figures for floating point values (in text)headers(=true/false, or bare for true): include headers in explicit model filesmatlab: export data in Matlab format
-
-exportstrat <file[:<options>]>: Generate and export a strategy to a fileGenerate and export a strategy to a file (or to the screen if "stdout"). Use file extension .tra, .pexp, .umb or .dot to export as an induced model. The default (e.g. for file extension .txt) is a list of state-action choices.
If provided, <options> is a comma-separated list of options taken from:
type(=actions/indices/induced/dot): type of strategy exportmode(=restrict/reduce): mode to use for building induced model (or Dot file)reach(=true/false, or bare for true): whether to restrict the strategy to its reachable statesstates(=true/false, or bare for true): whether to include full state informationmergeobs(=true/false, or bare for true): for partially observable models, whether to merge observationally equivalent statesundefined(=stop/loop/first/all/error): how to resolve undefined choices, for all reasons except unknownunknown(=stop/loop/first/all/error): how to resolve undefined choices when there is no information about themarbitrary(=stop/loop/first/all/error): how to resolve undefined choices where any choice is equally goodsatisfied(=stop/loop/first/all/error): how to resolve undefined choices after the objective is satisfiedunsatisfiable(=stop/loop/first/all/error): how to resolve undefined choices when the objective can no longer be satisfiedhorizon(=stop/loop/first/all/error): how to resolve undefined choices after a step boundunreachable(=stop/loop/first/all/error): how to resolve undefined choices in states not reachable under the strategyshowundef(=true/false, or bare for true): whether to also show undefined choices (and why) when exporting actions/indicesformat(=explicit/dot/drn/umb): model export format for induced model exportrewards(=true/false, or bare for true): whether to include rewards for induced model exportlabels(=true/false, or bare for true): whether to include labels for induced model exportactions(=true/false, or bare for true): whether to include actions on choices/transitions for induced model exportobs(=true/false, or bare for true): whether to include observation details for induced model exportprecision(=<n>): use <n> significant figures for floating point values (in text) for induced model exportzip(=true/false/gzip/xz): whether to zip files for induced model exporttext: show binary formats in textual form for induced model exportheaders(=true/false, or bare for true): include headers in explicit model files for induced model export
-
-exportmatlab: When exporting matrices/vectors/labels/etc., use Matlab format -
-exportrows: When exporting matrices, put a whole row on one line -
-exporttransdot <file>: Export the transition matrix graph to a dot file -
-exporttransdotstates <file>: Export the transition matrix graph to a dot file, with state info -
-exportdot <file>: Export the transition matrix MTBDD to a dot file -
-exportsccs <file>: Compute and export all SCCs of the model -
-exportbsccs <file>: Compute and export all BSCCs of the model -
-exportmecs <file>: Compute and export all maximal end components (MDPs only) -
-exportsteadystate <file>: Export steady-state probabilities to a file -
-exporttransient <file>: Export transient probabilities to a file -
-exportprismconst <file>: Export final PRISM model with expanded constants to a file
Export options
-exportmodelprecision <n>: Export probabilities/rewards with n significant decimal places-noexportheaders: Don't include headers when exporting rewards
Engines and methods
-
-ptamethod <name>: Specify PTA engine (games, digital, backwards) [default: games]Valid options: digital, games, backwards, bw.
-
-transientmethod <name>: CTMC transient analysis method (unif, fau) [default: unif]Valid options: unif, fau.
-
-heuristic <mode>: Automatic choice of engines/settings (none, speed, memory) [default: none]Valid options: none, speed, memory.
Model construction
-fixdl: Automatically put self-loops in deadlock states [default]-nofixdl: Do not automatically put self-loops in deadlock states-noprobchecks: Disable checks on model probabilities/rates-buildall: Build/store all labels and rewards during model construction
Solution methods (linear equations)
-power(or-pow,-pwr): Use the Power method for numerical computation-jacobi(or-jac): Use Jacobi for numerical computation [default]-gaussseidel(or-gs): Use Gauss-Seidel for numerical computation-bgaussseidel(or-bgs): Use Backwards Gauss-Seidel for numerical computation-pgaussseidel(or-pgs): Use Pseudo Gauss-Seidel for numerical computation-bpgaussseidel(or-bpgs): Use Backwards Pseudo Gauss-Seidel for numerical computation-jor: Use JOR for numerical computation-sor: Use SOR for numerical computation-bsor: Use Backwards SOR for numerical computation-psor: Use Pseudo SOR for numerical computation-bpsor: Use Backwards Pseudo SOR for numerical computation-omega <x>: Set over-relaxation parameter (for JOR/SOR/...) [default: 0.9]
Solution methods (MDPs)
-
-gaussseidel(or-gs): Use Gauss-Seidel value iteration for solving MDPs -
-intervaliter[:<options>](or-ii): Use interval iteration to solve MDPs/MCs (see -help -ii)Use interval iteration to solve MDPs/MCs.
If provided, <options> is a comma-separated list of options taken from:
boundmethod(=default/variant-1-coarse/variant-1-fine/variant-2/dsmpi): Select upper bound heuristic for reward computationslower(=<d>): Manually specify lower bound for reward computationsupper(=<d>): Manually specify upper bound for reward computations[no]boundverbose: Verbose output for upper bound computations (default = no)[no]selectmidpoint: Select midpoint between upper and lower as the result (default = yes)[no]monotonicbelow: Enforce monotonicity in iteration from below (default = yes)[no]monotonicabove: Enforce monotonicity in iteration from above (default = yes)[no]checkmonotonic: Check monotonicity, for testing (default = no)
Example: boundmethod=default,upper=3.0,noselectmidpoint,checkmonotonic
Solution method settings
-relative(or-rel): Use relative error for detecting convergence [default]-absolute(or-abs): Use absolute error for detecting convergence-epsilon <x>(or-e): Set value of epsilon (for convergence check) [default: 1e-6]-maxiters <n>: Set max number of iterations [default: 10000]-gridresolution <n>: Set resolution for fixed grid approximation (POMDP) [default: 10]
Model checking
-
-noprob0: Skip precomputation algorithm Prob0 (where optional) -
-noprob1: Skip precomputation algorithm Prob1 (where optional) -
-noprerel: Do not pre-compute/use predecessor relation, e.g. for precomputation -
-nofair: Don't use fairness (for model checking of MDPs) [default] -
-sumroundoff <x>: Set probability sum threshold [default: 1-e5] -
-nossdetect: Disable steady-state detection for CTMC transient computations -
-sccmethod <name>: Specify (symbolic) SCC computation method (xiebeerel, lockstep, sccfind)Valid options: xiebeerel, lockstep, sccfind.
-
-aroptions <string>: Abstraction-refinement engine options string<string> is a comma-separated list of options regarding abstraction-refinement:
- verbose=<n> (or v=<n>) - verbosity level
refine=<where,how>: which states to refine and how
<where> = all, allmax, first, firstmax, last, lastmax <how> = all, val- epsilonref=<x> (or eref=<x>) - epsilon for refinement
- nopre - disable precomputation
pre: use precomputationnoprob0: disable prob0 precomputationnoprob1: disable prob1 precomputationepsilon=<x>: epsilon for numerical convergencemaxref=<n>: maximum number of refinementsopt: use optimisationsnoopt: disable optimisationsexportdot: export dot files for each refinementabove: start numerical soluton from abovebelow: start numerical soluton from below
-
-pathviaautomata: Handle all path formulas via automata constructions -
-nodasimplify: Do not attempt to simplify deterministic automata, acceptance conditions -
-exportadv <file>: Export an adversary from MDP model checking (as a DTMC) -
-exportadvmdp <file>: Export an adversary from MDP model checking (as an MDP) -
-ltl2datool <exec>: Run executable <exec> to convert LTL formulas to deterministic automata -
-ltl2dasyntax <x>: Specify output format for -ltl2datool switch (lbt, spin, spot, rabinizer)Valid options: lbt, spin, spot, rabinizer.
-
-exportiterations: Export vectors for iteration algorithms to file -
-pmaxquotient: For Pmax computations in MDPs, compute in the MEC quotient
Multi-objective model checking
-linprog(or-lp): Use linear programming for MDP solution (explicit engine) and multi-objective model checking-multimaxpoints <n>: Maximal number of corner points for (valiter-based) multi-objective-paretoepsilon <x>: Threshold for Pareto curve approximation-exportpareto <file>: When computing Pareto curves, export points to a file
Output
-verbose(or-v): Verbose mode: print out state lists and probability vectors-extraddinfo: Display extra info about some (MT)BDDs-extrareachinfo: Display extra info about progress of reachability
Sparse, hybrid and MTBDD engines
-nocompact: Switch off "compact" sparse storage schemes-sbl <n>: Set number of levels (for hybrid engine) [default: -1]-sbmax <n>: Set memory limit (KB) (for hybrid engine) [default: 1024]-gsl <n>(or-sorl): Set number of levels for hybrid GS/SOR [default: -1]-gsmax <n>(or-sormax): Set memory limit (KB) for hybrid GS/SOR [default: 1024]-cuddmaxmem <n>: Set max memory for CUDD package, e.g. 125k, 50m, 4g [default: 1g]-cuddepsilon <x>: Set epsilon value for CUDD package [default: 1e-15]-ddsanity: Enable internal sanity checks (causes slow-down)-ddextrastatevars <n>: Set the number of preallocated state vars [default: 20]-ddextraactionvars <n>: Set the number of preallocated action vars [default: 20]
Parametric model checking
-
-param <vals>: Do parametric model checking with parameters (and ranges) <vals> -
-paramprecision <x>: Set max undecided region for parameter synthesis [default: 5/100] -
-paramsplit <name>: Set method to split parameter regions (longest,all) [default: longest]Valid options: longest, all.
-
-parambisim <name>: Set bisimulation minimisation for parameter synthesis (weak,strong,none) [default: weak]Valid options: strong, weak, none.
-
-paramfunction <name>: Set function representation for parameter synthesis (jascached,jas) [default: jascached]Valid options: jascached, jas, dag.
-
-paramelimorder <name>: Set elimination order for parameter synthesis (arb,fw,fwrev,bw,bwrev,rand) [default: bw]Valid options: arb, fw, fwrev, bw, bwrev, rand.
-
-paramrandompoints <n>: Set number of random points to evaluate per region [default: 5] -
-paramsubsumeregions <b>: Subsume adjacent regions during analysis [default: true] -
-paramdagmaxerror <b>: Maximal error probability allowed for DAG function representation [default: 1E-100]
Fast adaptive uniformisation (FAU)
-fauepsilon <x>: Set probability threshold of birth process in FAU [default: 1e-6]-faudelta <x>: Set probability threshold for irrelevant states in FAU [default: 1e-12]-fauarraythreshold <x>: Set threshold when to switch to sparse matrix in FAU [default: 100]-fauintervals <x>: Set number of intervals to divide time intervals into for FAU [default: 1]-fauinitival <x>: Set length of additional initial time interval for FAU [default: 1.0]
Simulation
-
-sim: Use the PRISM simulator to approximate results of model checking -
-simmethod <name>: Specify the method for approximate model checking (ci, aci, apmc, sprt)Valid options: ci, aci, apmc, sprt.
-
-simsamples <n>: Set the number of samples for the simulator (CI/ACI/APMC methods) -
-simconf <x>: Set the confidence parameter for the simulator (CI/ACI/APMC methods) -
-simwidth <x>: Set the interval width for the simulator (CI/ACI methods) -
-simapprox <x>: Set the approximation parameter for the simulator (APMC method) -
-simmanual: Do not use the automated way of deciding whether the variance is null or not -
-simvar <n>: Set the minimum number of samples to know the variance is null or not -
-simmaxrwd <x>: Set the maximum reward -- useful to display the CI/ACI methods progress -
-simpathlen <n>: Set the maximum path length for the simulator
Explicit model files
This page details the plain text file formats used by PRISM for exporting and importing models that have already been constructed, i.e., they comprise an explicit list of states, transitions, etc. making up the model, rather than a high-level model description in the PRISM modelling language. Below, we describe:
- PRISM explicit (.pexp) files
- Transitions (.tra) files
- Transitions (.tra) files (row form)
- Labels (.lab) files
- State rewards (.srew) files
- Transition rewards (.trew) files
- State (.sta) files
The examples are exported from four small PRISM models, which are shown, with diagrams, in the last section, Source PRISM files.
PRISM explicit (.pexp) files
The default for exporting models in textual format from PRISM is to do so in a combined .pexp file, that includes all parts of the model, as described individually in more detail below.
Here is an example, for the (DTMC) PRISM model dtmc.prism:
# Transitions (DTMC)
6 9
0 1 0.5
0 3 0.5
1 0 0.5
1 2 0.25
1 4 0.25
2 5 1
3 3 1
4 4 1
5 2 1

# States
(s)
0:(0)
1:(1)
2:(2)
3:(3)
4:(4)
5:(5)

# Labels
0="init" 1="deadlock"
0: 0

# Reward structure "r"
# State rewards
6 3
0 2
4 1
5 1

# Reward structure "r"
# Transition rewards
6 4
1 0 1
1 2 1
1 4 1
2 5 2
See below for the format of the constituent parts.
Transitions (.tra) files
These contain an explicit list of the transitions making up a probabilistic model, i.e. they are essentially a sparse matrix representation of the transition probability/rate matrix. After an (optional) header line containing the word Transitions and the model type, the first line of the file contains information about the size of the model, then the remaining lines contain information about transitions, one per line.
DTMCs and CTMCs
For Markov chains the initial line takes the form "n m", giving the number of states (n) and the number of transitions (m). The remaining lines are of the form "i j x" or "i j x a", where i and j are the indices of the source state (row) and destination state (column) of the transition, and x is the probability (for a DTMC) or rate (for a CTMC) of the transition. State indices are zero-indexed (i.e. between 0 and n-1). Probability/rate values are written as (positive) floating point numbers (examples: 0.5, .5, 5.6e-6, 1). a is optional and gives the action label for the transition. Action labels can be present for some, all or no transitions.
It is assumed that source states (rows) are in ascending order, but there is no assumption about the ordering of destination states (columns) within the transitions for each source state.
For a DTMC, the probabilities for the outgoing transitions of each state should sum to 1.
Here is an example, for the (DTMC) PRISM model dtmc.prism:
# Transitions (DTMC)
6 9
0 1 0.5
0 3 0.5
1 0 0.5
1 2 0.25
1 4 0.25
2 5 1
3 3 1
4 4 1
5 2 1
and here is one for the (CTMC) PRISM model poll2.prism:
# Transitions (CTMC)
12 22
0 1 0.5
0 2 0.5
0 6 200 loop1a
1 3 0.5
1 7 200 loop1a
2 3 0.5
2 4 200 loop1b
3 5 200 loop1b
4 5 0.5
4 6 1 serve1
5 7 1 serve1
6 7 0.5
6 8 0.5
6 0 200 loop2a
7 9 0.5
7 10 200 loop2b
8 9 0.5
8 2 200 loop2a
9 11 200 loop2b
10 11 0.5
10 0 1 serve2
11 2 1 serve2
MDPs (or PAs)
For MDPs, the format is an extension of the above To clarify terminology: each state of the MDP contains (nondeterministic) choices, each of which is essentially a probability distribution over successor states that we can view as a set of transitions. Optionally, each choice can be labelled with an action.
The first (non-header) line of the file take the form "n c m", giving the number of states (n), the total number of choices (c) and the total number of transitions (m). The remaining lines are of the form "i k j x" or "i k j x a", where i and j are the indices of the source state (row) and destination state (column) of the transition, k is the index of the choice that it belongs to, and x is the probability of the transition. a is optional and gives the action label for the choice of the transition. Action labels can be present for some, all or no states but, in slightly redundant fashion, the action labels, if present, must be the same for all transitions belonging to the same choice.
State indices and choice indices are all zero-indexed. Probability values (as above) are written as (positive) floating point numbers and should sum to 1 for each choice. It is assumed that source states (rows) and choices within states are in ascending order, but there is no assumption about the ordering of destination states (columns) within the transitions for each choice.
Here is an example, for the (MDP) PRISM model mdp.prism, exported without its actions
(-exportmodel mdp.tra:actions=false):
# Transitions (MDP)
4 5 7
0 0 1 1
1 0 2 0.5
1 0 3 0.5
1 1 0 0.7
1 1 1 0.3
2 0 2 1
3 0 3 1
and here is the same model exported with its actions:
# Transitions (MDP)
4 5 7
0 0 1 1 a
1 0 2 0.5 c
1 0 3 0.5 c
1 1 0 0.7 b
1 1 1 0.3 b
2 0 2 1 a
3 0 3 1 a
For LTSs (labelled transition systems), the format is the same as for MDPs,
except that there are no probabilities, so each choice comprises a single transition.
The remaining lines are of the form "i k j" or "i k j a".
Here is the start of the file for the LTS
in Non-probabilistic models:
# Transitions (LTS)
8 14 14
0 0 3 try1
0 1 1 try2
1 0 4 try1
1 1 2 enter2
...
POMDPs
The format of a .tra file for a POMDP is similar to an MDP,
but also contains information about observations.
The initial line of the file takes the form "n c m o", where n, c and m are, as for MDPs, the numbers of states, choices and transitions,
and o is the number of observations.
The lines that list transitions contain an additional integer after the transition probability
(and before the action, if present), giving the (deterministic) observation that is made
when entering the target state of that transition.
It is assumed that these are consistent for all states.
In order to also specify the observation for the initial state,
a dummy transition line of the form - - s - o is used,
giving both the initial state s and its observation o.
An example file is:
# Transitions (POMDP)
10 16 18 4
- - 0 - 0
0 0 1 0.1 1 toss
0 0 2 0.3 1 toss
0 0 3 0.6 1 toss
1 0 4 1 2 guess1
1 1 7 1 3 guess2
1 2 7 1 3 guess3
2 0 8 1 3 guess1
2 1 5 1 2 guess2
2 2 8 1 3 guess3
3 0 9 1 3 guess1
3 1 9 1 3 guess2
3 2 6 1 2 guess3
4 0 4 1 2 loop
5 0 5 1 2 loop
6 0 6 1 2 loop
7 0 7 1 3
8 0 8 1 3
9 0 9 1 3
Transitions (.tra) files (row form)
There is an alternative format for transition matrices (see the rows option for -exportmodel) where transitions for each state/choice are collated on a single line.
Here is the result for the dtmc.prism example from above (a DTMC):
# Transitions (DTMC)
6 9
0 0.5:1 0.5:3
1 0.5:0 0.25:2 0.25:4
2 1:5
3 1:3
4 1:4
5 1:2
for the mdp.prism example (an MDP), without its actions:
# Transitions (MDP)
4 5 7
0 1:1
1 0.5:2 0.5:3
1 0.7:0 0.3:1
2 1:2
3 1:3
and with them:
# Transitions (MDP)
4 5 7
0 1:1 a
1 0.5:2 0.5:3 c
1 0.7:0 0.3:1 b
2 1:2 a
3 1:3 a
Labels (.lab) files
These contain an explicit list of which labels are satisfied in each state.
After a header, showing Labels,
the first line lists the labels, assigning each one an index.
The remaining lines list indices of all states satisfying one or more labels,
followed by a list of the indices of labels that are satisfied in it.
This includes the built-in labels "init" (initial states) and deadlock (deadlock states).
An example is shown below, for mdp.prism, where, for example, both "heads" and "end" are satisfied in state 2.
# Labels
0="init" 1="deadlock" 2="heads" 3="tails" 4="end"
0: 0
2: 2 4
3: 3 4
State rewards (.srew) files
For reward files, the header, gives the name of the reward structure that generated it
and the type of rewards (state or transitions) stored in the file.
For state rewards, the information following this header is an explicit list of the (non-zero) state rewards.
The first line is of the form n m where n is the number of states in the model and m is the number of non-zero state rewards.
The following m lines are of the form i r, denoting that the state reward for state i is r.
For the dtmc.prism (6-state) DTMC example from above, we get rewards in 3 states (0, 4 and 5):
# Reward structure "r"
# State rewards
6 3
0 2
4 1
5 1
Transition rewards (.trew) files
Files containing transition rewards, like those for state rewards, start with a header. The rest of the file is formatted identically to transitions files (see above), except that probabilities/rates are replaced with reward values, and the number of transitions (the last number on the first line) is replaced with the number of non-zero transition rewards.
For the dtmc.prism (6-state) DTMC example from above, we get non-zero transition rewards on 4 transitions:
# Reward structure "r"
# Transition rewards
6 4
1 0 1
1 2 1
1 4 1
2 5 2
And for the mdp.prism (4-state) MDP example, we get non-zero transition rewards on 4 transitions:
# Reward structure "r"
# Transition rewards
4 5 4
1 0 2 6
1 0 3 6
1 1 0 5
1 1 1 5
States (.sta) files
These contain an explicit list of the reachable states of a model. The first (non-header) line is of the form (v1,...,vn), listing the names of all the variables in the model in the order that they appear in the PRISM model. Subsequent lines list the values of the n variables in each state of the model. Each line is of the form i:(x1,...,xn), where i is the index of the state (starting from 0) and x1,...,xn are the values of each variable in the state. States are ordered by their index (and, therefore, given PRISM's default behaviour, lexicographically according to the tuple of variable values).
For the example PRISM model poll2.prism, the states file looks like:
# States
(s,a,s1,s2)
0:(1,0,0,0)
1:(1,0,0,1)
2:(1,0,1,0)
3:(1,0,1,1)
4:(1,1,1,0)
5:(1,1,1,1)
6:(2,0,0,0)
7:(2,0,0,1)
8:(2,0,1,0)
9:(2,0,1,1)
10:(2,1,0,1)
11:(2,1,1,1)
Source PRISM files
The examples above were exported by PRISM from the following models. Each is shown with a diagram of the resulting model, in which states are labelled with their indices, as used in the files above.
dtmc.prism
A DTMC with 6 states and a reward structure "r":
dtmc

module M

s:[0..5];

[] s=0 -> 0.5:(s'=1) + 0.5:(s'=3);
[] s=1 -> 0.5:(s'=0) + 0.25:(s'=2) + 0.25:(s'=4);
[] s=2 -> 1:(s'=5);
[] s=3 -> 1:(s'=3);
[] s=4 -> 1:(s'=4);
[] s=5 -> 1:(s'=2);

endmodule

rewards "r"
	s=0 : 2;
	s>=4 : 1;
	[] s<3 : s;
endrewards
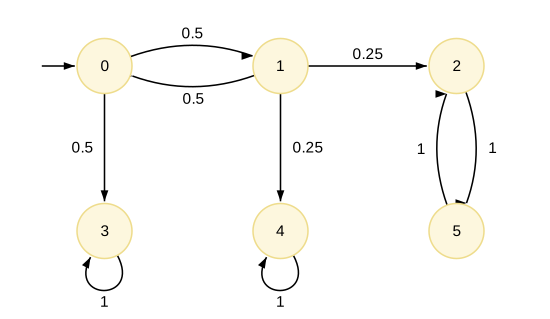
mdp.prism
An MDP with 4 states and 5 choices, labelled with actions, with labels "heads", "tails" and "end",
and a reward structure "r" on actions b and c:
mdp

module M

s:[0..3];

[a] s=0 -> 1:(s'=1);
[b] s=1 -> 0.7:(s'=0) + 0.3:(s'=1);
[c] s=1 -> 0.5:(s'=2) + 0.5:(s'=3);
[a] s=2 -> 1:(s'=2);
[a] s=3 -> 1:(s'=3);

endmodule

label "heads" = s=2;
label "tails" = s=3;
label "end" = s=2|s=3;

rewards "r"
	[b] true : 5;
	[c] true : 6;
endrewards
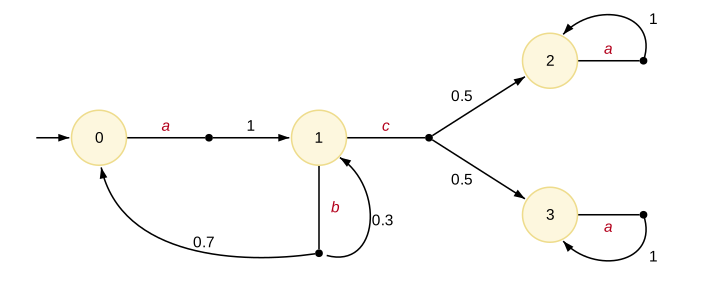
poll2.prism
A CTMC with 12 states: a polling system with two stations (the same as poll2.sm in the prism-examples directory).
The values of its variables in each state are listed in the states file above:
states 0 to 5 have the server at station 1 (s=1), on the left, and states 6 to 11 at station 2, on the right.
// polling example [IT90]
// gxn/dxp 26/01/00

ctmc

const int N = 2;

const double mu		= 1;
const double gamma	= 200;
const double lambda	= mu/N;

module server

	s : [1..2]; // station
	a : [0..1]; // action: 0=polling, 1=serving

	[loop1a] (s=1)&(a=0) -> gamma	: (s'=s+1);
	[loop1b] (s=1)&(a=0) -> gamma	: (a'=1);
	[serve1] (s=1)&(a=1) -> mu		: (s'=s+1)&(a'=0);

	[loop2a] (s=2)&(a=0) -> gamma	: (s'=1);
	[loop2b] (s=2)&(a=0) -> gamma	: (a'=1);
	[serve2] (s=2)&(a=1) -> mu		: (s'=1)&(a'=0);

endmodule

module station1

	s1 : [0..1]; // state of station: 0=empty, 1=full

	[loop1a] (s1=0) -> 1 : (s1'=0);
	[]       (s1=0) -> lambda : (s1'=1);
	[loop1b] (s1=1) -> 1 : (s1'=1);
	[serve1] (s1=1) -> 1 : (s1'=0);

endmodule

// construct further stations through renaming

module station2 = station1 [ s1=s2, loop1a=loop2a, loop1b=loop2b, serve1=serve2 ] endmodule
// (cumulative) rewards

// expected time station 1 is waiting to be served
rewards "waiting"
	s1=1 & !(s=1 & a=1) : 1;
endrewards

// expected number of times station 1 is served
rewards "served"
	[serve1] true : 1;
endrewards
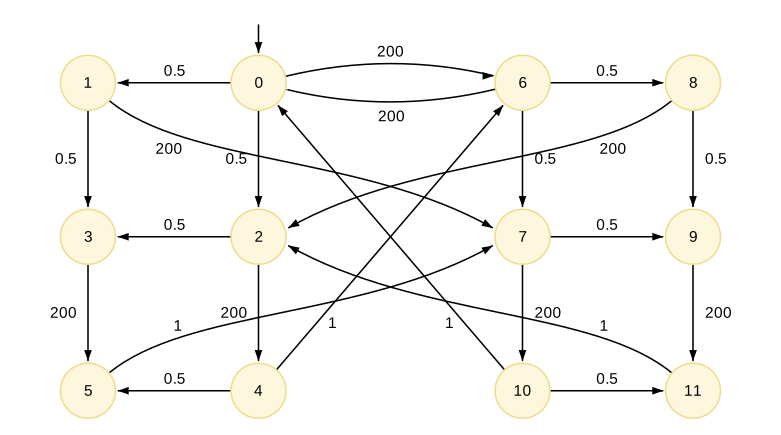
References
- [AD94] R. Alur and D. Dill. A theory of timed automata. Theoretical Computer Science, 126:183-235, 1994.
- [AH99] R. Alur and T. Henzinger. Reactive Modules. Formal Methods in System Design, 15(1):7-48, 1999.
- [ASSB96] A. Aziz, K. Sanwal, V. Singhal and R. Brayton. Verifying Continuous Time Markov Chains. In R. Alur and T. Henzinger, editors, Proc. 8th International Conference on Computer Aided Verification (CAV'96), volume 1102 of LNCS, pages 269-276, Springer, 1996.
- [Bai98] C. Baier. On Algorithmic Verification Methods for Probabilistic Systems. Habilitation thesis, Fakultät für Mathematik & Informatik, Universität Mannheim, 1998.
- [BdA95] A. Bianco and L. de Alfaro. Model Checking of Probabilistic and Nondeterministic Systems. In P. Thiagarajan, editor, Proc. 15th Conference on Foundations of Software Technology and Theoretical Computer Science (FSTTCS'95), volume 1026 of LNCS, pages 499-513, Springer, 1995.
- [BK98] C. Baier and M. Kwiatkowska. Model Checking for a Probabilistic Branching Time Logic with Fairness. Distributed Computing, 11(3):125-155, 1998.
- [BKH99] C. Baier, J.-P. Katoen and H. Hermanns. Approximate Symbolic Model Checking of Continuous-Time Markov Chains. In J. Baeten and S. Mauw, editors, Proc. 10th International Conference on Concurrency Theory (CONCUR'99), volume 1664 of LNCS, pages 146-161, Springer, 1999.
- [BKLPW17] Christel Baier, Joachim Klein, Linda Leuschner, David Parker and Sascha Wunderlich. Ensuring the Reliability of Your Model Checker: Interval Iteration for Markov Decision Processes. In Proc. 28th International Conference on Computer Aided Verification (CAV'17), volume 10426 of LNCS, pages 160-180, Springer, July 2017.
- [CHH+13] Taolue Chen, Ernst Moritz Hahn, Tingting Han, Marta Kwiatkowska, Hongyang Qu and Lijun Zhang. Model Repair for Markov Decision Processes. In Proc. 7th International Symposium on Theoretical Aspects of Software Engineering (TASE'13), pages 85-92, IEEE, July 2013.
- [DHK13] Frits Dannenberg, Ernst Moritz Hahn and Marta Kwiatkowska. Computing Cumulative Rewards using Fast Adaptive Uniformisation. In A. Gupta and T. Henzinger, editors, Proc. 11th International Conference on Computational Methods in Systems Biology (CMSB'13), volume 8130 of LNCS, pages 33-49, Springer, September 2013.
- [FKN+11] Vojtěch Forejt, Marta Kwiatkowska, Gethin Norman, David Parker and Hongyang Qu. Quantitative Multi-Objective Verification for Probabilistic Systems. In P. Abdulla and K. Leino, editors, Proc. 17th International Conference on Tools and Algorithms for the Construction and Analysis of Systems (TACAS'11), volume 6605 of LNCS, pages 112-127, Springer, March 2011.
- [FKNP11] Vojtěch Forejt, Marta Kwiatkowska, Gethin Norman and David Parker. Automated Verification Techniques for Probabilistic Systems. In M. Bernardo and V. Issarny, editors, Formal Methods for Eternal Networked Software Systems (SFM'11), volume 6659 of LNCS, pages 53-113, Springer, June 2011.
- [FKP12] Vojtěch Forejt, Marta Kwiatkowska and David Parker. Pareto Curves for Probabilistic Model Checking. In S. Chakraborty and M. Mukund, editors, Proc. 10th International Symposium on Automated Technology for Verification and Analysis (ATVA'12), volume 7561 of LNCS, pages 317-332, Springer, October 2012.
- [HHZ11] Ernst Moritz Hahn, Tingting Han and Lijun Zhang. Synthesis for PCTL in Parametric Markov Decision Processes. In Proc. 3rd NASA Formal Methods Symposium (NFM'11), volume 6617 of LNCS, Springer, April 2011.
- [HHZ11b] E. M. Hahn, H. Hermanns, and L. Zhang. Probabilistic reachability for parametric Markov models. Software Tools for Technology Transfer, 13(1):3-19, 2011.
- [Hil96] J. Hillston. A Compositional Approach to Performance Modelling. Cambridge University Press, 1996.
- [HJ94] H. Hansson and B. Jonsson. A Logic for Reasoning about Time and Reliability. Formal Aspects of Computing, 6(5):512-535, 1994.
- [HKN+03] Holger Hermanns, Marta Kwiatkowska, Gethin Norman, David Parker and Markus Siegle. On the use of MTBDDs for Performability Analysis and Verification of Stochastic Systems. Journal of Logic and Algebraic Programming: Special Issue on Probabilistic Techniques for the Design and Analysis of Systems, 56:23-67, June 2003.
- [HLMP04] T. Hérault, R. Lassaigne, F. Magniette and S. Peyronnet. Approximate Probabilistic Model Checking. In Proc. 5th International Conference on Verification, Model Checking and Abstract Interpretation (VMCAI'04), volume 2937 of LNCS, pages 307-329, Springer, January 2004.
- [HM14] S. Haddad and B. Monmege. Reachability in MDPs: Refining convergence of value iteration. In 8th International Workshop on Reachability Problems (RP), volume 8762 of LNCS, pages 125-137, Springer, 2014.
- [KNP04b] Marta Kwiatkowska, Gethin Norman and David Parker. Probabilistic Symbolic Model Checking with PRISM: A Hybrid Approach. International Journal on Software Tools for Technology Transfer (STTT), 6(2):128-142, September 2004.
- [KNP07a] Marta Kwiatkowska, Gethin Norman and David Parker. Stochastic Model Checking. In M. Bernardo and J. Hillston, editors, Formal Methods for the Design of Computer, Communication and Software Systems: Performance Evaluation (SFM'07), volume 4486 of LNCS (Tutorial Volume), pages 220-270, Springer, June 2007.
- [KNP09c] Marta Kwiatkowska, Gethin Norman and David Parker. Stochastic Games for Verification of Probabilistic Timed Automata. In J. Ouaknine and F. Vaandrager, editors, Proc. 7th International Conference on Formal Modeling and Analysis of Timed Systems (FORMATS'09), volume 5813 of LNCS, pages 212-227, Springer, September 2009.
- [KNPS06] Marta Kwiatkowska, Gethin Norman, David Parker and Jeremy Sproston. Performance Analysis of Probabilistic Timed Automata using Digital Clocks. Formal Methods in System Design, 29:33-78, August 2006.
- [KNSW07] M. Kwiatkowska, G. Norman, J. Sproston and F. Wang. Symbolic Model Checking for Probabilistic Timed Automata. Information and Computation, 205(7):1027-1077, July 2007.
- [Lov91] W. S. Lovejoy. Computationally Feasible Bounds for Partially Observed Markov Decision Processes. Operations Research, 39(1):162-175, 1991.
- [MWDH10] M. Mateescu, V. Wolf, F. Didier and T. Henzinger. Fast adaptive uniformisation of the chemical master equation. IET Syst Biol, 4(6):441-452, 2010.
- [Nim10] Vincent Nimal. Statistical Approaches for Probabilistic Model Checking. MSc Mini-project Dissertation, Oxford University Computing Laboratory, September 2010.
- [NPS13] Gethin Norman, David Parker and Jeremy Sproston. Model Checking for Probabilistic Timed Automata. Formal Methods in System Design, 43(2):164-190, September 2013.
- [NPZ17] Gethin Norman, David Parker and Xueyi Zou. Verification and Control of Partially Observable Probabilistic Systems. Real-Time Systems, 53(3):354-402, April 2017.
- [Par02] David Parker. Implementation of Symbolic Model Checking for Probabilistic Systems. Ph.D. thesis, University of Birmingham, 2002.
- [Put94] M. Puterman. Markov Decision Processes: Discrete Stochastic Dynamic Programming. John Wiley and Sons, 1994.
- [Seg95] R. Segala. Modelling and Verification of Randomized Distributed Real Time Systems. Ph.D. thesis, Massachusetts Institute of Technology, 1995.
- [Ste94] W. J. Stewart. Introduction to the Numerical Solution of Markov Chains. Princeton, 1994.
- [Str00] M. Strens. A Bayesian Framework for Reinforcement Learning. In Proc. 17th International Conference on Machine Learning (ICML'00), pages 943-950, Morgan Kaufmann, 2000.
- [YS02] H. Younes and R. Simmons. Probabilistic Verification of Discrete Event Systems Using Acceptance Sampling. In E. Brinksma and K. Larsen, editors, Proc. 14th International Conference on Computer Aided Verification (CAV'02), volume 2404 of LNCS, pages 223-235, Springer, 2002.
Frequently asked questions
Answers to frequently asked questions about modelling, properties and memory. For problems installing or running PRISM, see "Troubleshooting".
Contents
- Memory problems: crashes, and running out of memory during model construction, model checking or parsing
- PRISM modelling: model size, variable ordering, and modelling deterministic delays
- PRISM properties: infinite expected rewards, results for several states, and the probability of actions
Memory problems
Click on a question to see its answer.
PRISM crashed or stopped responding. Why?
When PRISM crashes, the most likely cause is that it has run out of memory. Similarly, if PRISM (or the machine you are running it on) becomes very slow or seems to have stopped responding, this is probably because it is using too much of your machine's memory. Probabilistic model checking, much like other formal verification techniques, can be a very resource-intensive process. It is very easy to create a seemingly simple PRISM model that requires a large amount of time and/or memory to construct and analyse. See the other questions on this page for tips on how to avoid this.
The other possibility is that you have found a bug.
If PRISM crashes or freezes whilst not using all/most of the available memory (you can check this with the top command in a Unix/Linux terminal or the Task Manager (via Ctrl-Alt-Delete) on Windows) then please file a bug report.
I ran out of memory. What can I do?
First, note that PRISM's different computation engines and solution methods can vary significantly in performance.
It also helps to establish at what point in PRISM's operation, you ran out of memory. If you are running the command-line version of PRISM then the output from the tool so far should give an indication of this. If using the GUI, check the log tab for this information. If PRISM crashed because of its memory usage, the error message can be helpful. If using the GUI, you may need to start the GUI from the command-line to see any error messages.
The two main steps that PRISM typically has to perform are:
- Model construction (conversion of a PRISM language description to the corresponding probabilistic model)
- Model checking/analysis (processing/analysis of a constructed probabilistic model in order to determine the result of a property or to compute steady-state/transient probabilities)
Memory usage issues for each of these steps are discussed in the questions on model construction and model checking below. In some cases the process performed prior to step 1 (model parsing - reading in a model description in the PRISM language and checking it for correctness) can also be resource intensive. This is discussed under model parsing.
If you are using the simulator to generate approximate model checking results then step 1 (model construction) is not performed and step 2 is carried out very differently. Memory consumption is not usually a problem in this case.
I ran out of memory during model construction. What can I do?
If PRISM has already output this:
Building model (engine:symbolic)...
but there is no line of the form:
Time for model construction: 34.3 seconds.
and then you get an error like this:
CUDD internal error detected, from the following stack trace:
  ...
Error: Out of memory (or other internal error) in the CUDD library.
Tip: Try using the -cuddmaxmem switch to increase the memory available to CUDD.
then PRISM ran out of memory whilst trying to construct the model. With the symbolic engines (MTBDD, hybrid and sparse), model construction is performed using BDDs (binary decision diagrams) and MTBDDs (multi-terminal BDDs), which are implemented in the CUDD library. The first thing to try in this case is to increase the amount of memory available to CUDD. See "CUDD memory" for details of this.
If increasing this memory limit does not resolve the problem, then you will need to consider ways to reduce the size of your model. You can find some tips on this in the PRISM modelling section. Bear in mind also that if you are having to increase the CUDD memory limit too high (e.g. close to the physical memory available on your computer) just for model construction, then it is unlikely that you will have enough memory for subsequent model checking operations.
It is also worth considering the ordering of the modules and variables in your model since this can have a (in some cases dramatic) effect on the size of MTBDD representation of the model. This topic is covered in the "PRISM modelling" section.
With the explicit engine, the model is built in Java, and running out of memory gives an error like this:
Exception in thread "main" java.lang.OutOfMemoryError: Java heap space
In this case, increase the memory available to Java instead (see "Java memory").
I ran out of memory during model checking. What can I do?
If model construction was successfully completed (see the previous question) but model checking was not, there are several things you can try. First of all, if the error message you see is the CUDD one in the previous question,
then it may be worth increasing the memory limit for CUDD (as described there).
If it is a Java OutOfMemoryError, increase the memory available to Java.
However, if PRISM is killed or aborts with no such message,
then increasing these limits probably will not help: PRISM is just trying to allocate more memory than is physically available on your system.
Here are some general tips:
-
Try experimenting with using the different engines in PRISM. Read the section "Computation engines" for details.
-
Look at the detailed output of PRISM for information about memory usage. If you are using the hybrid (or sparse) engine and the limiting factor in terms of memory is creation of the vectors, then you have no choice but to try and reduce the size (number of states) of your model. If you are using the MTBDD engine, it is also well worth considering the variable ordering of your model. Both topics are discussed in the "PRISM modelling" section.
-
Finally, if you can find no way to reduce the size of your model and are happy to consider an approximate (rather than exact) analysis, you may wish to try using PRISM's discrete-event simulation engine for analysis.
I ran out of memory during model parsing. What can I do?
This is a less common problem and will only occur if the actual PRISM language description of your model is very large. This may be the case, for example, if you are automatically generating PRISM models in some way. Errors due to lack of memory during parsing usually look like:
Exception in thread "main" java.lang.OutOfMemoryError: Java heap space
or:
Exception in thread "main" java.lang.StackOverflowError
You can resolve this problem by increasing the memory (for OutOfMemoryError) or the stack size (for StackOverflowError) allocated to Java.
See "Java memory" for details of both.
PRISM modelling
Click on a question to see its answer.
What size models can PRISM handle?
There is no definitive answer to this. Because of PRISM's symbolic implementation, using data structures based on binary decision diagrams (BDDs), its performance can be unpredictable in this respect. There are also several factors that affect performance, including the type of model and property being checked and the engine being used (PRISM has several different engines, which have varying performance).
Having said that, using the default engine in PRISM (the "hybrid" engine), you can normally expect to be able to handle models with up to
How can I reduce the size of my model?
The size of a probabilistic model (i.e. the number of states/transitions) is critical to the efficiency of performing probabilistic model checking on it, since both the time and memory required to do so are often proportional to the model size. Unfortunately, it is very easy to create models that are extremely large. Below are a few general tips for reducing model size.
-
Look for variables that have unnecessarily large ranges and try to reduce them. Even if your model needs large variables, it is generally a good strategy to first get a smaller version building successfully and then scale it up afterwards.
-
Similarly, can you (if only temporarily) reduce the number of modules/components of your model? Start with the smallest number of components possible and then add others one by one.
-
Do you have any inter-dependencies between variables? For example, perhaps you have some variables which are simply functions of other variables of the model. Even if these are convenient for modelling, they can be replaced with formulas or labels, which do not contribute to the state space.
-
Do any variables include more detail than is necessary for the model? Perhaps this can be exploited in order to reduce the number of variables in your model.
-
More generally, are any aspects of the model not relevant to the properties that you are interested in? If so, start with a simpler, more abstract version of the model and then add more details if possible.
How can I choose a good variable ordering?
Because PRISM is a symbolic model checker, the amount of memory required to store the probabilistic model can vary (sometimes unpredictably) according to several factors. One example is the order in which the variables of your model appear in the model file. In general, there is no definitive answer to what the best ordering is but the following heuristics are a good guide.
- Variables which are closely related should appear close together
- Variables which are related to most or all other variables should appear near the start of the ordering
Variables x and y are "related" if, for example, the value of one has an effect on how the other changes (e.g. (y'=x+1)) or if both appear together in an expression (e.g. a guard).
These heuristics also apply to the ordering of modules within the model file.
For technical details about variable ordering issues, see e.g. section 8 of [HKN+03] or section 4.1.2 of [Par02].
How can I add deterministic time delays to a CTMC model?
All delays in a CTMC need to be modelled as exponential distributions. This is what makes them efficient to analyse. If you included a transition whose delay was deterministic, i.e. which always occurred after exactly the same delay, the model would no longer be a CTMC.
One solution to this, if your model requires such a delay, is to approximate a deterministic delay with an Erlang distribution (a special case of a phase-type distribution). See for example this PRISM model:
ctmc

const int k;
const double mean = 10;

module trigger

	i : [1..k+1];

	[]   i < k -> k/mean : (i'=i+1);
	[go] i = k -> k/mean : (i'=i+1);

endmodule

module main

	x : [0..1];

	[go] x=0 -> (x'=1);

endmodule
In the model, the go-labelled action occurs after a delay with an Erlang distribution with mean mean and shape k. The special case of k=1 is just an exponential distribution. The graph below shows the probability distribution of the delay, i.e. of P=? [ F<=T x=1 ] for different values of k.
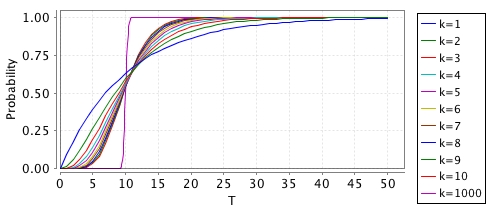
There is an obvious trade-off here between the accuracy (how close it is to modelling a deterministic time delay) and the resulting blow-up in the size of the model that you add this to. For k=1000, you can see that the shape is quite "deterministic" but this would increase your model size by a factor of ~1000.
PRISM properties
Click on a question to see its answer.
Why is my expected reward infinite?
This most commonly occurs when you are computing the expected reward that is accumulated up until some target set of states is reached ("reachability reward" properties). For example:
R=? [ F "end" ]
As mentioned earlier, this kind of property returns infinity if "end" is not eventually reached with probability 1. This is a choice that we made when designing the property specification language. Often, it is reasonable to assume that, if a path continues indefinitely without reaching a goal state, then reward will continue to be accumulated infinitely often (this would usually be true when modelling time as a reward structure, for instance). If there is a non-zero probability of not reaching the target (i.e. the probability of reaching it is less than 1), we would then expect the overall expected reward to be infinite.
You can check whether the probability of reaching the target is 1 with a property like:
P=? [ F "end" ]
A similar situation arises with models that contain nondeterminism, such as MDPs. The maximum expected reward to reach a target is finite if and only if the minimum probability of reaching the target is 1. Conversely, the minimum expected reward is finite if and only if the maximum probability is 1.
How do I check if a property is true in multiple (or all) states?
Consider a typical Boolean-valued PRISM property, such as:
P<0.01 [ F "error" ]
i.e. "the probability of reaching a state labelled with "error" is less than 0.01". By default, when model checking this query, PRISM will report the result of this property for the initial state of the model, i.e. whether, starting from the initial state, the probability of reaching "error" is below 0.01.
To check whether the above property is true for, say, all (reachable) states satisfying the label "safe", you should use filters, as
illustrated below:
filter(forall, P<0.01 [ F "error" ], "safe")
If you want to check whether the property is true for all reachable states, you can use either of the following two (equivalent) properties:
filter(forall, P<0.01 [ F "error" ], true)
filter(forall, P<0.01 [ F "error" ])
Equivalently, you can use implication (=>) inside the filter, as in this example:
filter(forall, "safe" => P<0.01 [ F "error" ])
How do I compute the probability of an action occurring?
PRISM's property specification language is primarily state-based, e.g. you can compute the probability of reaching a state that satisfies the label "error":
P=? [ F "error" ]
So how do you compute the probability of some action b occurring? You need to make a small change to your model. The cleanest way to do this is to add a small module that changes state when the action occurs, e.g.:
module checker

    q : [0..1] init 0;

    [b] q=0 -> (q'=1);
    [b] q=1 -> (q'=1);

endmodule
You can determine the probability of action b occurring in the model with the property:
P=? [ F q=1 ]
By design, the module above will not affect the behaviour (timing, probability, etc.) of your model at all, so all other properties will remain unchanged. This is true for any of the model types that PRISM supports. It may, though, lead to a (hopefully small) increase in total model size.
You can also modify the property above to compute, for example, the probability of b occurring within T time-units or the expected time until b occurs:
P=? [ F<=T q=1 ]
R{"time"}=? [ F q=1 ]
(where a constant T or reward structure time have been added to the model, as appropriate).